
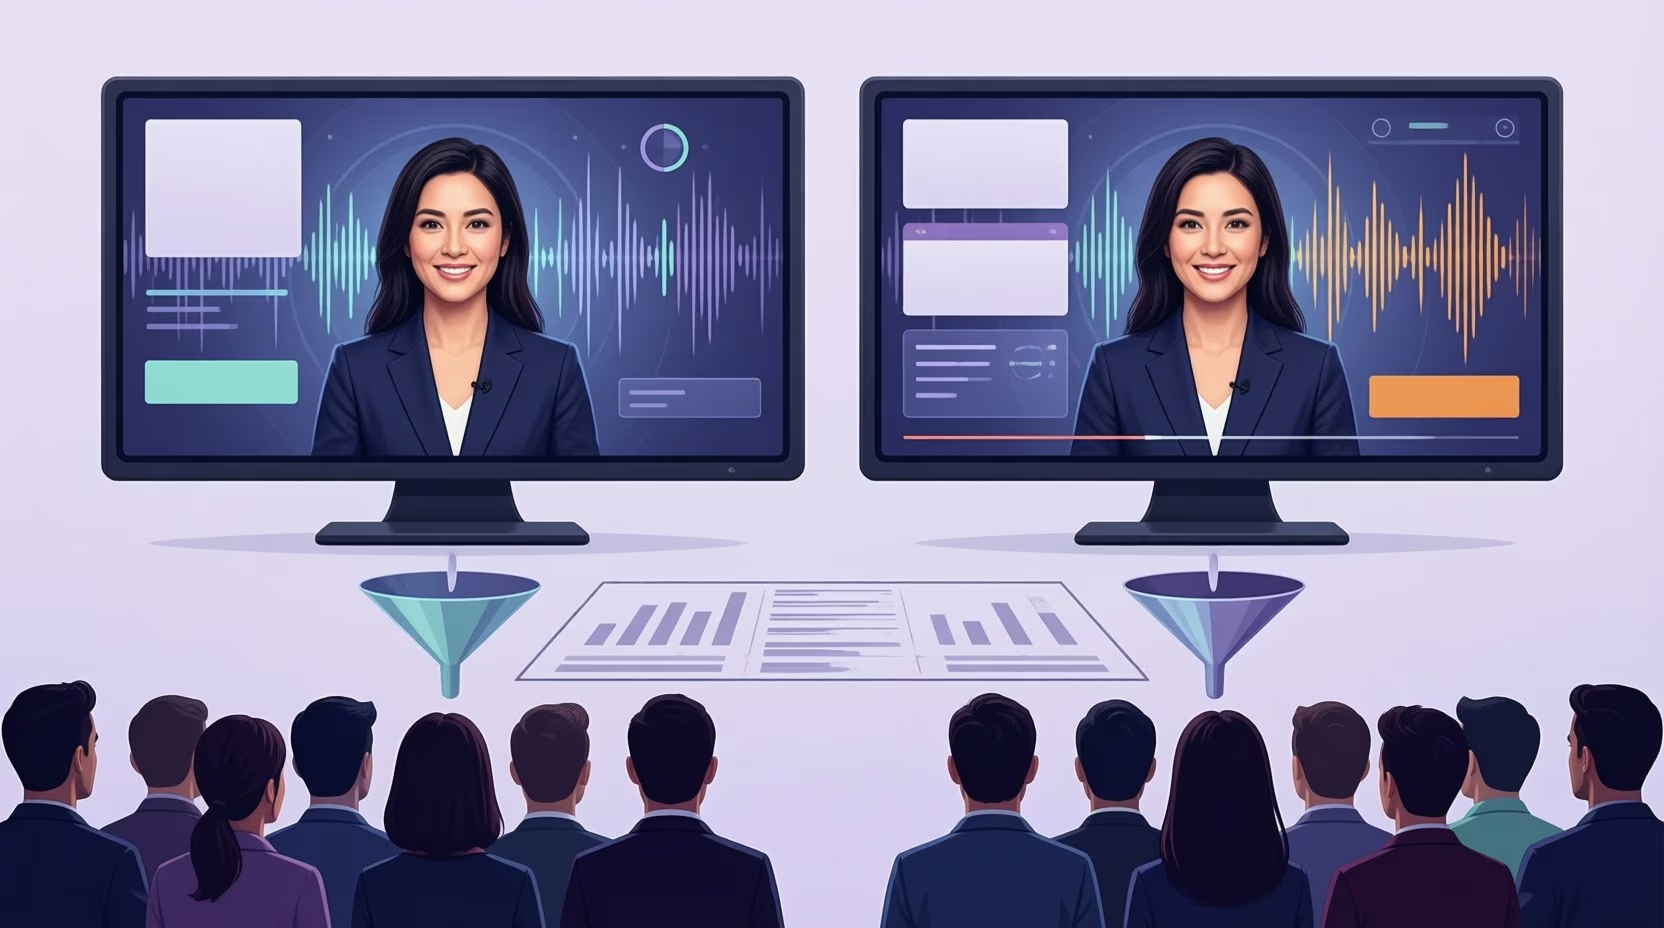
Video sits at the center of most paid and organic acquisition funnels, and generative tools now handle a large share of production work. For analytics and growth teams, an AI Avatar Generator separates the visual presenter, the script, and the vocal delivery into independent parameters that you can modify one at a time and test against funnel metrics.
- Why AI Avatar Video Changes Creative Testing Economics
- Choosing Variables for a Talking Avatar Experiment
- Presenter Style as a Test Variable
- Voice, Delivery and Language Variants
- Tools That Make Avatar Variants Controllable
- Sample Size and Significance in Plain Terms
- Video Metrics That Matter for AI Spokesperson Tests
- Instrumenting Video Experiments for Attribution
- Common Mistakes in Avatar Video Analysis
- A Six-Step Process for Talking Avatar A/B Tests
- Governance for AI Video Avatars and Talking Photos
- FAQ
- How many variants should an AI avatar video test include?
- Which metric should decide a presenter-style test?
- Do AI avatar results transfer across channels?
- Is AI disclosure required for avatar videos?
- Turning AI Avatar Generator Output Into Evidence
To run measurable video experiments with an AI avatar generator, the core rule is to change only one creative variable per test, such as the opening hook, presenter style, or voice delivery, while holding all other settings constant. Judge each test on the funnel metric closest to that variable after reaching a pre-calculated sample size.
- Change one variable per test: modify only the hook, presenter style, delivery, or call to action in each test arm.
- Match the metric to the variable: judge hooks on 3-second view rates and lock sample sizes before launch.
- Instrument and log every variant: tag UTM content strings, keep holdout groups, and record likeness consent and AI disclosure.
The numbers on adoption are clear enough. According to Wyzowl’s State of Video Marketing 2026, 91% of businesses use video as a marketing tool, and 63% of video marketers use AI tools to create or edit video (Piktochart). What the survey cannot tell any single team is which version of a video works for its own audience. That question belongs to experiment design, instrumentation, and careful analysis. Sources: evidence
This guide treats talking-avatar video as a controlled experimental input. Below, we cover how to prepare clean source assets, isolate single creative variables, select primary funnel metrics, wire UTM tracking into a business intelligence stack, and maintain governance logs across campaigns.
Pre-Experiment Setup Checklist
Before launching a split test, standardize your asset generation workflow so technical glitches do not contaminate creative comparisons. Most avatar tools follow a three-step creation flow where you upload or choose a character, add text or audio while directing expressions, and generate the rendered video (Kling AI). When preparing your baseline control video, follow these setup steps:
More Read
- Upload a clean, single-person source photo: Bad source photos are a frequent cause of rendering failures, including group photos where models try to merge multiple faces or mirror selfies where a phone obscures the jawline (TrendAvatar). Avoid blurry, low-resolution, or noisy inputs so the model replicates facial features and audio cleanly (LipSynthesis).
- Select a baseline presenter style and motion profile: Pick your control avatar style and verify that blink rate and subtle head movement look natural, since focusing only on mouth shapes while ignoring eye behavior leaves the presenter looking stiff (FontsGenerator).
- Add the approved script or audio track: Input your control text or voice recording and check brand pronunciation and gestures frame by frame before exporting (AI Avatar Tech Blog).
- Log all fixed parameters: Record the source image filename, avatar style, voice profile, video dimensions, and duration in your experiment tracker before generating the test variants.
Why AI Avatar Video Changes Creative Testing Economics
Traditional video testing is expensive. Every new variant means another shoot, another edit, and often another round of talent fees. Teams in that position tend to test two finished ads against each other, and when one wins, nobody can say why.
An AI avatar video generator lowers the marginal effort of producing creative variations. When creating a new test arm only requires editing a script line or swapping the visual style of a presenter, a team can generate multiple controlled versions from a single project file. That workflow makes it practical to isolate one element per experiment and accumulate longitudinal data across campaigns.
Cheap variants also create a risk. When production is no longer the bottleneck, teams can flood a campaign with versions and end up with a pile of underpowered results. The discipline has to move from the edit suite to the experiment plan.
Choosing Variables for a Talking Avatar Experiment
The core rule is simple: change one thing per test. If the hook, the voice, and the presenter all change at once, a winning variant tells you nothing about which change mattered.
Most talking avatar experiments fall into a handful of variable families. The table below maps each one to example variants and the metric that should decide the test.
| Variable | Example variants | Primary metric |
|---|---|---|
| Script hook | Question opener vs. bold claim vs. problem statement | Hook rate (3-second view rate) |
| Presenter style | Photorealistic vs. illustrated vs. 3D mascot | Hook rate, then watch-through |
| Voice and delivery | Calm and measured vs. energetic, with or without pauses | Watch-through / completion rate |
| Language | Original language vs. localized version | Conversion rate within each market |
| Length | 15 seconds vs. 30 seconds vs. 60 seconds | Completion rate and CTR |
| Call to action | “Start a trial” vs. “See pricing” vs. “Book a demo” | Click-through rate, then conversion |
The primary metric should sit close to the variable being tested. A new hook mostly affects whether people keep watching past the first few seconds, so judging it on final conversions adds noise from everything that happens later in the funnel.
Presenter Style as a Test Variable
Presenter style is one of the more interesting variables because it used to be fixed. A brand hired a spokesperson or chose an animated character, and that decision held for the campaign. With an AI Avatar Generator, the same underlying script can be fronted by different visual treatments, so the choice between a realistic digital presenter and a stylized mascot becomes an empirical question.
Keep everything else identical when testing style. Same script, same voice track, same length, same thumbnail logic, same placement. Otherwise a style “win” may simply reflect a different first frame.
Voice, Delivery and Language Variants
Delivery is easy to overlook because it is hard to describe precisely. Pace, pauses, and emotional tone shape how a message lands, and lip sync AI makes it possible to change the audio while keeping the visual presenter constant. That separation lets a team test delivery as its own variable.
Language tests deserve their own structure. A localized version should be compared against the original within the same market, not against performance in a different country, because audiences, costs, and seasonality differ across regions.
Tools That Make Avatar Variants Controllable
Running clean experiments depends on how precisely a tool lets you hold some elements constant while changing others. The Fish Audio AI Avatar Generator is one example of how that can work in practice. When a workflow lets you pair a consistent source image with either a typed script or uploaded audio while adjusting visual style or line-by-line delivery independently, you can swap presenter treatments or pacing deliberately between two variants without altering the rest of the video.
While interactive hiring avatars adapt in real time, ad experimentation relies on the opposite mechanism: locking down pre-rendered variables so every viewer in a test cohort sees the exact same visual and vocal stimulus.
Sample Size and Significance in Plain Terms
Statistical significance answers one question: how likely is it that the gap between two variants is just random noise? A result that looks large after a few hundred impressions can vanish after a few thousand. The smaller the real difference, the more traffic you need to detect it.
Three inputs drive the required sample size. The first is the baseline rate, such as a current CTR. The second is the smallest lift worth detecting, often called the minimum detectable effect. The third is the confidence level the team is willing to accept. Free online calculators turn those three inputs into a target number of users or impressions per variant.
The most common mistake is checking results repeatedly and stopping as soon as one variant looks like a winner. Evan Miller’s widely cited explainer, How Not To Run an A/B Test, puts it directly: “Repeated significance testing always increases the rate of false positives.” The fix he recommends is equally direct: “Decide on a sample size in advance and wait until the experiment is over.”
For AI video avatars, this matters because variants are cheap. A team that splits a modest budget across eight versions may never reach a reliable sample on any of them. Fewer arms, each with enough traffic, usually produce more usable answers.
Video Metrics That Matter for AI Spokesperson Tests
Each stage of a video funnel has its own metric, and each one answers a different question about an AI spokesperson video. Because ad networks define view thresholds differently, confirm your platform’s exact event definitions before comparing numbers across channels.
- Hook rate (3-second view rate): Used here as our operational definition for the share of impressions that turn into at least three seconds of viewing (verify the exact view threshold in your ad platform before comparing runs). It reflects the opening frame, the first line, and the presenter’s immediate appeal.
- Watch-through or completion rate: Defined operationally here as the share of viewers who reach a set quartile, such as 50% or 100% of the video (confirm how your hosting or ad platform logs quartile events before running cross-campaign roll-ups). It shows whether the script and delivery hold attention.
- Click-through rate (CTR): Clicks divided by impressions. It reflects the call to action and how well the video sets it up.
- Conversion rate: The share of visitors from the video who complete the target action, such as a sign-up or purchase.
- Cost per acquisition (CPA): Total spend divided by conversions. It is the metric finance teams care about, but it carries noise from every upstream stage.
A sensible pattern is to judge each test on the metric closest to its variable, then confirm that the winner does not hurt downstream numbers. A hook that lifts the 3-second view rate but lowers conversions is attracting the wrong attention.
Instrumenting Video Experiments for Attribution
Clean data starts before a variant goes live. The goal is that every click, view, and conversion can be traced back to one specific version of one specific video, and that those records roll up neatly in a BI tool.
UTM Parameters and Variant Naming
UTM parameters carry variant identity from the ad platform to the analytics stack. A common approach uses utm_campaign for the campaign, utm_content for the specific variant, and keeps utm_source and utm_medium consistent with existing reporting conventions.
Variant names should follow a fixed pattern that a query can parse. One workable format joins the test ID, the variable, and the value with underscores, for example T07_style_mascot and T07_style_photo. When names stay consistent, a dashboard can group every presenter-style test across campaigns and show cumulative evidence instead of isolated results.
Holdout Groups and Incrementality
Platform-reported conversions often include people who would have converted anyway. A holdout group, a slice of the target audience that sees no video or a neutral control, gives a baseline for measuring true incremental lift. Holdouts reduce the volume of reach in the short term, but they make attribution claims far easier to defend in a budget review.
Common Mistakes in Avatar Video Analysis
Even with good instrumentation, several analysis errors recur in AI video avatar programs. Watch for five specific pitfalls when reviewing test data: peeking early, testing multiple variables simultaneously, ignoring novelty decay, mixing audience temperatures, and shifting ad budgets mid-run.
- Peeking early. Stopping a test the moment a variant pulls ahead inflates false positives. Fix the sample size first and wait.
- Testing too many variables at once. If the presenter, script, and CTA all change, the result cannot be attributed to any one of them.
- Ignoring novelty effects. A new presenter style may perform well simply because it looks different from previous ads. Running the test long enough, or rechecking a winner after a few weeks, helps separate novelty from durable preference.
- Mixing audiences. Comparing a variant shown to warm retargeting traffic against one shown to cold prospects measures audience quality, not creative quality. Randomize within the same audience.
- Changing budgets mid-test. Shifting spend between arms while the test runs can change how an ad platform delivers each variant and bias the results.
A Six-Step Process for Talking Avatar A/B Tests
The steps below turn the ideas above into a repeatable routine. By standardizing how your team writes hypotheses, sizes traffic, generates variants, tags URLs, monitors delivery, and archives outcomes, you ensure that individual campaign tests compound into reliable institutional knowledge.
- Write a hypothesis. State the variable, the expected direction, and the primary metric, for example “a question hook will raise the 3-second view rate versus a bold claim.”
- Size the test. Use the baseline rate and minimum detectable effect to set a target sample per variant, and limit the number of arms to what the budget can support.
- Produce controlled variants. Change only the chosen variable and log every setting that stays fixed.
- Instrument before launch. Apply UTM parameters, the naming convention, and a holdout group where incrementality matters.
- Run to completion. Avoid decisions until the planned sample is reached, and keep budgets steady across arms.
- Record and roll up. Add the result to the variant log and the BI dashboard so the next test builds on it.
Governance for AI Video Avatars and Talking Photos
Testing at scale raises governance questions that a data team is well placed to handle. Protecting your experimentation program requires three core operational controls: documented consent for real likenesses, a standardized internal AI disclosure label across all variants, and a central configuration log.
Consent for real likenesses. Any variant built from a real person’s photo, including a talking photo of an employee or a customer, should rest on documented, written consent that covers the intended uses and channels. Consent records belong alongside the creative assets, not in someone’s inbox.
AI disclosure. Labeling synthetic media is a sensible internal default for every avatar experiment. Applying a clear disclosure policy the exact same way to every variant also keeps disclosure from becoming an accidental test variable while you verify current platform policies.
A variant log. Every variant should have a record of its source image, style, script version, voice settings, language, length, CTA, launch date, and approval. The log supports audits and makes it possible to reproduce a winning version months later. It also helps teams avoid re-testing ideas that already lost, which is a common source of wasted spend. For related thinking on structured testing in short-form social formats, see SmartData Collective’s piece on how AI is changing Instagram Reel marketing.
FAQ
The questions below address the most common operational decisions data and marketing teams face when sizing talking-avatar split tests, selecting primary evaluation metrics, validating results across ad networks, and setting internal disclosure standards for synthetic video assets.
How many variants should an AI avatar video test include?
Most AI avatar video tests give clearer answers with two to four variants. The right number depends on traffic and budget, because each variant needs enough impressions to reach the planned sample size.
Which metric should decide a presenter-style test?
Hook rate is usually the best primary metric, since presenter style mainly affects whether people keep watching in the first seconds. Watch-through and conversion should be checked as guardrails.
Do AI avatar results transfer across channels?
Not reliably. Viewing behavior differs by platform and placement, so AI avatar test results from one channel should be retested before a winning variant is rolled out on another channel.
Is AI disclosure required for avatar videos?
Applying a consistent internal disclosure standard across all avatar variants is the safest default. Verify current policies on each ad network before launch so every test arm follows the exact same labeling format.
Turning AI Avatar Generator Output Into Evidence
AI avatar tools make variants cheap, but they do not make conclusions cheap. The value comes from treating each video as a structured experiment with a clear hypothesis, a fixed sample size, consistent naming, and a variant log that feeds the BI layer. For creative testing, the bottleneck has usually been production cost, and that is the part these tools remove.
Teams that pair an AI Avatar Generator with disciplined measurement can build a growing body of evidence about which hooks, presenters, voices, and calls to action work for their audiences, while keeping human review, consent, and disclosure in place for every version that runs.