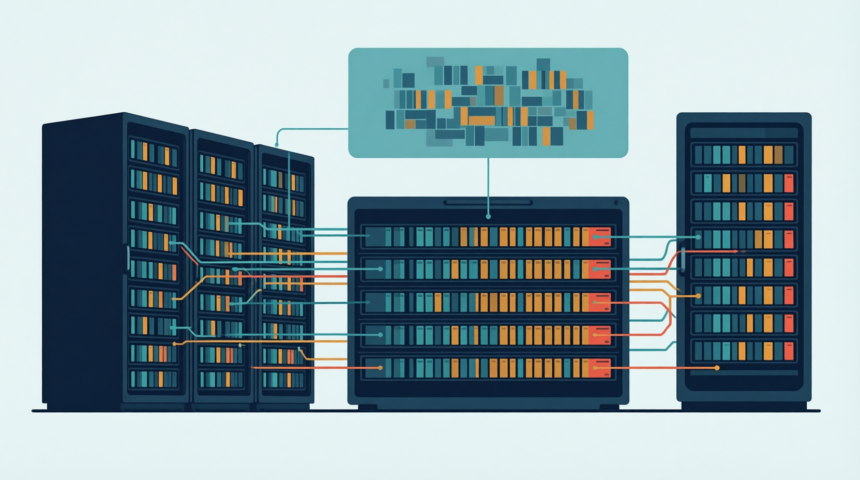
The various online reports about the end of Hadoop as a big data framework bring to mind Mark Twain’s notable quote about the reports of his demise being an exaggeration. Hadoop is very much alive, and numerous organizations continue to make it a key component of their big data and analytics initiatives.
A newer big data framework, Apache Spark, has been described as a possible replacement for Hadoop. Some
view Spark as being more accessible and powerful than the older framework, and therefore more suitable for emerging big data and analytics projects.
The fact is, rather than being a replacement for Hadoop, Spark can serve as a complement to it, and Hadoop can remain a viable component of big data strategies. Spark can either run on top of Hadoop, leveraging its cluster manager and underlying storage, or separately from the framework, integrating with alternative cluster managers and storage platforms.
Hadoop now includes the YARN cluster manager, which the Apache Software Foundation refers to as MapReduce 2.0, or a complete overhaul of MapReduce. While Hadoop MapReduce can be used effectively for working with data types such as log files and static batch processes, other processing tasks can be assigned to different processing engines such as Spark). YARN would handle the management and allocation of cluster resources.
Organizations can integrate Hadoop with Spark for a number of purposes. One is for cluster administration and another is data management including business continuity.
While Spark is a general-purpose data processing engine that is suitable for a variety of projects, it’s not currently designed to handle the data management and cluster administration functions associated with running data process and analysis workloads at scale. Hadoop and its associated projects can effectively handle these tasks, however.
By integrating Spark with Hadoop, organizations can leverage many of the Hadoop capabilities that production environments require, such as YARN resource manager, which handles scheduling tasks across available nodes in the cluster; the Hadoop Distributed File System (or MapR-FS), which stores data when the cluster runs out of free memory and which also stores historical data when Spark isn’t running; and the disaster recovery capabilities that are inherent with Hadoop.
Furthermore, Hadoop provides enhanced data security, which is critical for production workloads, especially in heavily regulated industries such as financial services and healthcare; and a distributed data platform, which enables Spark workloads to be deployed on available resources anywhere in a distributed cluster, without the need to manually allocate and track individual tasks.
When it comes to the benefits of using these two platforms together, it’s by no means a one-way street; Spark can certainly add value to Hadoop as well. For example, Spark’s machine learning module can provide capabilities that are not easily exploited in Hadoop without the use of Spark.
The original design goal of the newer framework, to allow fast in-memory processing of large data volumes, is a key contribution to the capabilities of a Hadoop cluster.
There is no doubt that newer big data frameworks such as Spark are gaining momentum. By the beginning of 2014 Spark had become one of the Apache Software Foundation’s top-level projects and today is one of its most active projects.
As of early 2015, surveys were showing that more than 500 organizations were using Spark in production, according to the foundation. These include Amazon, eBay, NASA, Yahoo!, IBM and many other entities. Many organizations are running Spark on clusters of thousands of nodes, the foundation says, and the largest known cluster has some 8,000 nodes. In terms of data size, Spark has been shown to work well up to petabytes, it says.
But as pointed out earlier, none of this means the end of Hadoop, and industry research bears this out. According to a June 2015 report by market research firm MarketAnalysis.com, the Hadoop market is forecast to grow at a compound annual growth rate (CAGR) of 58%, surpassing $1 billion by 2020.
Hadoop has become “an integral part of almost any commercially available big data solution and de-facto industry standard for business intelligence (BI),” the report notes. More and more organizations are gravitating toward Hadoop and the functionality that it offers, the report says.
Among the interesting trends that have emerged in the Hadoop market in recent years, it says, are the shift from batch processing to online processing; the emergence of MapReduce alternatives such as Spark, Storm and DataTorrent; in-house Hadoop development and deployment; the growth of the Internet of Things (IoT) and all the data it will bring; and the emergence of niche companies focused on enhancing Hadoop features and functionality.
Despite some setbacks, “there are indications that Hadoop is here to stay and grow, though the rapid growth period is still a few years ahead,” the study says.
IT and business executives would be wise to consider that the two big data frameworks, Hadoop and Spark, can work hand in hand to give organizations even greater value from their big data endeavors.
Explore more of Spark’s benefits with the free interactive ebook: Getting Started with Spark: From Inception to Production, by James A. Scott.