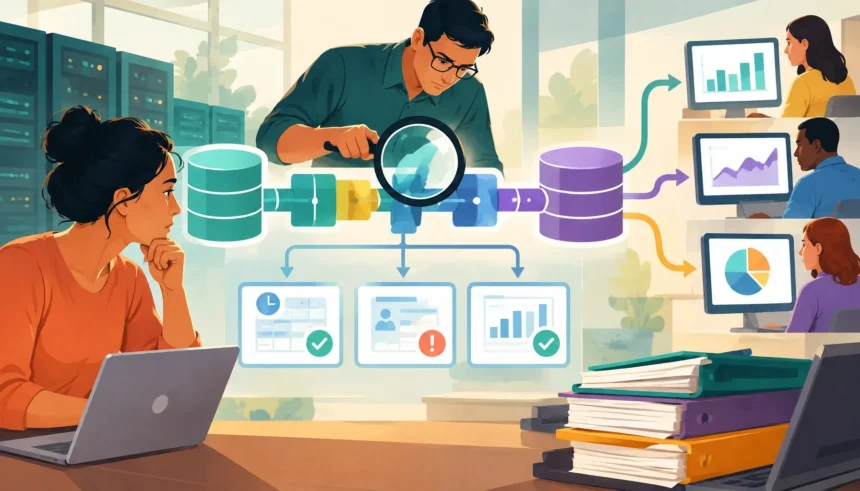
A data platform rarely announces that its design has stopped working. What usually happens is less dramatic: engineers keep it running with patches. A job gets retried, a filter gets added, a table gets rebuilt, and a dashboard gets updated to match. Each fix makes sense on its own. The trouble is that each one pushes the problem a step further downstream, where it lands on someone else.
- Follow a change through the system
- When a successful run produces unreliable data
- Copies solve local problems and create shared ones
- When technical debt starts making decisions for the team
- FAQ
- How do I know my data architecture needs an outside review?
- What should a data architecture review answer?
- Make the review answer a decision
An outside data architecture review is warranted when routine changes break downstream reports, jobs succeed while loading incomplete records, or departments maintain conflicting copies of core metrics. Scoping the audit around one concrete change traces where hidden assumptions, missing schema contracts, and unowned transformations cause systemic drift.
That drift says more about the platform than the age of its tools or the count of failed jobs. When a new data source threatens existing reports, when analysts keep private versions of the same metric because they no longer trust the shared one, and when a critical transformation is understood by exactly one person, the system has likely outgrown the design it started with. The hard part is telling whether these are separate operational issues or symptoms of the same early decisions. An architecture review is meant to answer that exact question.
Teams that want an outside view usually look for a review that covers more than code. Some data engineering consulting firms scope it as a system audit of the technology stack, data quality, and pipeline codebase, with the most critical issues handled first.
Source: https://sysgears.com/solution/data-engineering-consulting/
Follow a change through the system

Consider a subscription company adding a second billing provider. The new integration sends customer and invoice records into the data warehouse. The ingestion job runs, but the provider uses different names for subscription statuses. The transformation maps familiar values and leaves the new ones blank.
The first symptom appears in a churn report. An engineer adds a mapping for the missing statuses. Yet the finance dashboard uses a separate model with its own status logic, so its revenue totals still disagree. The team fixes that model too. A month later, a source update changes the meaning of one status, and the two mappings diverge again.
This is a useful moment to look beyond the failing report. The issue may involve several connected design gaps: no agreed definition for a subscription’s status, no clear owner for the shared customer data, and no process for checking how source changes affect downstream consumers.
A schema contract can make expected fields and behaviors explicit. It also establishes how teams handle changes: which additions are safe, which require consumer updates, and how consumers learn about a breaking change. The contract must be checked as part of the workflow to have practical value. A document that isn’t tested or consulted won’t prevent a silent change from breaking a report.
Streaming systems make timing especially tricky because producers and consumers get updated separately. Adding an optional field is generally easier to accommodate than changing an existing field’s type or meaning, though consumers may still reject unknown fields. Google Cloud’s guidance on upgrading streaming pipelines describes the planning required to manage schema mutations without disrupting downstream systems.
An outside review can trace a small number of key data flows from source to use. For the billing example, that means examining ingestion code alongside status definitions, transformations, report dependencies, and the process for communicating changes. The goal is to find where an assumption became an invisible interface.
When a successful run produces unreliable data
The billing pipeline may now finish without failures, but that doesn’t prove its output is complete or usable. A job can succeed while processing only part of a source, loading stale records, or accepting values that downstream models don’t understand.
Retries illustrate the distinction. In a typical operational scenario, they help recover from temporary network failures, yet they don’t guarantee safe recovery from partial writes. If a job writes some records before timing out, rerunning it may duplicate those records unless the operation is idempotent or otherwise handles duplicates. Adding a cleanup step can work, though it often shifts the burden to downstream models and obscures the original failure.
A review should ask how the pipeline behaves after an interruption. Can it resume from a reliable checkpoint? Are malformed records isolated for investigation? Do alerts identify whether the problem is a timeout, a schema change, or a data quality failure? Those decisions depend on the workload. A daily batch import and a low-latency event stream don’t need identical recovery strategies.
Execution status also needs to be paired with measures of data health. A team might monitor freshness for inventory data or track the proportion of billing records with an unknown status. Google Cloud’s Dataflow guidance describes measuring correctness with metrics over an appropriate time window. The useful measure depends on what consumers need; “the job completed” is rarely enough to define success.
If teams can’t tell whether a recurring problem is a source issue, a recovery weakness, or an invalid assumption in a transformation, an external assessment can connect incidents that have been handled as isolated tickets, uncovering hidden risks before they become expensive problems.
Copies solve local problems and create shared ones
Within the same company, finance and customer success may each build a customer table suited to their particular work. Finance needs invoice-level detail, while customer success needs an account view. Separate datasets are reasonable here if their definitions and owners are clear.
Problems arise when downstream teams treat both tables as authoritative. Each may use a different rule for merging duplicate accounts or deciding whether a subscription is active. A leadership report that joins them can show conflicting business intelligence customer counts, while analysts spend hours reconciling spreadsheets to explain the difference.
In many organizations, these turn into data silos when copies become operational sources that other systems depend on, yet no one is responsible for keeping them aligned. The solution isn’t necessarily to consolidate every dataset into one central model. Centralizing all decisions can slow domain teams and force unrelated use cases into the same structure. Instead, define which data product owns which meaning, how consumers find it, and what guarantees it provides.
A data catalog or lineage tool lets teams discover datasets and see dependencies for themselves. It can’t settle a disagreement about the meaning of “active customer,” assign an owner, or keep two copies synchronized by itself. Microsoft’s lakehouse guidance similarly distinguishes temporary copies from copies that downstream products rely on and that can drift out of sync, a problem that accelerates semantic drift in organizational data.
The outside reviewer should look at how data is actually used instead of simply counting duplicated tables. A throwaway extract for analysis differs from a copy powering a monthly financial report. The appropriate fix might include retiring one dataset, documenting separate definitions, and establishing a supported interface between domains.
When technical debt starts making decisions for the team
Some shortcuts are sensible when a system is small. As an illustrative example, a single transformation is easy to operate when there is one billing provider and one report. That setup becomes much harder to justify when every integration requires edits to the same job, changes need approval from one busy engineer, or a fix for one consumer breaks another.
That is technical debt with a measurable effect. It limits how safely and quickly the team can change the system. Splitting a large transformation into smaller models can make it easier to test and isolate failures, though more components also mean more interfaces and dependencies to maintain. The right design reduces the cost of changes the team actually makes. It doesn’t maximize the number of services or tools.
An assessment should connect proposed changes to evidence. If engineers spend hours tracing failures because lineage is missing, improving lineage for critical datasets is an obvious step. If deployments repeatedly introduce invalid statuses, source-level tests can catch the issue earlier instead of later. In dbt, for instance, data tests check assumptions involving uniqueness, non-null values, and referential integrity. They verify stated conditions, though they still can’t decide whether the business definition behind a metric can be fully trusted.
The same discipline applies to large architectural proposals. Moving to a data mesh may help organizations where domain teams can own data products and follow shared governance standards. It also requires the skills and operating model to support that ownership. Google Cloud’s data mesh guidance describes the potential for domain autonomy alongside the capabilities it requires. A new architecture pattern isn’t a substitute for clear responsibility.
FAQ
How do I know my data architecture needs an outside review?
Your platform needs an outside review when routine source changes break downstream reports, pipelines complete without errors while producing incomplete or duplicated records, departments maintain conflicting copies of core tables, or a single complex transformation slows down every new integration.
What should a data architecture review answer?
A data architecture review should answer a specific operational decision by tracing real data flows from source to report. It identifies whether recurring incidents stem from missing schema contracts, weak recovery checkpoints, unowned dataset copies, or tightly coupled transformations, and defines who will maintain the fix.
Make the review answer a decision
Frame the review around a specific change the team struggles to make. If adding the second billing provider put finance reports at risk, bring the incident notes, the transformation code, and a diagram of the data flow if one exists. Include someone who uses those reports as well. They can clarify which discrepancies affect decisions and which are merely cosmetic.
The reviewer can trace a status value from the provider through the models and into the reports. At each step, the team checks what the value means, where it gets mapped, and whether a test or alert would catch a mismatch. Separate what the logs and code show from assumptions about where the problem began. That gives the team a solid basis for deciding where the mapping belongs and who will maintain it.
The review may point to a change in recovery logic, a shared definition, or an ownership gap. It might also show that the existing design handles the work adequately and simply needs better monitoring. Each recommendation should name the problem it addresses, who will act on it, and what result will indicate that the change helped.
| Review Area | Operational Symptom | Underlying Design Gap | Review Deliverable |
|---|---|---|---|
| Change Propagation | Adding a new provider breaks churn and finance reports | Missing schema contracts and unowned status definitions | Explicit schema contracts and consumer update rules |
| Pipeline Reliability | Jobs succeed but load incomplete, stale, or duplicated rows | Non-idempotent retries and lack of checkpointing | Idempotent recovery logic paired with data health metrics |
| Dataset Copies | Department tables produce conflicting customer counts | Unmanaged copies acting as operational sources | Clear domain ownership and defined interfaces |
| Technical Debt | Every new integration edits one monolithic transformation | High coupling and missing source-level data tests | Modularized models and targeted lineage or dbt tests |