Amazon is a big data giant, which is why I want to look at the company in my second post of my series on how specific organisations use big data.
- How Amazon turns customer data into recommendations
- Predictive shipping, inventory, and fulfilment
- Customer service depends on usable customer records
- AWS tools for big data processing and real-time analysis
- The original AWS service list in context
- Real-time stream processing
- Lakehouse access and transactional data
- How Amazon’s Big Data Architecture Continues to Scale
- Frequently Asked Questions
Amazon uses big data to recommend products, predict buying habits, improve inventory management, and support customer service. Purchase and browsing histories help make shopping more relevant, while operational data supports fulfilment decisions. Through AWS, Amazon also sells data processing and analytics services that other companies can use for their own workloads.
We all know that Amazon pioneered e-commerce in many ways, but possibly one of its greatest innovations was the personalized recommendation system – which, of course, is built on the big data it gathers from its millions of customer transactions. Psychologists speak about the power of suggestion – put something that someone might like in front of them and they may well be overcome by a burning desire to buy it – regardless of whether or not it will fulfil any real need.
This is of course how impulse advertising has always worked – but instead of a scattergun approach, Amazon used their customer data and honed its system into a high powered, laser-sighted sniper rifle. Or at least that is the plan – they don’t seem to get it completely right yet. I have had some very strange recommendations from Amazon.
How Amazon turns customer data into recommendations
Amazon’s recommendation system uses customer transactions and browsing history to suggest products a shopper may want. In retail analytics, the primary distinction is between casual browsing interest and an actual verified purchase. Suggestions can bring relevant products into view, but an irrelevant recommendation can still appear even when plenty of customer data exists.
An important factor to consider when looking at Amazon is how commercial its big data is, compared to those of other companies that deal with data on a comparable scale. Unlike, say, Facebook – which might know an awful lot about which movies you like or who your friends are – much of Amazon’s data on us relates to how we spend hard cash.
A purchase gives a retailer a different signal from a page visit. Someone may browse a product repeatedly without buying, or buy a gift that says little about their own preferences. Analytics systems must keep those events distinguishable when evaluating algorithmic recommendations. Treating every customer interaction as uniform interest distorts predictive modeling and degrades recommendation relevance.
More Read
Industry analyses of Amazon’s recommendation engine attribute significant revenue to targeted customer suggestions, demonstrating how predictive analytics directly impacts the retail bottom line.
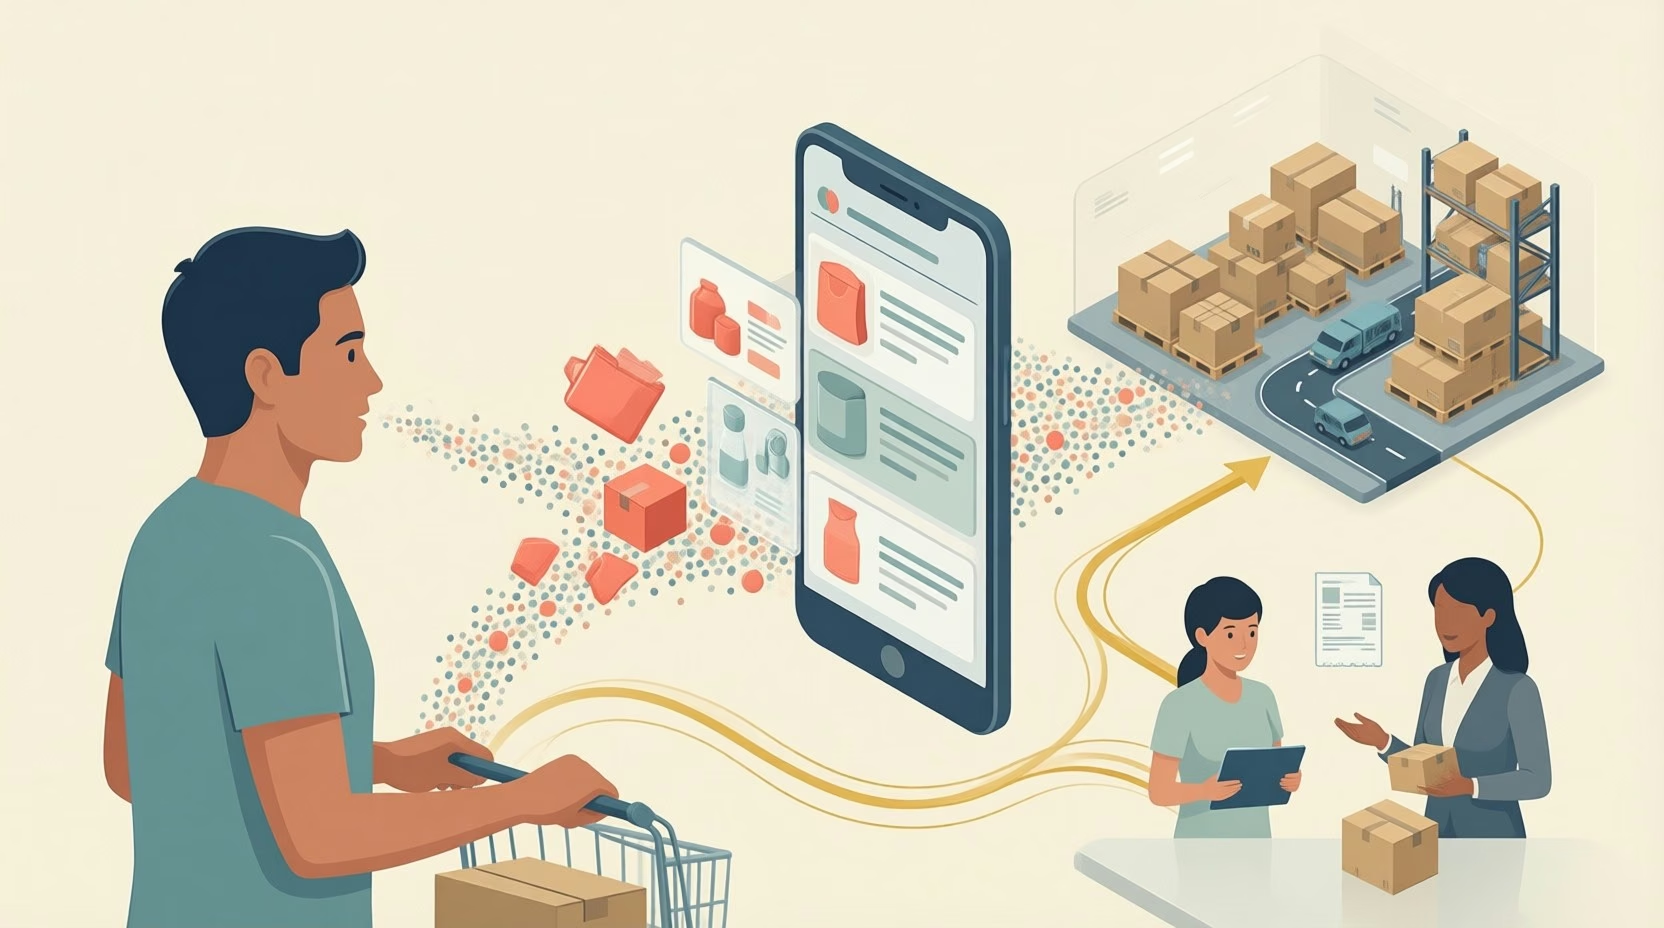
The commercial appeal is straightforward. A recommendation can put a relevant item in front of someone who is already shopping, without making that person run another search. Yet a click alone does not confirm whether a suggestion converted. Recording displayed recommendations and resulting orders separately clarifies where browsing ends without an order.
Amazon big data analytics also extends into advertising. The original article described adverts driven by Amazon’s platform appearing on other sites, bringing Amazon into competition for marketers’ budgets. That advertising business should be distinguished from AWS: access to cloud analytics services does not, by itself, establish access to Amazon’s retail customer records.
Predictive shipping, inventory, and fulfilment
Amazon uses customer data to predict buying habits and improve inventory management. In warehouse operations, the central question is whether forecast demand matches available physical stock. The predictive despatch patent discussed in the original article describes an anticipated shipping approach, while Amazon’s published fulfilment examples document specific uses of AI and machine learning.
As I’ve previously mentioned, Amazon obtained a patent on a system designed to ship goods to us before we have even decided to buy them – predictive despatch – you can read more about that here. This was a development discussed in the original 2014 article. A patent describes an invention; it does not establish how widely a shipping process has been deployed.
The underlying planning problem remains useful to examine. A retailer can predict interest in a product and still have the wrong quantity available where customers want it. When evaluating demand forecasts, comparing predictions with orders and available inventory for the same product, location, and period prevents regional shortages. A company-wide sales total can hide a local stock shortage.
Amazon’s own account of AI and machine learning in its fulfilment centres describes Amazon Monitron, Amazon SageMaker, and the Automated Tote Retriever. These examples extend the discussion beyond product suggestions on a website to the work of running fulfilment operations. They also provide a more concrete operational reference than assuming every predictive shipping idea became standard practice.
Effective operational reporting keeps forecast accuracy and fulfilment performance distinct. A correct demand estimate does not explain why an order arrived late, and an on-time delivery does not prove the inventory forecast was accurate. Trace an exception back through the order and stock records before changing the prediction model. Otherwise, organizations risk adjusting a forecasting model when the underlying discrepancy sits in inventory records.
Customer service depends on usable customer records
Amazon has also incorporated big data analysis into its customer service operations. Customer records give service teams context for a purchase and the problems associated with it. In customer support operations, the deciding factor is whether a representative can connect the customer’s enquiry to the relevant order without reconstructing the history manually.
Its purchase of shoe retailer Zappos is often cited as a key element in this. Since its founding, Zappos had earned a fantastic reputation for its customer service and was often held up as a world leader in this respect. Amazon acquired Zappos in 2009. The acquisition belongs in the historical account, but it does not establish which customer-data systems the companies share today.
Keep the distinction between service analysis and sales analysis visible. A customer contacting support about an item has expressed a problem, which is different from showing interest in buying it again. Preserving that context when preparing customer transaction records for recommendations prevents skewed models. Otherwise, repeated support interactions can be mistaken for enthusiasm about the product.
AWS tools for big data processing and real-time analysis
Amazon Web Services offers cloud-based computing and big data analysis on an enterprise scale. For companies using these services, processing speed and access to data shape the workload choice. Streaming addresses incoming events, while warehouse and lakehouse services support analytical access across stored data. Available AWS capabilities should be distinguished from Amazon’s internal retail deployments.
This allows companies which need to run highly processor-intensive procedures to rent computing time without setting up their own data processing centres. Whether that is cheaper depends on the workload and how it is operated. The original article’s blanket claim that rented computing is far cheaper should not be used as a budget assumption.
The original AWS service list in context
The 2014 article listed Redshift for data warehousing, Elastic Map Reduce for hosted Hadoop processing, S3, Glacier for archival storage, and Kinesis for real-time stream processing. That is a historical snapshot of the services discussed at publication. The original description of S3 as a database running Amazon’s physical warehousing operations is not retained here.
Finally, it is worth mentioning the public data sets that Amazon hosts, and allows analysis of, through Amazon Web Services. The original article highlighted the Human Genome Project, NASA’s Earth science datasets, and US census data. Before planning a workload around a public dataset, check its current location and terms, along with any charges associated with running the analysis.
Real-time stream processing
Kinesis is a real-time stream processing service designed to aid analysis of high-volume data streams. It is no longer a recent addition to the AWS service list. AWS’s explanation of big data describes how demand for faster time-to-insight encouraged frameworks and services such as Apache Spark, Apache Kafka, and Amazon Kinesis to support streaming data processing.
Real-time processing also creates a different operational question from analysing yesterday’s completed orders. What should happen when an expected event has not arrived? Keep that behaviour explicit in tests, and check how the analytical output changes when records arrive late. These are evaluation checkpoints for your implementation, not a description of Amazon’s private recommendation pipeline.
Lakehouse access and transactional data
The next generation of Amazon SageMaker is built on an open data lakehouse architecture. AWS’s analytics overview describes unified access to data lakes and data warehouses on AWS, as well as federated sources such as Google BigQuery and Snowflake. This expands the available analytical access beyond the separate service descriptions in the original article.
AWS also documents transactional data access through zero-ETL and SageMaker Lakehouse. The example brings data from Amazon RDS and Amazon Aurora into Redshift using zero-ETL integrations, with access through the SageMaker Lakehouse Federated Catalog. It describes a concrete route from operational records to analytical processing.
These AWS capabilities explain what Amazon makes available to customers. They do not establish that every Amazon retail workload uses the same lakehouse arrangement, or that a particular service powers every recommendation. Keep that boundary clear when using Amazon as an example for your own architecture decisions.
Amazon has grown far beyond its original inception as an online bookshop, and much of this is due to its enthusiastic adoption of big data principles.
Bernard Marr, SmartDataCollectiveHow Amazon’s Big Data Architecture Continues to Scale
Amazon’s use of big data connects customer activity with recommendations, inventory planning, and service decisions. Connecting predictive signals to verifiable customer orders ensures data initiatives yield measurable business performance. More frequent processing is useful when the resulting recommendation or stock decision reflects the customer’s actual purchase history.
Check more The Big Data Guru columns.
Frequently Asked Questions
How is big data used in Amazon?
Amazon uses big data to personalize product recommendations, predict buying habits, plan inventory, optimize logistics, and support customer service. Purchase and browsing histories help identify products shoppers may want, while demand forecasts inform stock planning. Through Amazon Web Services (AWS), it also provides tools that other organizations can use to store, process, and analyze large datasets.
Who are the big 3 cloud providers?
The “big three” cloud providers are Amazon Web Services (AWS), Microsoft Azure, and Google Cloud. All three offer cloud computing, storage, databases, and analytics services that organizations can use to process big data without operating all the underlying infrastructure themselves.