
Synthetic data gives engineering teams an on-demand sandbox to build and stress-test machine learning algorithms without scraping millions of live web pages. Yet artificial records cannot replace ground truth. Without real web observations anchored in actual user behavior, market shifts, and messy edge cases, predictive models rapidly drift away from operational reality. High-performing machine learning teams rely on both: real web data anchors what is happening right now, while synthetic data generation lets teams simulate extreme edge conditions and scale up training data without prohibitive manual labeling costs.
In this guide, we evaluate synthetic and real web data for AI and ML projects, comparing their operational tradeoffs, limitations, and collection methods across production pipelines.
Synthetic Data vs Real Web Data: Comparison
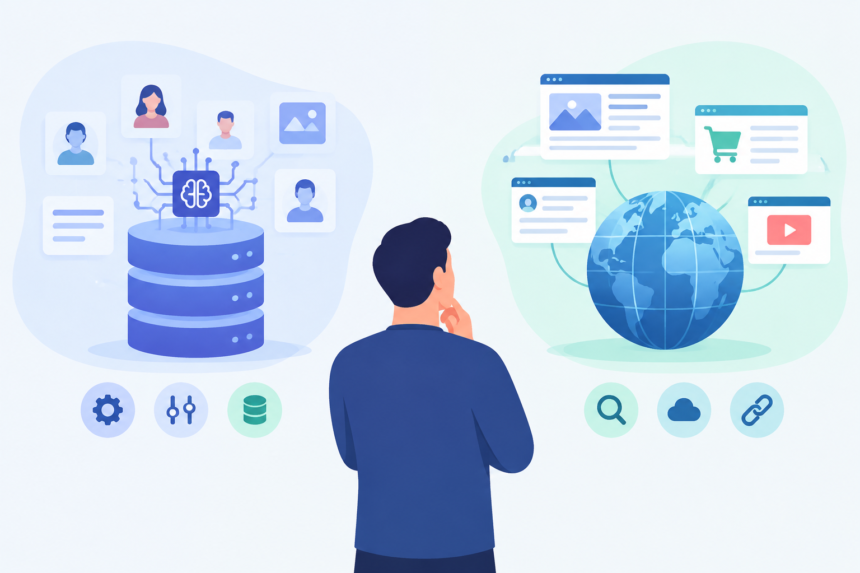
When collecting data for machine learning, most companies treat synthetic records and web data as interchangeable options for filling a dataset. For a production business system, separating them by functional role produces far better outcomes. They solve different engineering problems.
Real web records capture observable events. They document what actually happened, where, and when. An enterprise pipeline ingesting live web data can log an e-commerce price drop on Amazon, track sudden hiring sprees across job boards, or flag unexpected shifts in buyer sentiment. In contrast, artificially generated data provides an experimental testing ground where engineers adjust parameters to see how an algorithm responds.
You can simulate spikes in card-not-present fraud or test inventory limits under simulated logistics chokepoints. Even so, any generated price or user behavior remains an assumption rather than an observed fact. Modeling assumptions carry risk when customer habits change.
These two data types also operate on different timelines. A real record carries a concrete observation timestamp. A synthetic record has a generation timestamp, but its actual distribution depends entirely on its source training sample. If that baseline is six months stale, generating ten million new rows today simply magnifies yesterday’s market.
The most reliable operating model combines both approaches in a closed feedback loop. Live web data detects shifts in the wild. Teams then use that fresh signal for targeted data augmentation, manufacturing synthetic corner cases around the new pattern. Finally, engineers validate the retrained model against new, unmanipulated real-world inputs to verify it holds up in production.
As synthetic content spreads across the public internet, the primary bottleneck in big data engineering is no longer raw volume, but verified provenance. Advantage belongs to organizations with fast feedback loops connecting web changes, model updates, and live outcomes. Understanding different types of online data for your data strategy prevents teams from treating synthetic simulations as empirical ground truth.
Limitations of Synthetic Data for AI Training
Synthetic training data carries three direct operational risks: metric illusion, distorted event distribution, and unverified causality. When models train on machine-generated records, they optimize for the generator’s internal patterns rather than actual market behavior, creating production failures that lab benchmarks miss.
A generator produces subtle mathematical artifacts. When a model trains and evaluates on data from that same generator, it learns those artificial artifacts rather than genuine market mechanics. A high accuracy score on a synthetic test set often reflects compatibility with the generator rather than readiness for live traffic.
In a July 2024 study published in Nature, researchers led by Ilia Shumailov showed that training generative models recursively on model-produced content triggers model collapse. Over successive generations, statistical tail events vanish and the model’s output degenerates into repetitive, low-variance noise.
The generator also controls event frequency. While manufacturing thousands of rare fraud or inventory stockout examples helps an algorithm recognize anomalous signatures, it artificially skews the base rate. In production, that distortion leads to a surge of false positives and wasted manual reviews. Synthetic data shows what an anomaly looks like, but it cannot establish how often that anomaly actually happens.
Causality presents another major hurdle. A synthetic table might show that lowering a product price by 10% increases sales by 30%. That synthetic correlation might simply echo unmodeled holiday promotions or supply shortages present in the seed data. Acting on that assumption in a dynamic market turns an unverified statistical correlation into an expensive pricing blunder.
Because of this, curating a synthetic dataset directly encodes your business logic. By selecting which scenarios to oversample and which to suppress, your data team decides which failure modes the model will penalize most heavily.
Synthetic data isn’t a substitute for market reality. It’s a testing ground to see where your models break before real customers find out.
Bernard Marr, Founder of Bernard Marr & Co.Synthetic data remains valuable for stress-testing edge cases and balancing sparse classes, but relying on it as your sole training foundation blinds models to shifting consumer behavior.
How to Collect Real Web Data
Collecting real web data requires choosing between four established acquisition channels depending on your latency needs, governance standards, and engineering capacity: open public repositories, third-party commercial datasets, direct API integrations, and automated custom web scrapers.
- Using open datasets.
Public repositories like data.gov and Eurostat offer free access to official registries, economic indicators, and academic baselines. While convenient for initial benchmarking, teams must scrutinize license terms, field completeness, and refresh cadences. Stale open records frequently derail production systems.
According to an enterprise data management study by Gartner, organizations will abandon 60% of AI projects unsupported by AI-ready data through 2026. Clean, audited source data is a hard prerequisite for reliable machine learning.
- Purchasing a ready-made dataset.
Commercial vendors sell packaged point-in-time snapshots and historical archives, often available through recurring feeds. This allows engineering teams to deploy prototypes rapidly. However, your team cannot modify the underlying schemas or collection windows, which often leaves critical proprietary signals out of your models.
- Connecting to an API or data feed.
Direct APIs deliver structured JSON or Parquet feeds without the overhead of parsing raw HTML. While reliable, enterprise rate limits and payload quotas can restrict your ingestion velocity. Upstream endpoint changes can also break downstream feature pipelines without warning.
- Develop your own web scraper.
Building automated pipelines with headless browser frameworks like Playwright or distributed extractors like Scrapy gives your team complete control over your intake. You define target domains, schema definitions, and crawling cadence. Dedicated tooling can solve operational roadblocks such as Cloudflare bot challenges, IP rate limiting, and dynamic JavaScript rendering.
For specialized ai data extraction workflows, many enterprises rely on managed web scraping partners. An outside provider manages proxy rotation, handles schema drift when target sites change layout, and delivers clean records directly into your data warehouse. You configure the exact data points and delivery schedules your models demand without diverting in-house engineering sprints.
Most mature data organizations do not rely on a single channel. A pragmatic enterprise strategy might blend a commercial historical dataset for initial weights, official APIs for hourly pricing, and custom scrapers to capture niche competitor catalogs.
Wrapping up
The line dividing real web records from synthetically generated data is not a simple choice between truth and fabrication. A synthetic record derives from mathematical distributions, prompt constraints, or simulation rules; it models an imagined scenario. A real web record captures what was observable in the external world at a given second, even if the underlying web page contained user errors or automated spam.
Context dictates utility. An AI-generated review on an e-commerce site constitutes genuine real-world observation if your goal is analyzing automated spam patterns in search results. That same review is useless if you are evaluating actual customer sentiment about product durability. Similarly, a scraped retail price reflects what an e-commerce platform served to a specific IP address in Chicago, not a universal benchmark across the entire retail economy.
Looking ahead, successful enterprise AI initiatives will not choose between real and synthetic data. Competitive advantage belongs to teams that connect both into an agile pipeline: using live web data to detect ground-truth market dynamics, deploying synthetic records to explore edge cases safely, and verifying every deployment against real user behavior.