We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Python and Productivity
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Uncategorized > Python and Productivity
Uncategorized

Python and Productivity

Editor SDC
Editor SDC
6 Min Read
Python and Productivity
Illustrative image generated with OpenAI gpt-image-1.
SHARE

One of the main benefits of programmability is the ability to extend and automate SPSS Statistics capabilities. I’d like to tell you the story of a recent extension effort: the SPSSINC TURF command and dialog.

TURF analysis is Total Unduplicated Reach and Frequency. It is a common technique in market research. Suppose you have a survey about sports viewing popularity. It asks about football, soccer, baseball, basketball, hockey, and other sports. You would like to know how to reach the most viewers with no more than three sports.

You could tabulate with FREQUENCIES the positive responses to each sport. But this doesn’t answer the question, because the audiences will overlap. You would like to know the highest reach of combinations of up to three sports eliminating the overlap.

Calculating the TURF requires finding the set union for all combinations up to a certain size of positive responses to the sports and then presenting the best of those combinations. That is a computationally demanding task that grows explosively as the number of questions increases, but it is conceptually simple.
More Read

Social Media: Making It Measure Up
Data Visualizations: The Tip of the Iceberg of Understanding
IBM Drops $1B for Merge Healthcare
My Thoughts on the “Washington’s Tech Titans” List
Monitoring a System

SPSS Statistics does not have a built-in way to do this, so I set out to create an extension command implemented in Python for it: SPSSINC TURF. First, I decided to work with transposed data and the built-in set algebra capabilities of Python. I pass the question dataset and create a set for each question listing the case numbers that have positive responses. That’s just a few lines of code.

The trickier part was figuring out how to manage all the set union calculations. It’s a set of tree structures for which a little bit of recursion boils the work down to a few lines of code. My first try was getting clumsy, so I went out for a bike ride for a few hours and came back with the algorithm worked out in my head. I believe in the left-brain, right-brain approach: study something intensively; then relax or do something different, and things are much clearer when you return to the subject.

Putting this together, I finished the code, but I was worried that this task would be so computationally demanding that it would be too slow to be useful. As it turned out, though, the approach I took, heavily leveraging Python sets and some other features, runs amazingly fast. And although the sets have to fit in memory, it seems to handle pretty large problems.

I went on to create a dialog box interface using the Version 17 Custom Dialog Builder and extension command syntax using the extension mechanism, which requires a small xml file to define the syntax and uses our extension.py module to handle that interface.

So, what sort of effort did this take? Less than one day, including the bike ride. How much more productive could you be? Taking advantage of the combination of Python and SPSS together along with the CDB and other tools reduced this task to about 225 lines of code plus the dialog and xml.

I posted this to SPSS Developer Central, where it can be downloaded for free. It is written for SPSS Statistics 17, but it will work with version 16 (not including the dialog) with a small change documented in the readme file. One competing product that does this as a main feature sells for a 4-figure price.

The original version posted had a subset of the features I had thought about doing. I wanted to see what interest there might be. Within a few days I had received and implemented a few enhancement requests. By getting the first version out to the world, it was easier to see what additional features users might want. Again, higher productivity by not implementing things that would probably not be used. But maybe I’ll do more later.

This experience is typical of many programmability projects, in my experience. Big results for small amounts of work. Of course, I’ve done this a lot, so I know all the tools and how to approach a problem. Programmability definitely requires an investment in learning the technology, but it’s hard to beat the ROI.
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is workload-by-workload decision-making for cloud migration, where s
Which Workloads Should Move to the Cloud?
Cloud Computing Exclusive IT
Flat editorial illustration: The article positions data governance as a strategic board-level concern rather than a purely techni
Why Data Governance Is Becoming a Board-Level Business Priority
Big Data Exclusive Policy and Governance
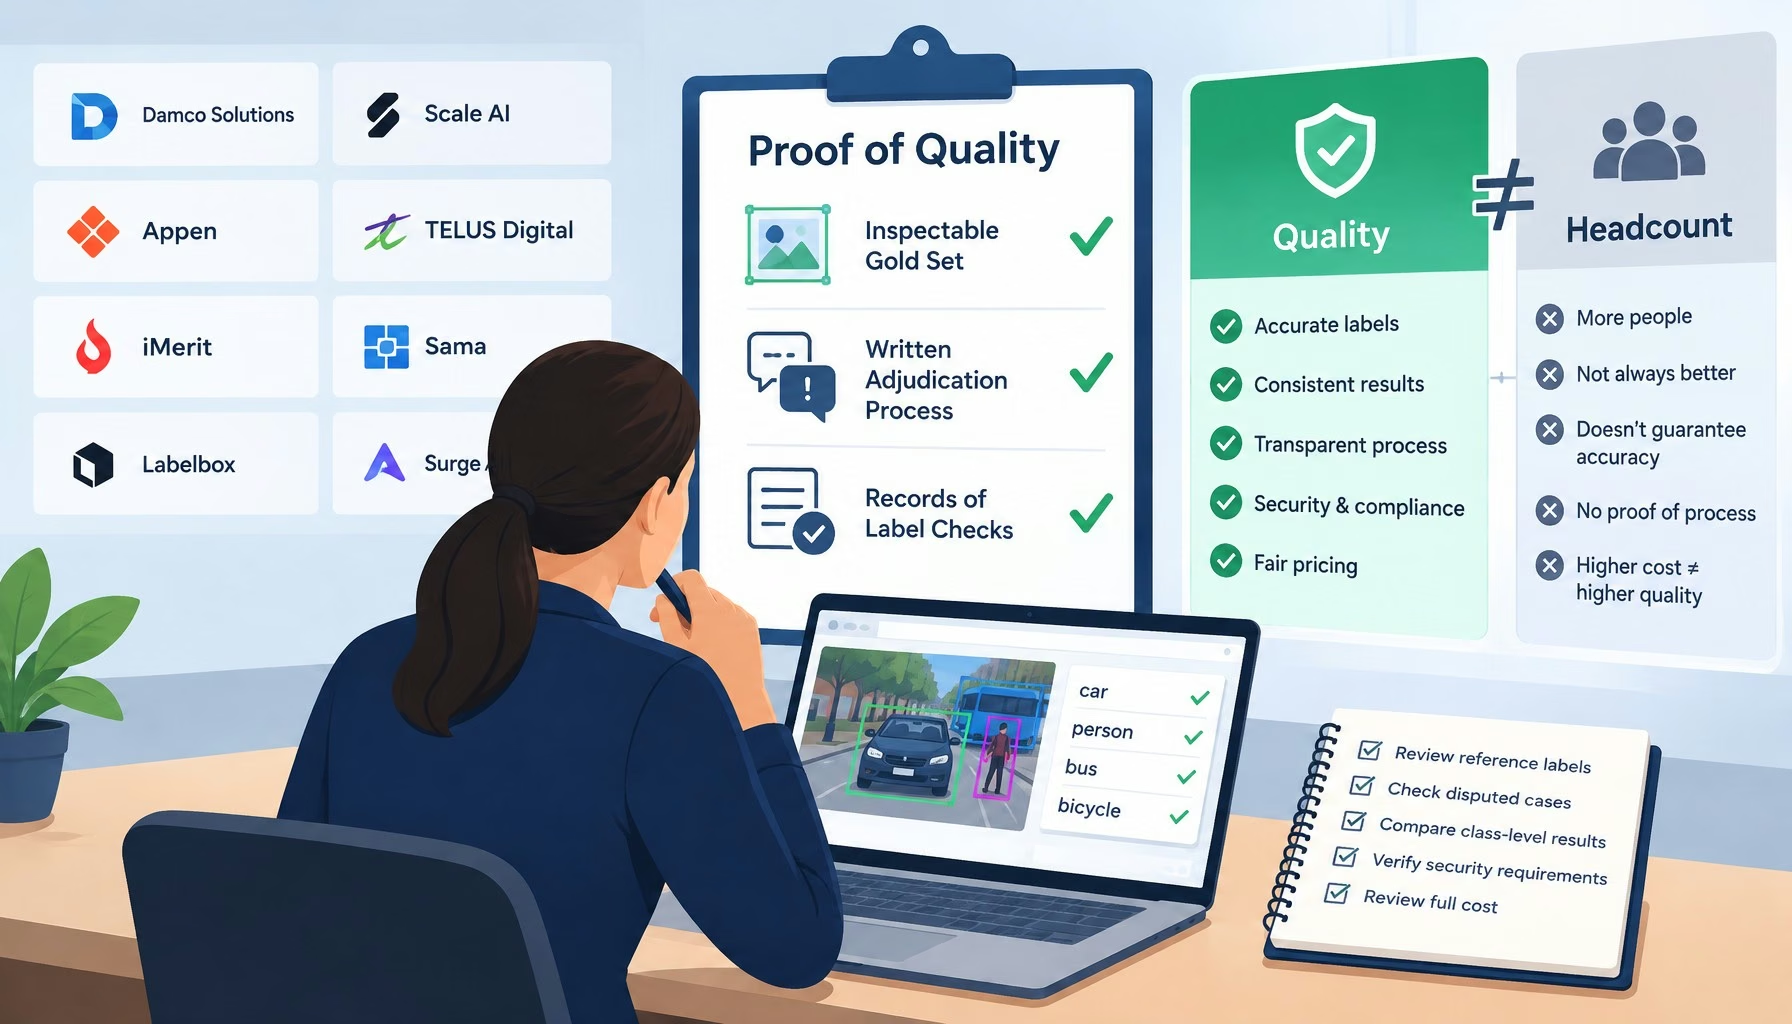
Flat editorial illustration: The article argues that data annotation quality should be measured by inspectable gold sets, written
The Top Data Annotation Companies Are Separated by Proof of Quality, Not Headcount
Big Data Exclusive
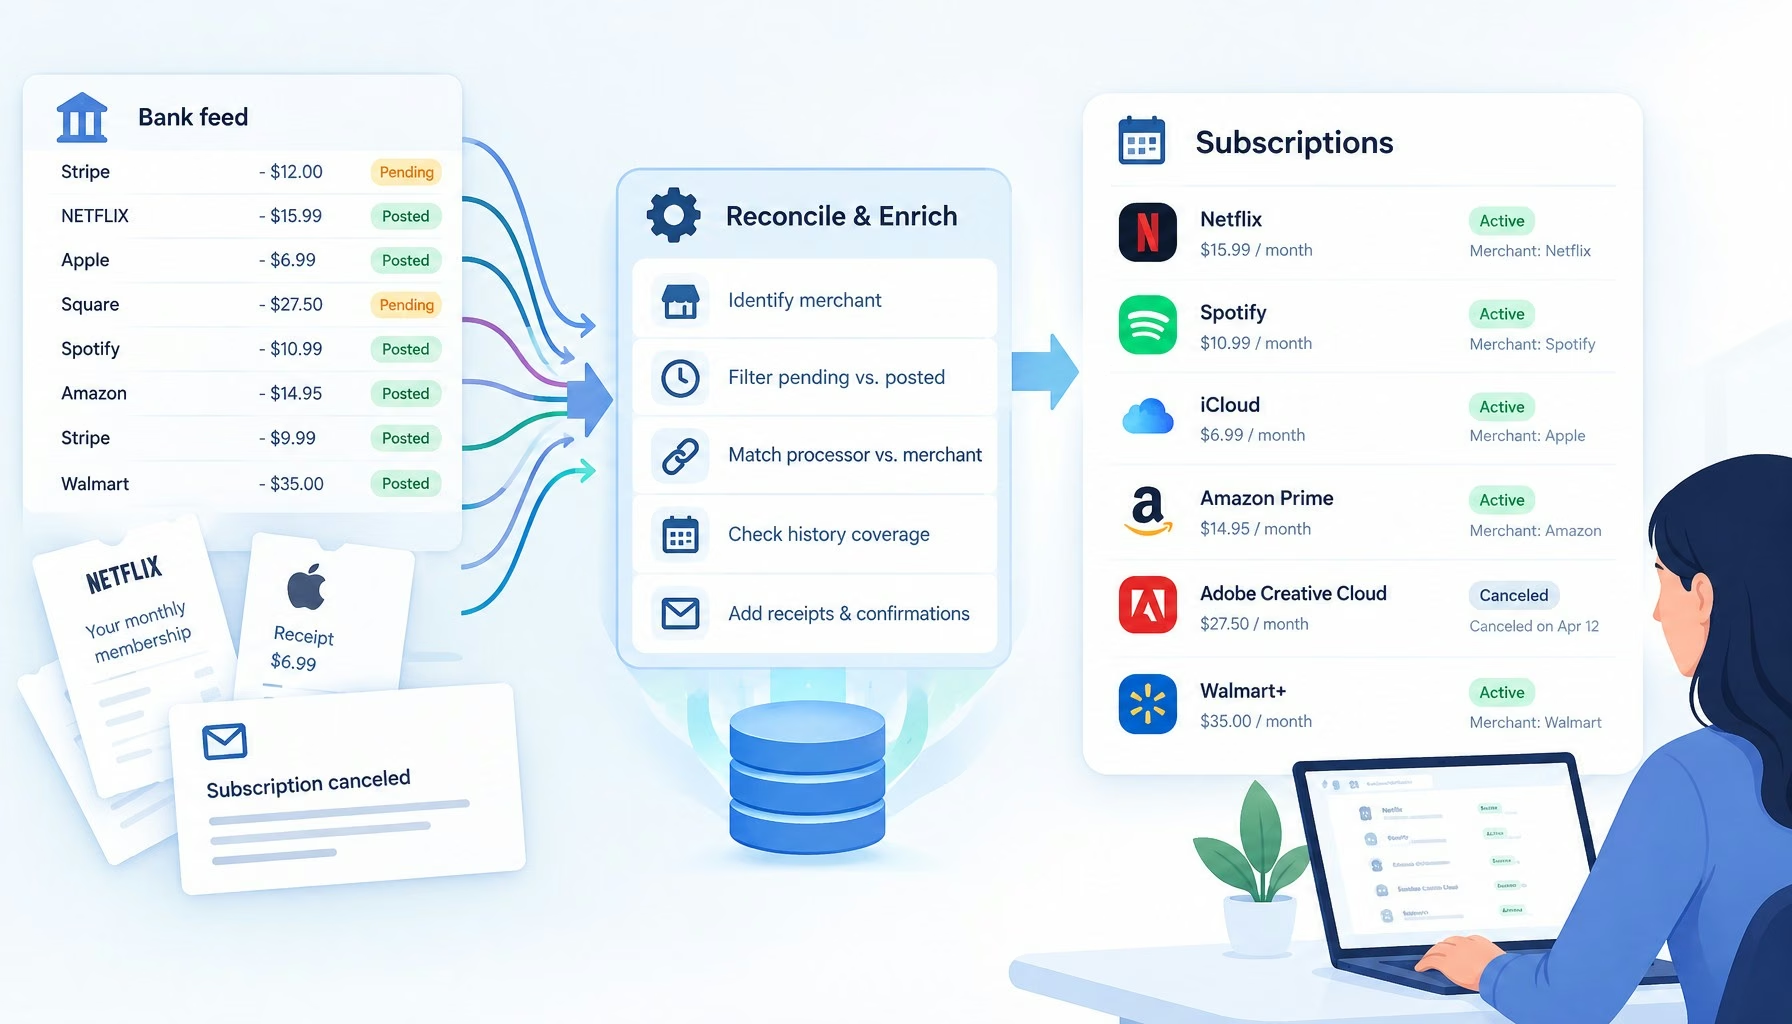
Flat editorial illustration: The article's core relationship is the gap between raw bank-feed records and reliable subscription i
Subscription Trackers Have a Transaction Data Problem
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

#20: Here's a thought...
Uncategorized

#20: Here’s a thought…

6 Min Read
Search with Slashtags: Taking Blekko Out for a Spin
Uncategorized

Search with Slashtags: Taking Blekko Out for a Spin

4 Min Read
Is Enterprise 2.0 a Crock?
Uncategorized

Is Enterprise 2.0 a Crock?

6 Min Read
Value Your Customer Data as a Business Asset
Uncategorized

Value Your Customer Data as a Business Asset

8 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

ai chatbot
How AI Website Chatbots Improve Customer Support and Lead Generation
Chatbots Exclusive
Artificial Intelligence for eCommerce: A Closer Look
Artificial Intelligence

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?