We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: SAS Admin: Process Data Faster in RDBMS by Buffering the Data in Memory
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Data Management > SAS Admin: Process Data Faster in RDBMS by Buffering the Data in Memory
Data Management

SAS Admin: Process Data Faster in RDBMS by Buffering the Data in Memory

Tricia Aanderud
Tricia Aanderud
4 Min Read
SAS Admin: Process Data Faster in RDBMS by Buffering the Data in Memory
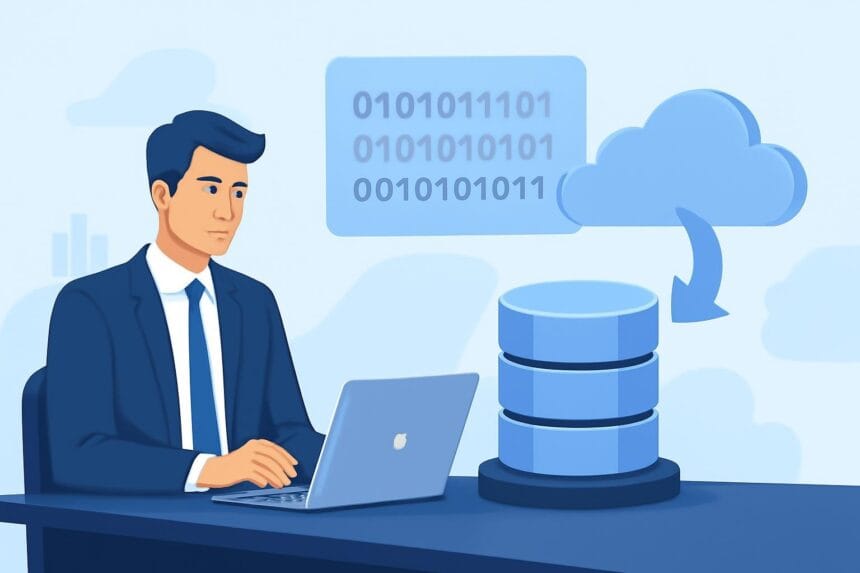
Illustrative image generated with OpenAI gpt-image-1.
SHARE

Contributed by Stephen Overton to BI Notes
Contents
  • Buffering Options
  • Using the LIBNAME Option
  • Using a SAS Data Set Option
  • Considerations


Contributed by Stephen Overton to BI Notes


More Read

Analytics: What’s Passion Got to Do with It?
What Is the Government Really Collecting From Your Phone? [INFOGRAPHIC]
A Visualization of the World’s Largest Data Breaches [INFOGRAPHIC]
The Battle of Britain: Thought Leadership in Information Management
Zombie Spreadsheets

By default, accessing third party relational databases can be very slow if not configured properly.  I recently started using PostgreSQL 9.1, an open source database, to store high volumes of data for my SAS Global Forum 2013 paper.  At first it was taking forever to load up data because SAS was inserting 1 row at a time into the database table.  After adding a simple option my data processing was off to the races!

Buffering Options

The SAS INSERTBUFF and READBUFF options will improve ODBC and OLE DB libraries dramatically.   By default these are set to 1 and 250 rows respectively for ODBC connections.  Other third party databases, such as Oracle, DB2, or MS SQL Server, will probably benefit as well but I have not been able to test.  Setting these buffer sizes tells SAS how many rows to buffer in memory before processing.  

Using the LIBNAME Option

These options can be added to the LIBNAME statement to set the buffering sizes for all processing done on tables within the library.  Ideally if you have the SAS Metadata server running, your SAS Administrator should set these options through the Data Library manager in SAS Management Console.

If you are using Base SAS or writing code in SAS Enterprise Guide, you can also manually write the LIBNAME step like this:

LIBNAME pgsgf13 ODBC  DBCOMMIT=10000  READBUFF=30000 INSERTBUFF=30000  DATASRC=sasgf13  SCHEMA=public ;

Be sure to check out SAS support for more information on the INSERTBUFF and READBUFF options for the LIBNAME statement.

Using a SAS Data Set Option

You can also explicitly define these buffer options for an individual data step in your code if you want.   This may come in handy depending on the type, size and width of data you plan on inserting.

LIBNAME pgsgf13 ODBC DATASRC=sasgf13 SCHEMA=public ; data pgsgf13.test(dbcommit=500000 insertbuff=10000 readbuff=10000); *** DATA STEP STUFF ****; run;

Be sure to check out SAS support for more information on the INSERTBUFF and READBUFF options for the data step.

Considerations

Careful consideration must be taken into account when setting these options.  The optimal setting depends on your SAS compute server resources and network capacity.  The number of rows to buffer should be much less for very wide tables with lots of character data because of the physical byte sizes of character columns and the overall width of the table.  In my project I am using very skinny fact tables with numeric data, which requires only 8 bytes per column of numeric data.  Assuming I have 10 numeric columns, that’s only about 80 bytes of data per row.  For my data step which inserts a huge volume of data, I could theoretically set the INSERTBUFF equal to something like 1,000,000 rows, but SAS does have a hard limit of approximately 32,000 rows it can buffer in memory :-) . 

Related content:

  1. Web Report Studio: Adding a Confidentiality Disclaimer
  2. SAS Enterprise Guide: Updating the Metadata with New/Modified Datasets
  3. Administration: Cleaning Up the WORK Library Automatically in UNIX
  4. Administration: Fall in Love with JBoss Again by Configuring the JGroup Bind Address
  5. SAS Code: Simple Macro to Benchmark Data Performance

The post SAS Administration: Process Data Faster in RDBMS by Buffering the Data in Memory appeared first on Business Intelligence Notes for SAS® BI Users.
TAGGED:metadatasas
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is the engineering transition from an AI prototype to a production-r
From AI Prototype to Production: Observability and Scalability Requirements for Data-Heavy SaaS Applications
Artificial Intelligence Exclusive
Preparing Data Systems and Governance for a Scaling Global Gaming Brand -- AI-generated illustration
Preparing Data Systems and Governance for a Scaling Global Gaming Brand
Big Data Infographic
How Restaurant POS and Ordering Data Reveal Generational Customer Patterns -- AI-generated illustration
How Restaurant POS and Ordering Data Reveal Generational Customer Patterns
Exclusive Infographic
From Trucks To Data: How Telematics Can Improve Freight Transportation -- AI-generated illustration
From Trucks To Data: How Telematics Can Improve Freight Transportation
Big Data Exclusive Infographic

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

SAS Visual Analytics: What's Happening to SAS BI?
Data Visualization

SAS Visual Analytics: What’s Happening to SAS BI?

7 Min Read
Better customer service, better results with predictive analytics
Business IntelligenceData MiningPredictive Analytics

Better customer service, better results with predictive analytics

6 Min Read
Interview with Anne Milley, SAS II
Data MiningPredictive Analytics

Interview with Anne Milley, SAS II

10 Min Read
Analytics Valley: Big Data, Data Scientists and SAS Programmers
AnalyticsHadoopOpen Source

Analytics Valley: Big Data, Data Scientists and SAS Programmers

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

Artificial Intelligence for eCommerce: A Closer Look
Artificial Intelligence
How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?