Gartner has put a number on something most BI leaders already suspect about their own organisation: 87% of enterprises still operate at a low level of BI and analytics maturity. Most are stuck doing spreadsheet-level analysis, or running pockets of siloed dashboards with no one actually in charge of whether the underlying data can be trusted.
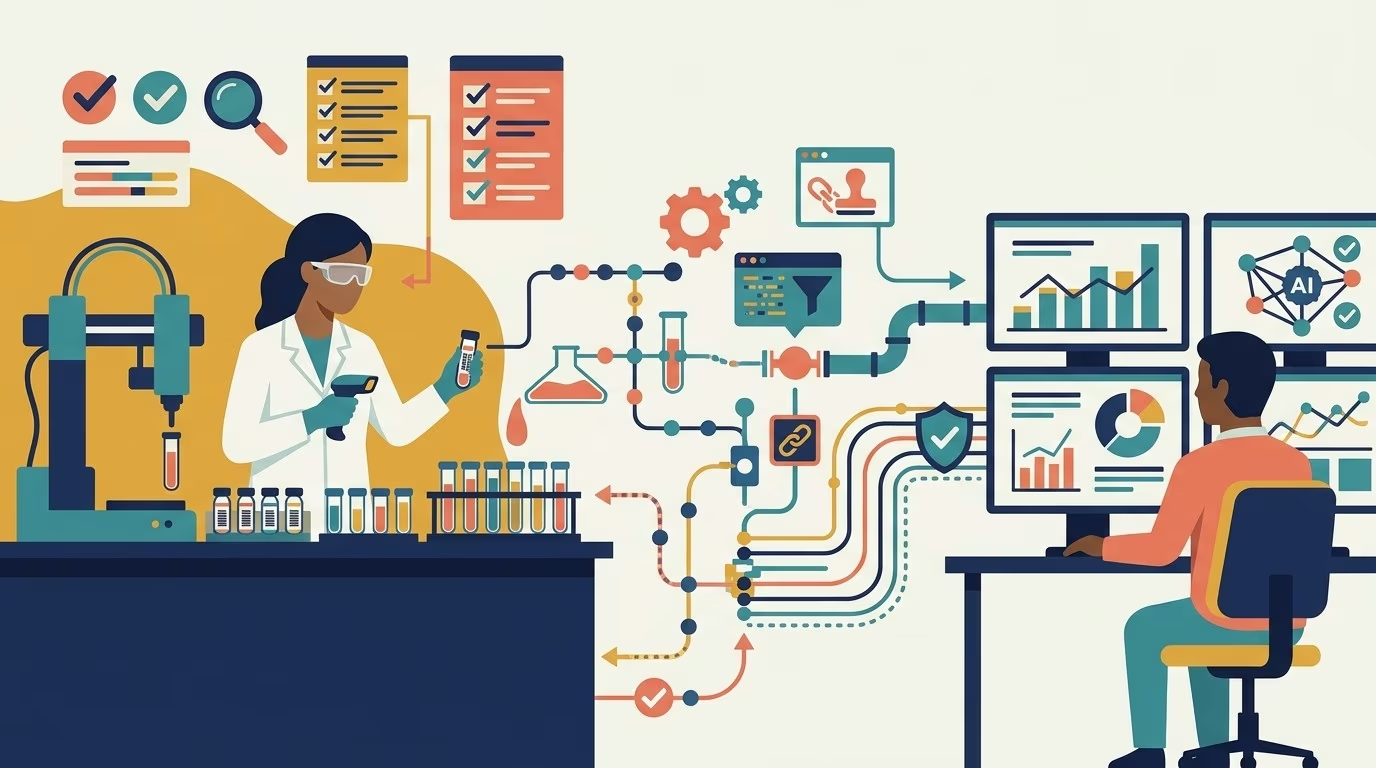
BI data governance can borrow three practices from regulated labs: validate data when it enters the system, retain its lineage through every transformation, and keep a verifiable record of its source and handling. Together, these practices address input, processing, storage, and contextual integrity before errors reach dashboards or AI models.
Meanwhile, a few floors down in the physical sciences, regulated laboratories have been solving a version of this exact problem for decades. Not because they’re more sophisticated with technology. Because they had no choice: a wrong result in a genomics or diagnostics lab doesn’t just skew a quarterly report, it can end up in a patient’s chart.
Low BI maturity severely constrains analytics leaders who are attempting to modernize BI,
Melody Chien, Senior Director Analyst, Gartner, in EMSNOW’s coverage of Gartner’s BI and analytics maturity findingsThat gap is worth closing. Here’s what BI actually has to learn from it.
More Read
- Input integrity: Validate records at capture, while you can still check their source and correct an entry error.
- Processing integrity: Keep transformations traceable so your team can follow a reported value back through the calculations that produced it.
- Storage integrity: Preserve accurate records and the history needed to establish what happened to them after capture.
- Contextual integrity: Keep provenance attached to the data so its later use remains consistent with the expectations at its source.
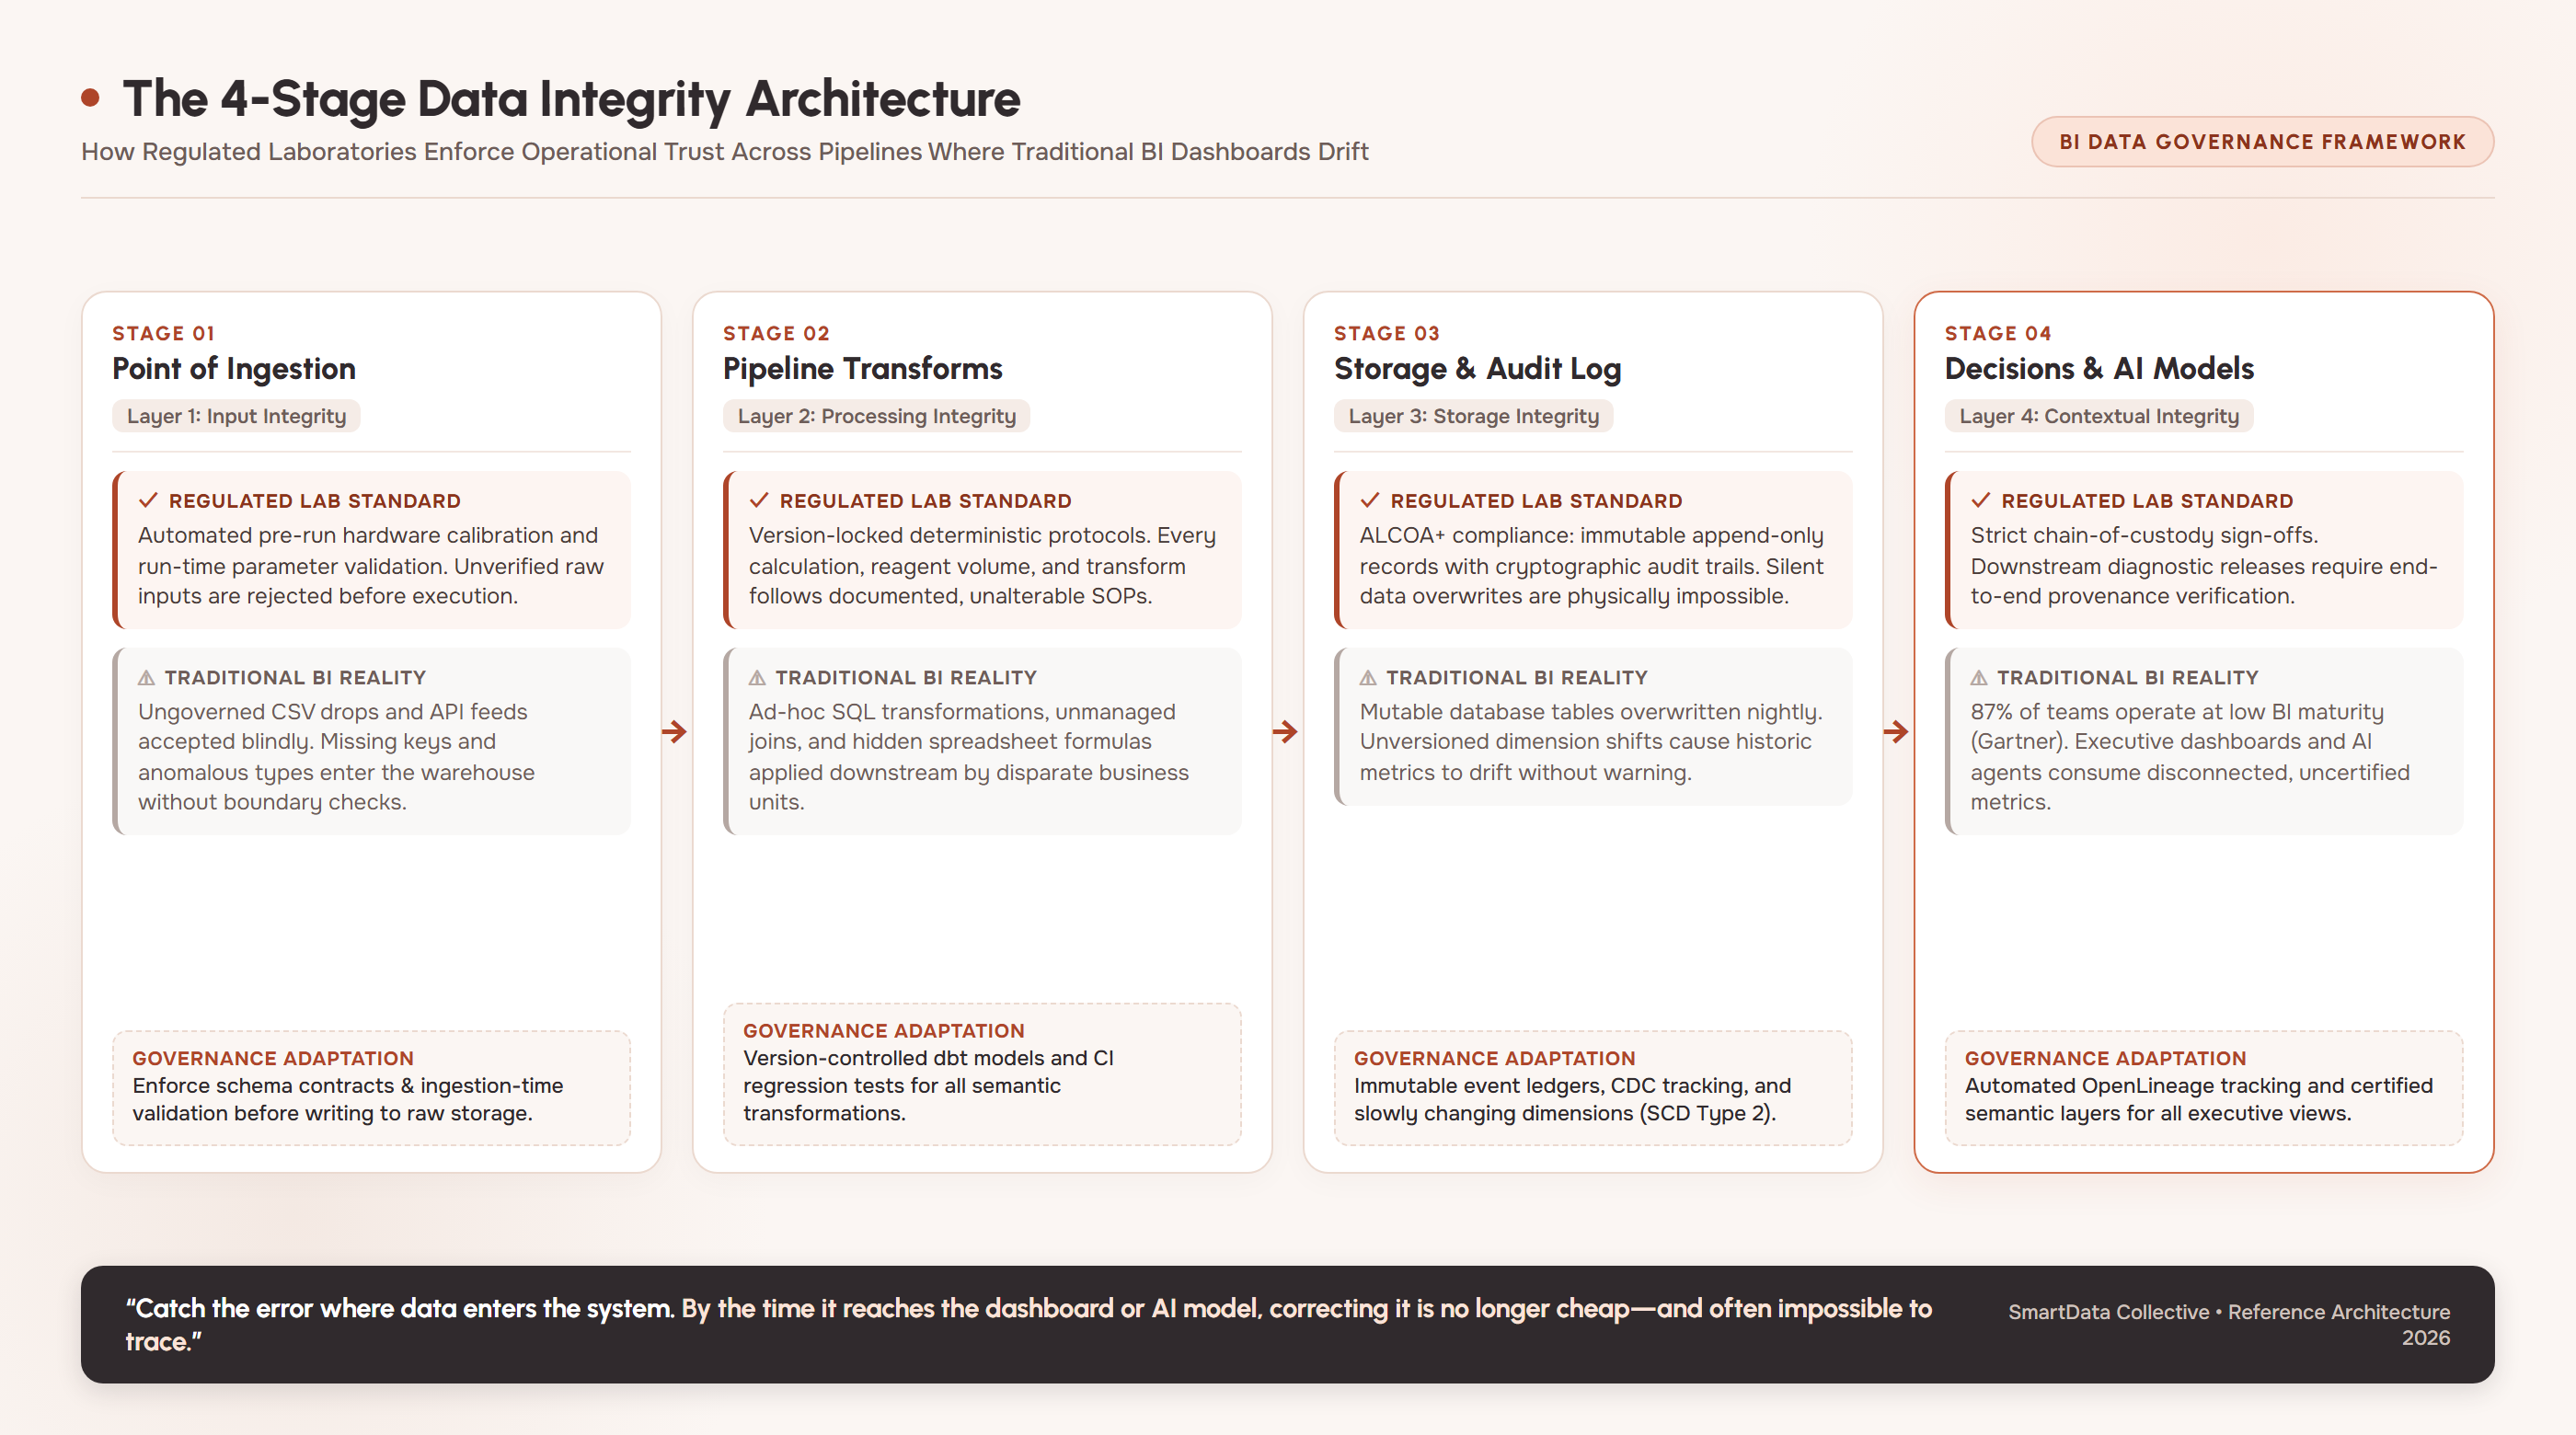
Engineers who think seriously about system trust break data integrity into four distinct failure modes, not one vague “data quality” bucket. Input integrity is whether the data entering a system is genuine and accurate. Processing integrity is whether the system transforms that data correctly. Storage integrity is whether it stays correct once it’s sitting somewhere. Contextual integrity is whether it’s used the way its source expects.
Each one fails differently. A processing error can leave every source record intact and still produce a wrong result. Imagine a transformation that reads an amount in cents as an amount in dollars. The input arrived correctly, and the stored source hasn’t changed. The calculation is where the meaning broke.
| Integrity Dimension | Regulated Lab Standard (ALCOA+) | Traditional BI Blind Spot | Modern BI Architecture Fix |
|---|---|---|---|
| Input Integrity | Automated pre-run calibration and ingestion validation; unverified raw data is rejected at the instrument boundary. | Unvalidated CSV and API feeds flow directly into staging tables; errors are only discovered after dashboard anomalies appear. | Ingestion-time schema contracts and automated pre-load validation tests (e.g., Great Expectations, dbt tests). |
| Processing Integrity | Deterministic, version-controlled SOP protocols; every reagent calculation and transformation step is programmatically locked. | Ad-hoc SQL transformations and unmanaged spreadsheet formulas scattered across siloed business departments. | Version-controlled semantic models (dbt/SQLMesh) with automated regression testing in CI/CD pipelines. |
| Storage Integrity | Immutable, append-only audit trails with cryptographic verification; in-place data overwrites are strictly prohibited. | Destructive nightly overwrites and unversioned dimension updates that silently alter historical reporting totals. | Immutable event streams, Change Data Capture (CDC), and SCD Type 2 dimension versioning in the data warehouse. |
| Contextual Integrity | Rigorous chain-of-custody documentation; diagnostic results cannot be released without end-to-end provenance sign-off. | 87% of teams operate at low BI maturity (Gartner); dashboards display aggregated metrics without traceable source lineage. | Automated active metadata catalogs (OpenLineage) and certified data products with explicit domain ownership. |
Whether a number looks wrong on a dashboard is a symptom check. A lab-inspired review follows that number back through its source records and transformations. IBM defines data integrity in terms of accuracy, completeness, and consistency throughout the data lifecycle. Your team can use the four failure modes to examine a report before a suspicious total forces the investigation:
- Input: Can you match the captured value to its source, and see which validation happened when it entered the system?
- Processing: Can you follow the transformations from that source value to the reported result, including any unit conversion?
- Storage: Does the retained record still match what was captured, with changes traceable?
- Context: Does the report use the data in a way consistent with its source and intended use?
Why Regulated Labs Got There First
Clinical and genomics labs treat sample identity and traceability as mandatory because a result can affect a patient’s care. For BI teams, the transferable discipline is keeping a record connected to its origin throughout processing and storage, even when the consequences of an error are less immediate.
Every sample needs a verifiable identity from collection. Its transformations have to remain traceable, and the chain of custody connects a result back to a specific sample and operator. A result without that connection leaves the lab unable to establish whose sample produced it or how it was handled.
None of that happened because a lab director woke up one day wanting better governance. It happened because the alternative is a patient getting someone else’s diagnosis.
BI teams don’t carry that same legal weight, which is exactly why the discipline tends to slip. Nobody goes to jail over a bad churn forecast. But the underlying mechanics of what goes wrong are the same: data gets disconnected from its origin, nobody notices until the output looks strange, and by then the root cause is three systems upstream and impossible to trace.
Liquid Handling as a Working Example
Lab instrumentation has been moving the same direction BI eventually needs to: pushing integrity checks back to the point of capture, before downstream review. Modern liquid handling systems increasingly validate a run before it starts instead of catching problems after results come out, which is the input-integrity half of the lab’s discipline built directly into the hardware.
Bio Molecular Systems’ Myra is a working example of this. Before a run begins, its software checks the protocol can actually be completed and verifies the physical deck layout with a camera system, catching a misplaced plate before a single sample gets touched. Sample lists import directly as CSV instead of requiring manual retyping by hand, which closes off a classic transcription-error path.
None of that was built as a BI feature. It was built because a lab can’t afford to find out three steps later that a sample went into the wrong well. The liquid handler is, in effect, enforcing input integrity at the hardware layer, which is precisely the layer most BI pipelines skip entirely.
What BI Teams Can Actually Borrow
Three things translate cleanly, without anyone needing a lab coat.
First, validate at the point of capture, not at the dashboard. A BI stack that only checks data quality once it’s already in the warehouse is doing the equivalent of reviewing lab results after the sample’s already been thrown out. By then you can flag the anomaly, but you can’t fix the cause.
Second, treat lineage as non-negotiable, not a nice-to-have. A lab can tell you which operator ran which sample on which instrument at what time. Most BI teams can’t tell you which system a given field originated in, let alone who touched it last. That’s not a tooling gap so much as a priorities gap.
Third, put provenance on the agenda at the level labs put chain of custody. One Forbes Finance Council piece framed this bluntly: without a verifiable record of where training data came from and how it’s been handled, an AI model’s output is a liability dressed up as an asset. The author’s suggested standard, TRiSM (trust, risk and security management for AI), is essentially asking BI and AI teams to adopt the lab’s old habit of never trusting a result you can’t trace back to its source.
The AI Stakes Make This Urgent
Data quality affects whether your team can trust a model’s predictions. Stale or incomplete inputs can produce inaccurate results, as Decube’s discussion of data governance explains. The lab’s capture-time checks address that upstream problem, while lineage keeps the source and handling history available when an output needs investigation.
That’s the lab’s oldest lesson, applied to a newer problem. Catch the error where the data enters the system, because by the time it reaches the model, correcting it is no longer cheap, and it’s sometimes no longer possible to even locate.
Checking BI Data Before It Reaches the Dashboard
Regulated labs didn’t invent data governance because they were ahead of the curve on dashboards. They invented it because the cost of getting it wrong was unacceptable, and that forced the discipline further upstream than most BI teams have ever bothered to go. The dashboard was never the right place to start checking data quality. It’s usually the last place a problem should still be visible, not the first.
Frequently Asked Questions
What is BI data governance and why does it fail in most organizations?
BI data governance is the structured framework of policies, validation gates, and metadata management that ensures enterprise reports and dashboards reflect accurate, reliable business metrics. In practice, most implementations struggle because organizations rely on reactive dashboard cleanups instead of proactive point-of-capture validation. According to Gartner research led by analyst Melody Chien, 87% of organizations operate at low BI maturity, characterized by siloed spreadsheet extraction, ungoverned metrics, and uncoordinated analytics initiatives.
What are the four core integrity layers in BI data governance?
Modern data architecture adapts four integrity disciplines from regulated laboratories: input integrity (verifying schema conformance and data quality before records enter staging), processing integrity (ensuring transformation logic and SQL calculations are deterministic and version-controlled), storage integrity (preventing silent overwrites and unversioned historical metric drift), and contextual integrity (maintaining end-to-end data lineage so consumers know the exact origin, transformations, and intended usage of every dashboard metric).
How does point-of-capture validation prevent downstream dashboard and AI errors?
Catching data errors at the ingestion boundary stops bad records before they propagate into downstream reporting marts or machine learning models. In automated liquid handling systems, hardware calibrations and volume tolerances are verified before a run starts, preventing corrupted experimental results. Similarly, enforcing schema contracts and automated data quality checks at the BI ingestion tier eliminates the costly post-hoc reconciliation cycles that erode executive trust in analytics.