
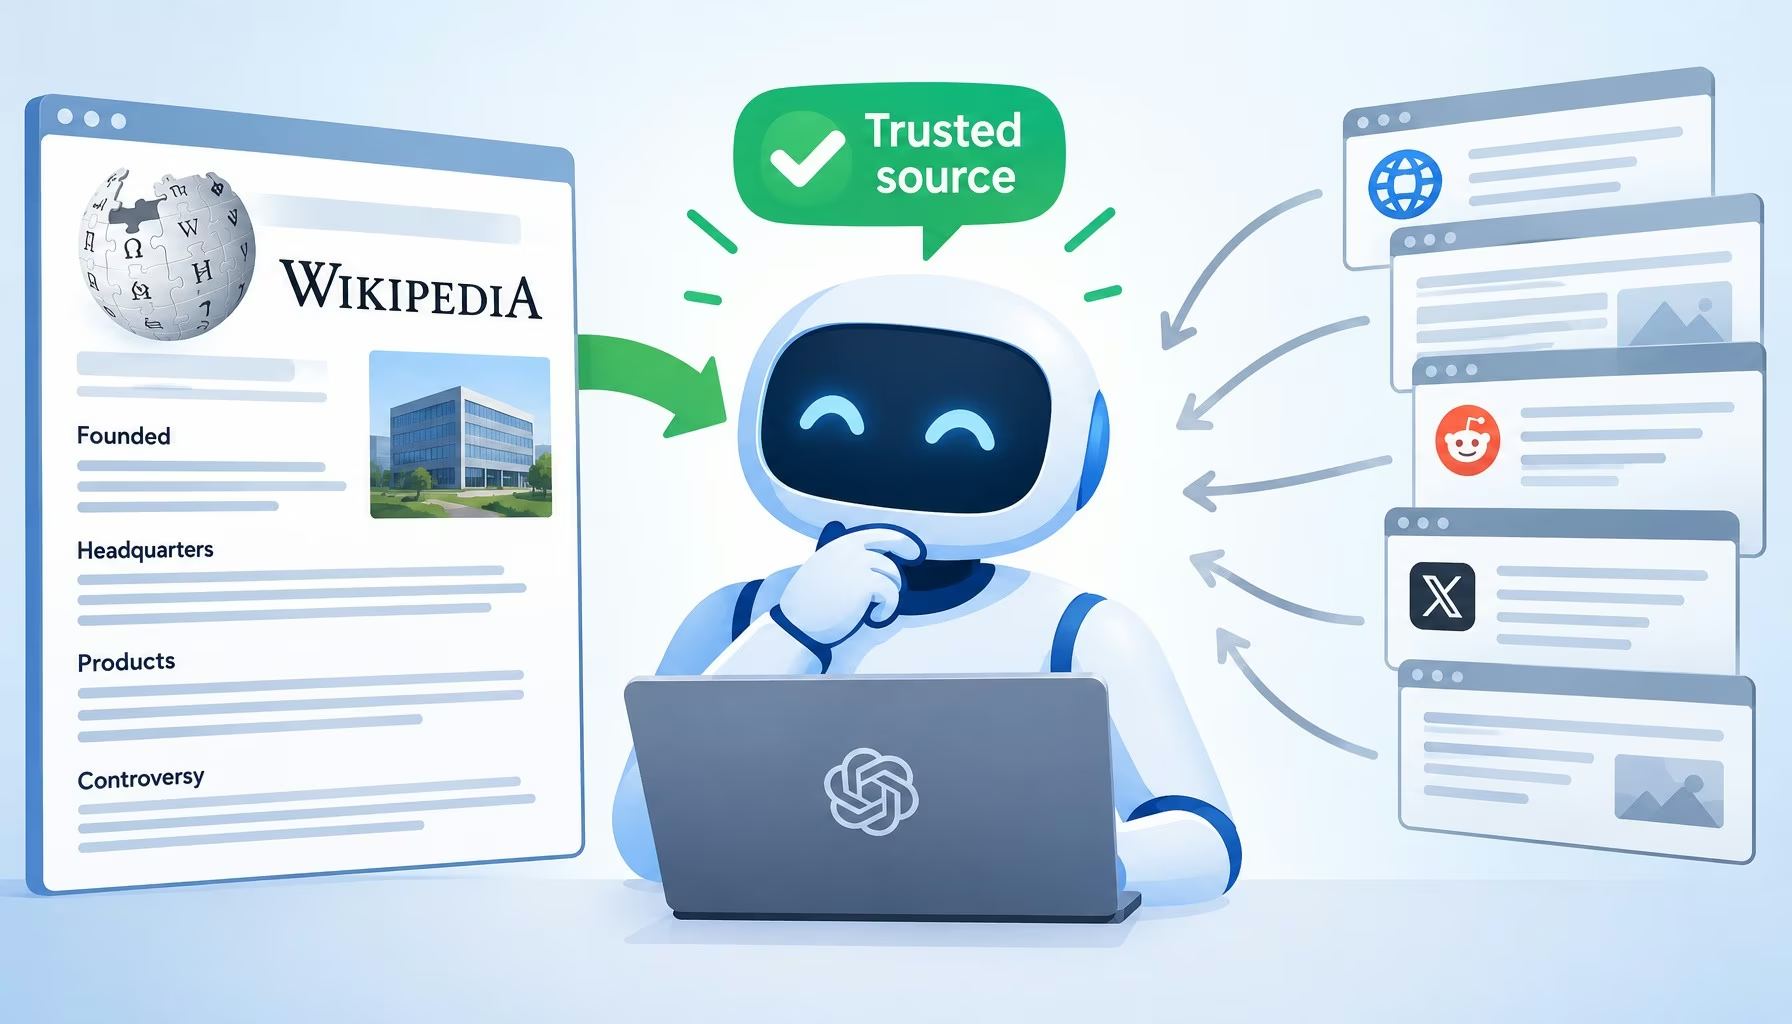
Ask an AI assistant about a company and you may get a familiar outline: founding date, headquarters, products and a controversy. That resemblance alone does not reveal where the answer came from. To investigate it, separate two questions: what went into the model’s training, and what sources the product retrieved for this answer.
- What are Wikipedia editing services?
- Why do LLMs trust Wikipedia more than other sources?
- Structure does part of the work
- The web copies Wikipedia, so check where agreement comes from
- AI companies now pay for the feed
- But isn’t Wikipedia’s AI citation share dropping?
- What this means for your reputation
- What legitimate Wikipedia editing services actually do
- Wikipedia is one input. Plan for the rest of the stack.
- FAQ
- What do Wikipedia editing services do?
- Why do large language models rely on Wikipedia?
- Does fixing a Wikipedia article change what ChatGPT says?
- Is paid Wikipedia editing allowed?
- Is Wikipedia still important for AI search visibility?
- Can a company remove negative information from its Wikipedia page?
- How do I find out what AI says about my company?
Wikipedia editing services sit at the intersection of those questions. Published training papers document Wikipedia’s use, and Wikimedia now supplies commercial data access to major technology companies. Neither fact means a company can control an AI answer by changing an encyclopedia entry. The useful goal is accurate, independently sourced information, with a clear record of how corrections were requested.
What are Wikipedia editing services?
These are firms or consultants offering help with Wikipedia research, article assessment and proposed corrections. Assess the work against Wikipedia’s rules, rather than a promise of favorable coverage. The Wikimedia paid-contribution disclosure guidance requires disclosure of the employer, client and affiliation. Disclosure does not exempt anyone from the project’s other rules.
English Wikipedia’s conflict-of-interest guideline strongly discourages editing articles about one’s own interests. For an organization commissioning work, disclosed talk-page requests provide a way to propose corrections for independent editors to consider. An editing contract should specify that process and the evidence supplied, without promising acceptance.
Why do LLMs trust Wikipedia more than other sources?
Here, “trust” is shorthand for a training choice, not a belief held by a model. Historical examples show why Wikipedia deserves attention, but they do not disclose the data mix of every current AI product.
In GPT-3’s original paper, Table 2.2, filtered Common Crawl contained 410 billion tokens and received 60% of the training mix. Wikipedia contained 3 billion tokens and received 3%. For a 300-billion-token training run, the table reports 0.44 epochs for filtered Common Crawl and 3.4 for Wikipedia. Dataset size, sampling weight and repeated exposure are different measures.
The 2023 LLaMA paper, Table 1, lists Wikipedia at 83 GB, a 4.5% sampling proportion and 2.45 epochs. Its CommonCrawl and C4 rows report 1.10 and 1.06 epochs respectively, so describing all web data as being seen once or less would be inaccurate.
Those figures establish Wikipedia’s inclusion and reuse in two documented training runs. They do not establish that an individual Wikipedia statement will dominate an answer, or that today’s assistants share those exact proportions. A communications team should use them as context for an audit, not as a formula for buying influence.
More Read
Structure does part of the work
Wikipedia’s lead-section guidance calls for an accessible introduction and summary of an article’s important points. Infoboxes, where appropriate, summarize selected facts. They are not mandatory on every article, and section order varies by subject.
Wikidata provides a separate, structured knowledge base. An audit can compare an organization’s encyclopedia article with relevant Wikidata statements and their references. Do not assume that every field is current, or that every AI product consults Wikidata before other sources.
For practical review, check the lead, key dates, leadership and references individually. Record disagreements between sources. A neatly formatted claim still needs verification; predictable formatting is not evidence that a statement is true.
The web copies Wikipedia, so check where agreement comes from
The Wikipedia community documents citogenesis incidents: an unsupported statement is repeated elsewhere and that repetition is later treated as a source for Wikipedia. This is a sourcing problem even before an AI system enters the picture.
When several pages repeat a questionable claim, investigate whether they offer independent reporting or merely copy one another. Repetition should prompt a source check. It does not by itself prove that an AI model treats those copies as independent corroboration.
For example, an audit might investigate an old leadership name or a lawsuit described without its later outcome. These are proposed checks, not claims about a particular company. Start with the underlying records, then document which public pages need correction.
AI companies now pay for the feed
On January 15, 2026, Wikimedia Enterprise announced Amazon, Meta, Microsoft, Mistral AI and Perplexity as partners, alongside an existing roster including Google and Ecosia. The announcement describes commercial infrastructure for large-scale reuse of Wikimedia content. It does not disclose how each partner weights Wikipedia in training or how quickly a correction reaches a specific assistant.
Infrastructure costs are part of the context. In its April 2025 account of crawler traffic, Wikimedia reported a 50% increase in bandwidth used to download multimedia since January 2024, largely driven by automated scraping. It also reported that bots accounted for 65% of its most resource-consuming traffic. Those are infrastructure measurements, not measures of Wikipedia’s influence on generated answers.
But isn’t Wikipedia’s AI citation share dropping?
A citation-share claim needs a defined denominator. Ask whether a report measures all citations, a selection of leading domains, or conversations containing a citation. Also record the product, prompts, market and collection dates before comparing two reports.
A visible source link concerns the answer being inspected. It does not disclose the contribution of a training document. The original retrieval-augmented generation paper explicitly distinguishes model parameters from an external retrieval index, illustrating why these are separate things to examine.
| What you are checking | Useful evidence | What it cannot establish alone |
|---|---|---|
| Historical training exposure | Published training papers and dataset tables | The source of a particular current answer |
| Retrieved sources for an answer | The answer’s links, accessible source text and test date | The model’s complete training mix |
| A factual correction | Underlying records, edit-request history and follow-up answer checks | A guaranteed update across every AI product |
What this means for your reputation
Treat Wikipedia accuracy as one part of a broader information audit. A useful working process is:
- Record the answer. Save the question, product, date and cited links. Keep separate records for different assistants.
- Trace the disputed statement. Compare the cited page with the underlying documentation, rather than assuming Wikipedia was responsible.
- Request a supported correction. Explain precisely what is wrong and provide suitable sources through the relevant editorial process.
- Check again. Re-run the same questions after the source changes. Record what actually changed instead of promising an update schedule.
A source edit is not a command to an already trained model. A retrieval system also has its own indexing and selection process. Avoid contracts promising immediate changes across assistants, automatic removal of criticism, or a guaranteed answer.
What legitimate Wikipedia editing services actually do
When assessing wikipedia editing services, ask for a documented scope rather than a favorable-coverage guarantee. Useful deliverables to request include:
- An accuracy audit: proposed corrections tied to particular passages and supporting records.
- A sourcing assessment: a distinction between independent coverage, the organization’s own statements and claims that remain unsupported.
- Disclosed edit requests: neutral proposed wording, references and a record of the discussion.
- A Wikidata check: relevant statements and references reviewed separately from the encyclopedia text.
- A monitoring record: follow-up checks for outdated facts and the outcomes of requested changes.
Wikipedia’s verifiability policy and neutrality policy govern sourcing and fair treatment. A company’s preferred wording is not sufficient grounds for changing an article. Its own publications may support limited, appropriate statements, but should not be presented as independent coverage.
Ask the provider how it handles an unfavorable fact that is well sourced. The answer should address accuracy, context and proportion. It should not promise to erase criticism. Disclosed paid work still needs to comply with the same editorial policies.
Wikipedia is one input. Plan for the rest of the stack.
Wikipedia work and generative engine optimization services can be evaluated together without treating either as a shortcut. Use the same factual record to review company information across relevant sources, and distinguish a correction from an attempt to manufacture favorable consensus.
The practical sequence is straightforward: audit current answers, investigate their sources, request supported corrections and measure the result. Published training papers explain why Wikipedia deserves a place in that audit. They do not make it the sole source of truth, and they do not turn an editing service into a control panel for AI answers.
FAQ
What do Wikipedia editing services do?
Wikipedia editing services offer research, article assessments and proposed corrections. When hiring one, require disclosure, neutral wording, suitable sourcing and an edit-request record. Acceptance remains an editorial decision, not a contractual entitlement.
Why do large language models rely on Wikipedia?
Published GPT-3 and LLaMA training papers document its use and repeated exposure. That establishes a role in those models’ training, not the source of every answer or a universal rule for all current models.
Does fixing a Wikipedia article change what ChatGPT says?
A Wikipedia correction alone does not establish that ChatGPT’s answer will change. Check the answer’s sources and repeat the test after the edit. Training and retrieval are separate processes, with no guaranteed update timeline established by the sources here.
Is paid Wikipedia editing allowed?
Wikimedia requires paid-contribution disclosure. Disclosure alone is not permission for every edit: contributors must also follow the applicable project policies and conflict-of-interest guidance.
Is Wikipedia still important for AI search visibility?
The historical training papers and Wikimedia’s commercial partnerships make it relevant to investigate. Measure its role in your own answer checks rather than using an undefined citation percentage as a universal benchmark.
Can a company remove negative information from its Wikipedia page?
Dislike of a statement is not grounds for removal. A request should identify a factual error, sourcing problem or issue of proportion under Wikipedia’s policies. Provide evidence and allow independent editors to assess the request.
How do I find out what AI says about my company?
Use a repeatable set of questions across the assistants you want to examine. Save dates, answers and citations, then check disputed statements against underlying records. This produces an auditable observation rather than an assumption about where the answer originated.