We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Fraud Prediction – Decision Trees & Support Vector Machines
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Business Intelligence > CRM > Fraud Prediction – Decision Trees & Support Vector Machines
CRMData MiningPredictive Analytics

Fraud Prediction – Decision Trees & Support Vector Machines

romakanta
romakanta
5 Min Read
Fraud Prediction - Decision Trees & Support Vector Machines
Illustration generated with FLUX.2 [klein 4B] via Cloudflare Workers AI.
SHARE

My first thought when I was asked to learn and use Oracle Data Mining (ODM) was, “Oh no! Yet another Data Mining Software!!!”

It’s been about 2 weeks now since I have been using ODM, particularly focusing on two classification techniques – Decision Trees & Support Vector Machines. As I don’t want to get into the details of the interface/usability of ODM (unless Oracle pays me!!), I will limit this post on a comparison of these two classification techniques at a very basic level, using ODM.

A very brief introduction of DT & SVM.
More Read

How Nate Silver Won the Election with Data Science
Overcoming the Challenges of Big Data Clustering
Can We Automate Data Mining?
To Test or to Target? Where to start for best ROI?
How Artificial Intelligence Is Revolutionizing Healthcare Sector in 2019

DT – A flow chart or diagram representing a classification system or a predictive model. The tree is structured as a sequence of simple questions. The answers to these questions trace a path down the tree. The end product is a collection of hierarchical rules that segment the data into groups, where a decision (classification or prediction) is made for each group.

-The hierarchy is called a tree, and each segment is called a node.
-The original segment contains the entire data set, referred to as the root node of the tree.
-A node with all of its successors forms a branch of the node that created it.
-The final nodes (terminal nodes) are called leaves. For each leaf, a decision is made and applied to all observations in the leaf.

SVM – A Support Vector Machine (SVM) performs classification by constructing an N-dimensional hyperplane that optimally separates the data into two categories.

In SVM jargon, a predictor variable is called an attribute, and a transformed attribute that is used to define the hyperplane is called a feature. A set of features that describes one case/record is called a vector. The goal of SVM modeling is to find the optimal hyperplane that separates clusters of vector in such a way that cases with one category of the target variable are on one side of the plane and cases with the other category are on the other size of the plane. The vectors near the hyperplane are the support vectors.

SVM is a kernel-based algorithm. A kernel is a function that transforms the input data to a high-dimensional space where the problem is solved. Kernel functions can be linear or nonlinear.

The linear kernel function reduces to a linear equation on the original attributes in the training data. The Gaussian kernel transforms each case in the training data to a point in an n-dimensional space, where n is the number of cases. The algorithm attempts to separate the points into subsets with homogeneous target values. The Gaussian kernel uses nonlinear separators, but within the kernel space it constructs a linear equation.

I worked on this dataset which has fraudulent fuel card transactions. Two techniques I previously tried are Logistic Regression (using SAS/STAT) & Decision Trees (using SPSS Answer Tree). Neither of them was found to be suitable for this dataset/problem.

The dataset has about 300,000 records/transactions and about 0.06% of these have been flagged as fraudulent. The target variable is the fraud indicator with 0s as non-frauds, and 1s as frauds.

The Data Preparation consisted of missing value treatments, normalization, etc. Predictor variables that are strongly associated with the fraud indicator – both from the business & statistics perspective – were selected.

The dataset was divided into a Build Data (60% of the records) and Test Data (40% of the records).

Algorithm Settings for DT,

Accuracy/Confusion Matrix for DT,

Algorithm Settings for SVM,

Accuracy/Confusion Matrix for SVM,


http://datalligence.blogspot.com/

Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

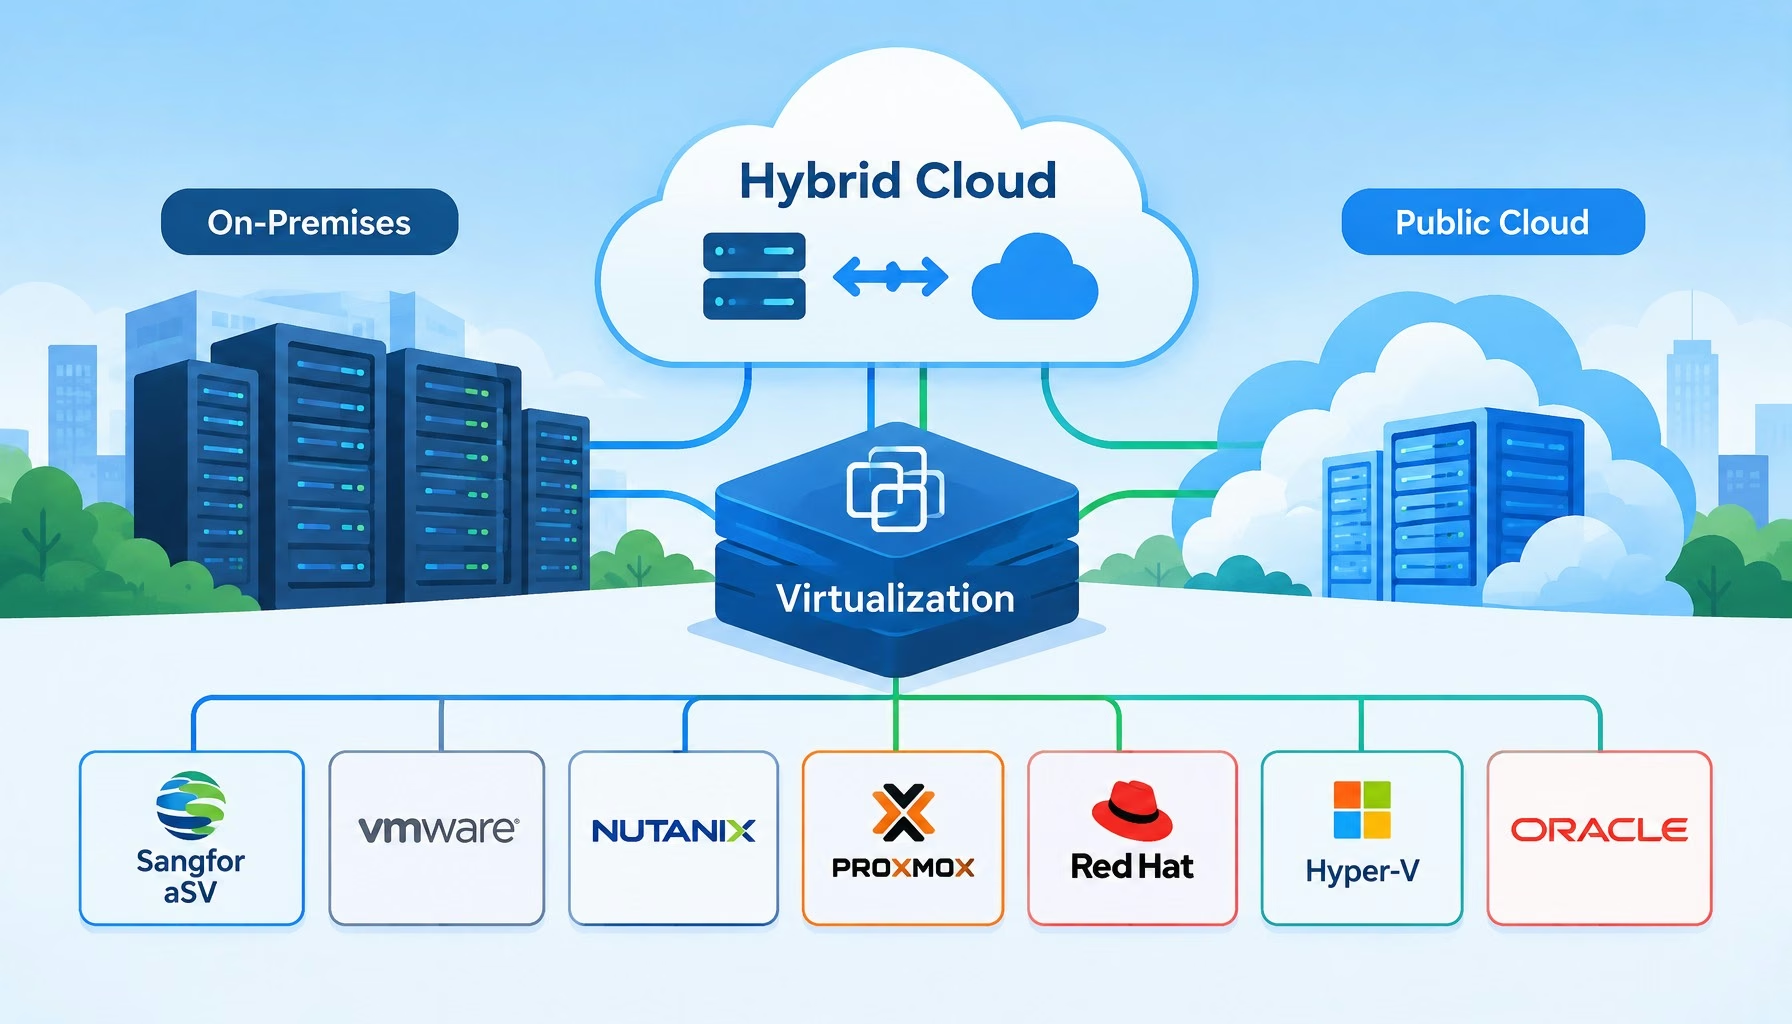
Flat editorial illustration: The article's core relationship is the hypervisor as the abstraction layer that makes hybrid cloud p
7 Best Virtualization Platforms for Hybrid Cloud Environments
Big Data
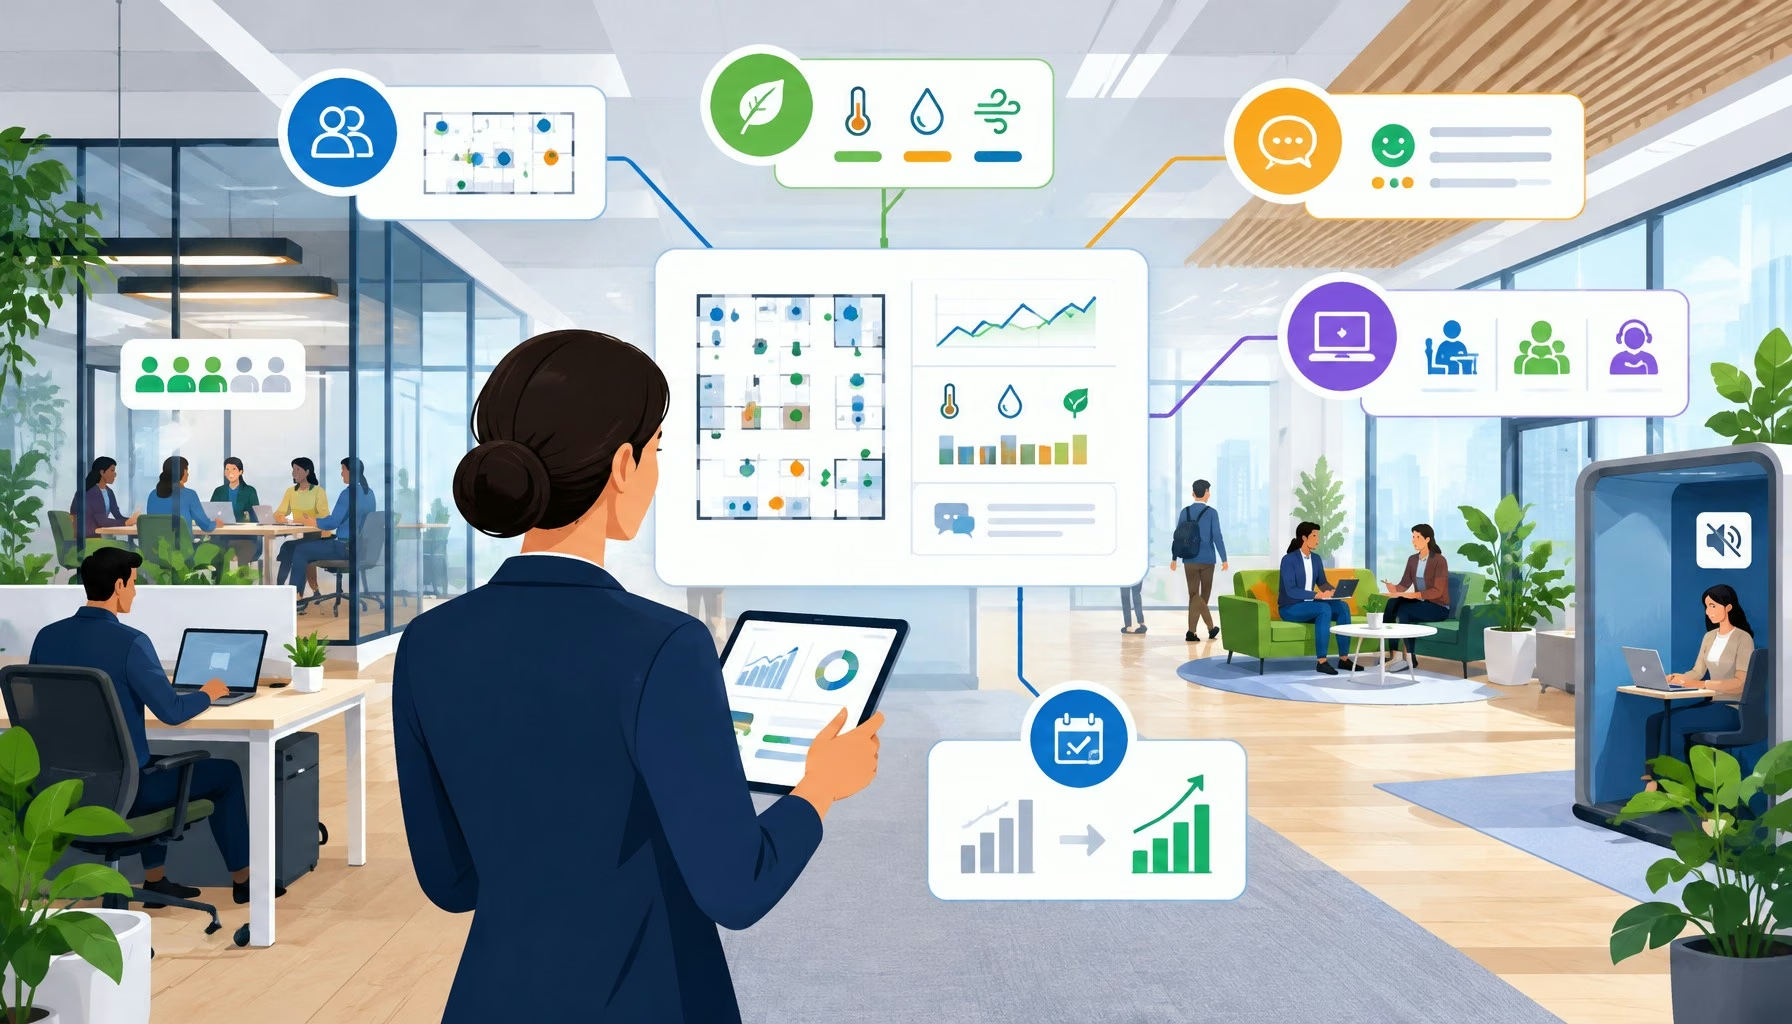
Flat editorial illustration: The article's core relationship is between aggregated workplace data (occupancy, environmental, feed
How Businesses Can Use Workplace Data to Create Better Office Environments
Big Data Business Intelligence Exclusive
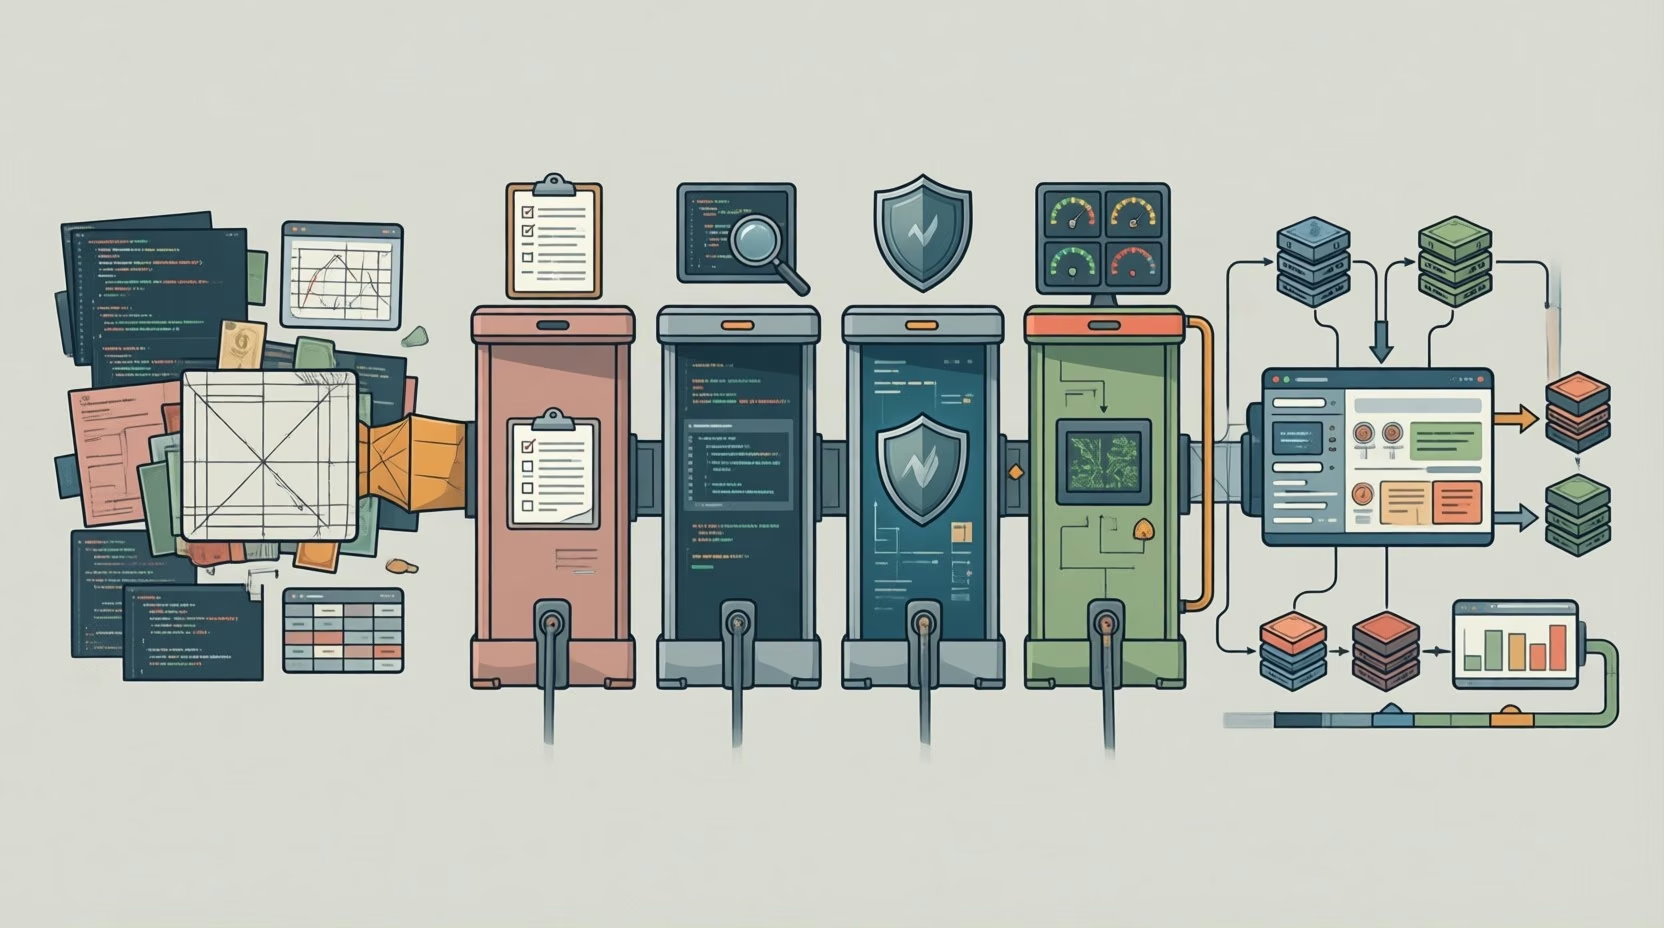
Flat editorial illustration: The article's core relationship is the engineering transition from an AI prototype to a production-r
From AI Prototype to Production: Observability and Scalability Requirements for Data-Heavy SaaS Applications
Artificial Intelligence Exclusive
Preparing Data Systems and Governance for a Scaling Global Gaming Brand -- AI-generated illustration
Preparing Data Systems and Governance for a Scaling Global Gaming Brand
Big Data Infographic

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Call Center Improvement Strategies that Work: 4 Ways to use Data And Win
Data Collection

Call Center Improvement Strategies that Work: 4 Ways to use Data And Win

5 Min Read
Predictive Model Deployment and Execution Made Easy with PMML
Data MiningModeling

Predictive Model Deployment and Execution Made Easy with PMML

4 Min Read
Redefining the enterprise user experience
CRM

Redefining the enterprise user experience

9 Min Read
How Big Data Can Impact the Mining Industry
Predictive Analytics

How Big Data Can Impact the Mining Industry

6 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive
ai chatbot
How AI Website Chatbots Improve Customer Support and Lead Generation
Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?