We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    Flat editorial illustration: The article is about joining public web signals with internal business metrics so BI teams can inter
    Alternative Data in BI: Bringing Public Web Data Into Your Dashboards
    23 Min Read
    Flat editorial illustration: The article contrasts passive follower totals with a behavioral path from attention and trust to cli
    Creator Analytics Beyond Follower Count: Seven Metrics That Measure Audience Behavior
    11 Min Read
    Flat editorial illustration: The article connects AI and marketing analytics with managerial judgment grounded in consumer behavi
    How an Online MBA in Marketing Connects AI and Data Analytics
    11 Min Read
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: What Are Accumulators? A Must-Know for Apache Spark
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Big Data > Data Quality > What Are Accumulators? A Must-Know for Apache Spark
Big DataData QualityData WarehousingUnstructured Data

What Are Accumulators? A Must-Know for Apache Spark

kingmesal
kingmesal
6 Min Read
What Are Accumulators? A Must-Know for Apache Spark
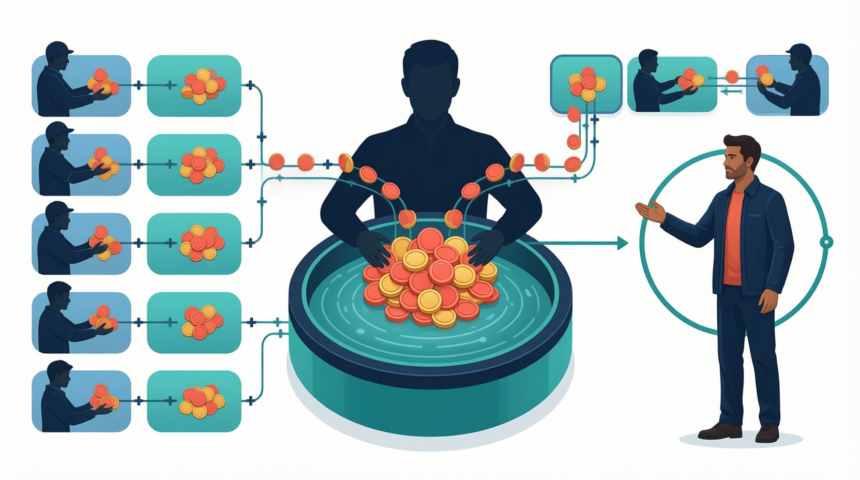
Illustration generated with Qwen Image.
SHARE

If you’ve been using Apache Spark, then you know how awesome the Resilient Distributed Dataset (RDD) is. This data structure is essential to Spark for both its speed and its reliability.

Contents
  • Accumulators
  • Avoiding Mutable Variables
  • Use Case: Log Errors
  • Broadcast Variables
  • Conclusion

There are a couple of concepts that make Spark even faster and more reliable when run over large clusters: accumulators and broadcast variables.

Accumulators

What exactly are accumulators? Accumulators are simply variables that are meant to count something—hence the name “accumulator.” You can specify an accumulator with a default value. If you’re starting from scratch, the number would typically be from 0.

Avoiding Mutable Variables

Why would you use accumulators instead of a normal variable? Like a lot of Spark installations, yours is probably running over large clusters, either in your data center or in some cloud provider’s machines.
More Read

5 Ways Big Data is Fueling the Sharing Economy
How Big Data Will Change People Management Forever
Why Choosing Python For Data Science Is An Important Move
5 Ways to Make Big Data Investment Work For Your Organization
Technologies and Analyses in CBS’ Person of Interest

One of the biggest uses for Spark is also computing a result across nodes and aggregating the results.

Normal variables are mutable, which means that it’s possible to modify them. The ability of slave nodes to change data instead of merely computing the results can cause all kinds of problems and side effects, such as race conditions or comprehension difficulties for programmers. Accumulators solve the problem by making it impossible for slave nodes to change the data. The slave nodes can’t even see the accumulator; they’ll just fetch the data and send it back to the slave node, which can see and change the information in the variables.

Use Case: Log Errors

So what would you use an accumulator for? A good example is for counting items that occur in your data. Searching through text files is another good example. If you’re a sysadmin, you’re probably accustomed to using tools like grep to sift through your log files, looking for things like errors and possible security problems. You might even have created some custom scripts that can look for these errors.

If you manage a large data center, how are you going to look through each node, when there may be hundreds or even thousands of log files? Spark can make this a possibility, but how will you be sure that the number of errors is accurate and that some node didn’t somehow create problems?

Accumulators will come to the rescue here.

We’ll get to see them in action. A similar example for counting in log files is in MapR’s Apache Spark cheat sheet.

We have our log file that contains the terms like “error, warning, info,” etc.

Here’s a contrived example, with just these terms in a text file, each on one line:

error
warning
info
trace
error
info
info

This log is named output.log and saved in the home directory. In real life, it could be a web server log, a system log, or any other kind of log with thousands of lines.

At the Scala prompt, we’ll define the accumulator that will count the number of errors and call it nErrors:

scala> val nErrors=sc.accumulator(0.0)

You’ll notice that it’s a floating-point number. We could have easily just used 0 instead of 0.0, as there isn’t really such a thing as a fractional error. This is merely a way to show that you can choose both integers and floating point for your accumulators.

Next, let’s import our log into Spark and convert it to an RDD:

scala> val logs = sc.textFile(“/Users/ddelony/output.log”)

Now we’ll look through the logs.

The slave nodes will look through a line, add 1 if it finds “error” in it, and send the result back to the master, which will then add them all up:

scala> logs.filter(_.contains(“error”)).foreach(x=>nErrors+=1)

Now let’s see how many errors are in our log:

scala> nErrors.value
Result: Int = 2

We could easily modify this to look for warnings and traces, and with much longer files.

Broadcast Variables

A related idea in Spark is the broadcast variable. A broadcast variable, as the name suggests, is broadcast from a master node to its slaves. Broadcast variables avoid the network bottlenecks when aggregating data. These variables let slaves quickly access RDD data and send the results back to the master.

Broadcast variables are frequently used for mapping operations. You create them with the sc.broadcast() command, as with accumulators, the initial value as an argument.

Conclusion

Both accumulators and broadcast variables can make advanced operations on large clusters faster, safer, and more reliable using Apache Spark. Learn more about real-time security log analytics with Spark.


TAGGED:big datadata mining
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article is about joining public web signals with internal business metrics so BI teams can inter
Alternative Data in BI: Bringing Public Web Data Into Your Dashboards
Big Data Business Intelligence Exclusive Web Analytics
Flat editorial illustration: A SaaS-editorial scene showing product usage, support patterns, and renewal feedback informing a fle
Using Product Usage Analytics and Support Data to Build a B2B Product Roadmap
Business Intelligence Infographic
From Hiring To Payroll: Managing HR Data Across Business Systems -- AI-generated illustration
From Hiring To Payroll: Managing HR Data Across Business Systems
Big Data Business Intelligence Infographic
Flat editorial illustration: The article is about automating the collection, preparation, and delivery of marketing data across p
From Data to Dashboards: 5 Marketing Reporting Automation Software Picks
Big Data Business Intelligence Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

5 Best Practices for Extracting, Analyzing, and Visualizing Data
Data Visualization

5 Best Practices for Extracting, Analyzing, and Visualizing Data

6 Min Read
AI And Augmented Reality Merge For New Business Solutions
Artificial IntelligenceBig DataBusiness IntelligenceExclusiveKnowledge Management

AI And Augmented Reality Merge For New Business Solutions

7 Min Read
3 Ways Generation Z Entrepreneurs Are Capitalizing Off Big Data
Big DataExclusiveNews

3 Ways Generation Z Entrepreneurs Are Capitalizing Off Big Data

5 Min Read
Big Data Sources: 20 Free Data Sources and Where to Find Them -- AI-generated illustration
Big Data

Big Data Sources: 20 Free Data Sources and Where to Find Them

41 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive
From Bolts to Bots: How AI Is Fortifying the Automotive Industry
Artificial Intelligence

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?