We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Big Data Ingestion… or Indigestion?
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Uncategorized > Big Data Ingestion… or Indigestion?
Uncategorized

Big Data Ingestion… or Indigestion?

Gayle Nixon
Gayle Nixon
5 Min Read
Big Data Ingestion... or Indigestion?
Illustration generated with FLUX.2 [klein 4B] via Cloudflare Workers AI.
SHARE

With the exception of those special few with iron stomachs, any rapid ingestion of a wide variety of rich, exotic foods can cause a lot of discomfort for quite a while. The same is true of data ingested into Hadoop.

With the exception of those special few with iron stomachs, any rapid ingestion of a wide variety of rich, exotic foods can cause a lot of discomfort for quite a while. The same is true of data ingested into Hadoop. Organizations are piling high volumes of diverse, disparate data sources into Hadoop at rapid speeds, but their inability to find value amidst all of that information is causing a fair amount of distress and uneasiness among both business and technical leaders.

One way to ease pains following data ingestion into Hadoop is to apply rigorous, scalable data quality methodologies to your Hadoop environment. This will ensure data is reliable for downstream use in business applications. In my last Big Data blog, I talked about how traditional principles of data quality and data governance are a necessity for Big Data and Hadoop. However, given all of the new data sources and applications associated with Big Data, newer approaches to data quality and governance are necessary as well. Here are a few considerations to help you more easily digest all of your business information in a Big Data environment:

A critical first step is to relinquish data quality processing during the ingestion phase. Traditionally, data quality applies during migration processes as data is sent to data warehouses and relational databases. Given the volume of information associated with Big Data, it is no longer operationally efficient to apply data quality during ingestion into Hadoop. The time and cost associated with record-by-record data quality processing would hinder your efforts and detract from the increased processing performance and efficiency that are part of the core value of Hadoop.
More Read

Web services should be both federated and extensible
Monitoring a System
Search with Slashtags: Taking Blekko Out for a Spin
Big Analytics Rather Than Big Data
Stupid Analytics Gets Them Talking

Next, Hadoop adopters should shift to data quality processing once data is ingested into Hadoop. Evidence of this is found in a recent TDWI Best Practices Report for Hadoop reported that the most prevalent data quality strategy among Hadoop adopters is to “ingest data immediately into Hadoop, and improve it later as needed” as opposed to improving data before it enters Hadoop. Native data quality processing ensures business rules are applied across all records on all nodes of your cluster, enabling real-time processing and supporting accurate, real-time analytics and business process that Big Data is meant to support. It also ensures that external, third-party reference data sources undergo the same data quality processing as data sets that are ingested from internal data sources.

With so many types of data entering Hadoop, it’s also important to recognize that data quality has to be tailored to different data types, and traditional data quality rules may no longer be widely applicable to all types of data. For example, unstructured data may have more value in its raw, unedited form, and certain data inaccuracies or “errors” might provide useful information about an inefficient process or product. But, if you’re like most organizations, leveraging Big Data to learn more about your customers, both accuracy and data linking are critical steps to extracting value from a wide array of data points. One of the key benefits of data quality for Big Data is the confluence of disparate data points into a single, clearer version of the truth that will help you build a better customer experience, stronger customer interactions, and more targeted marketing campaigns.

By combining traditional data quality concepts to the new nuances and intricacies of Big Data, you can keep Hadoop healthy and minimize the downstream impacts of dirty data.

by Denise Laforgia, Product Marketing Manager, Trillium Software
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

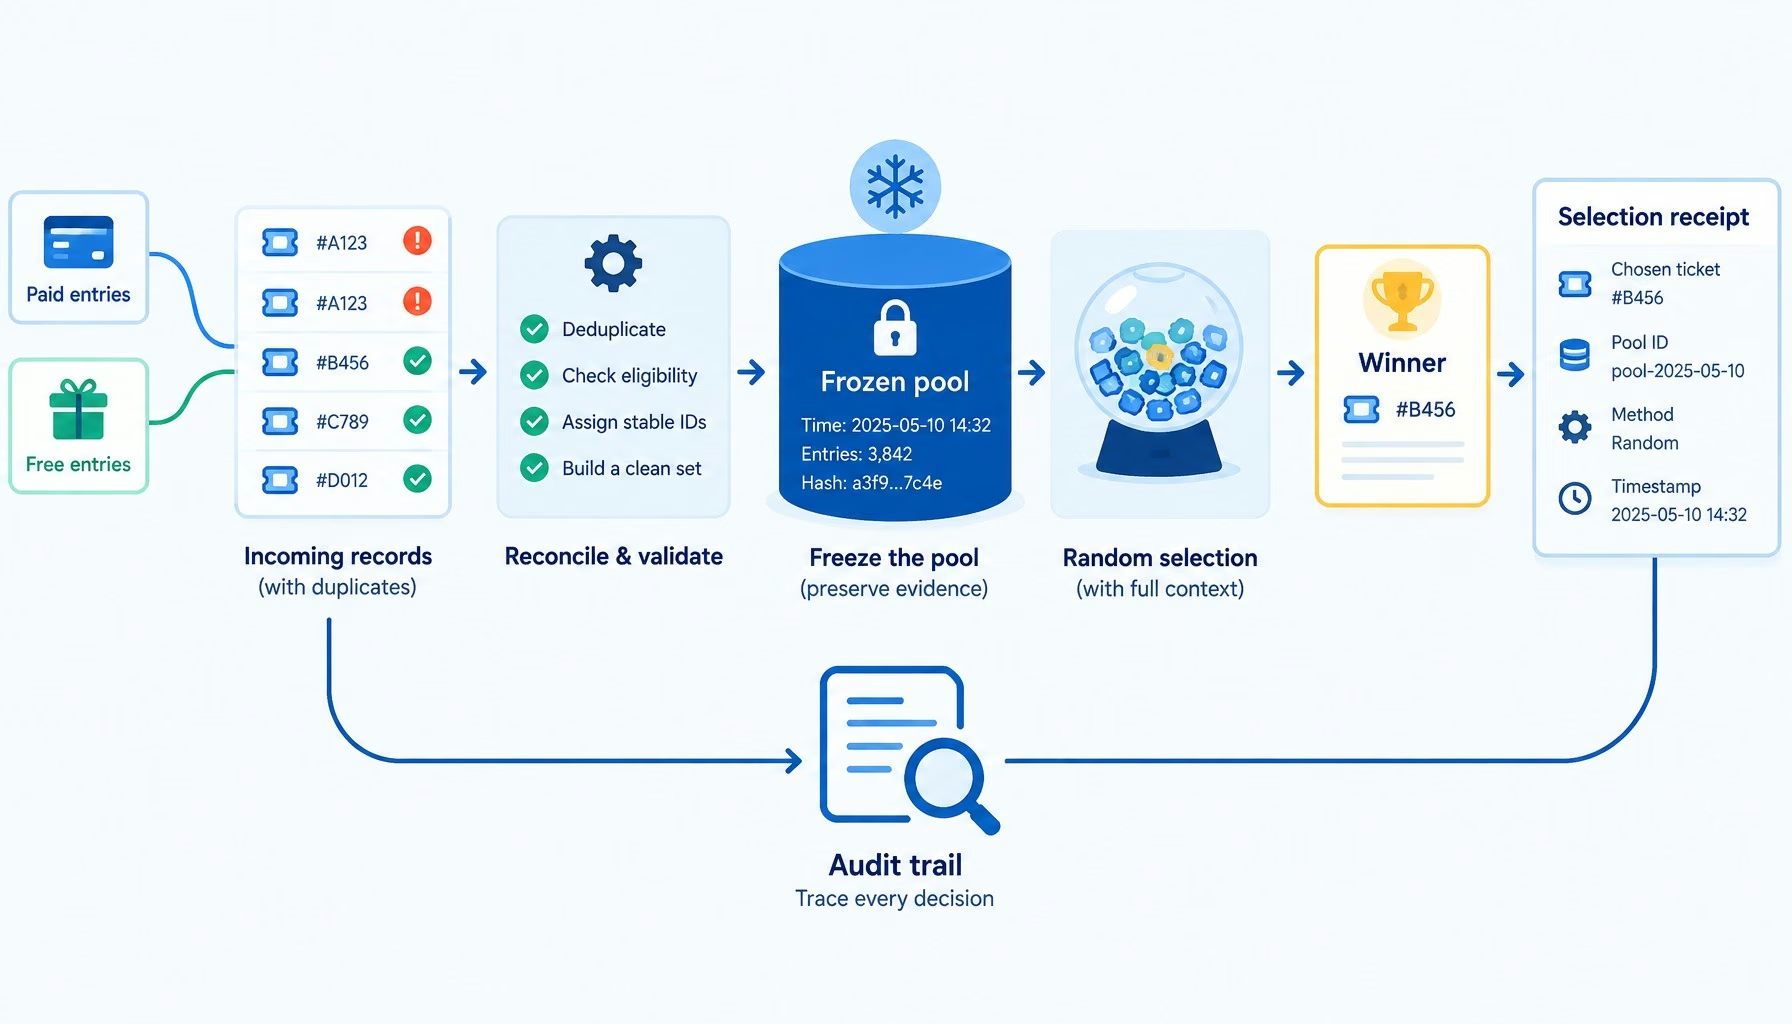
Technical architecture diagram and decision framework for data engineering for prize draws: building an audit trail
Data Engineering for Prize Draws: Building an Audit Trail
Big Data
Technical architecture diagram and decision framework for the trouble with ai that won’t leave a job unfinished
The Trouble With AI That Won’t Leave a Job Unfinished
Artificial Intelligence News
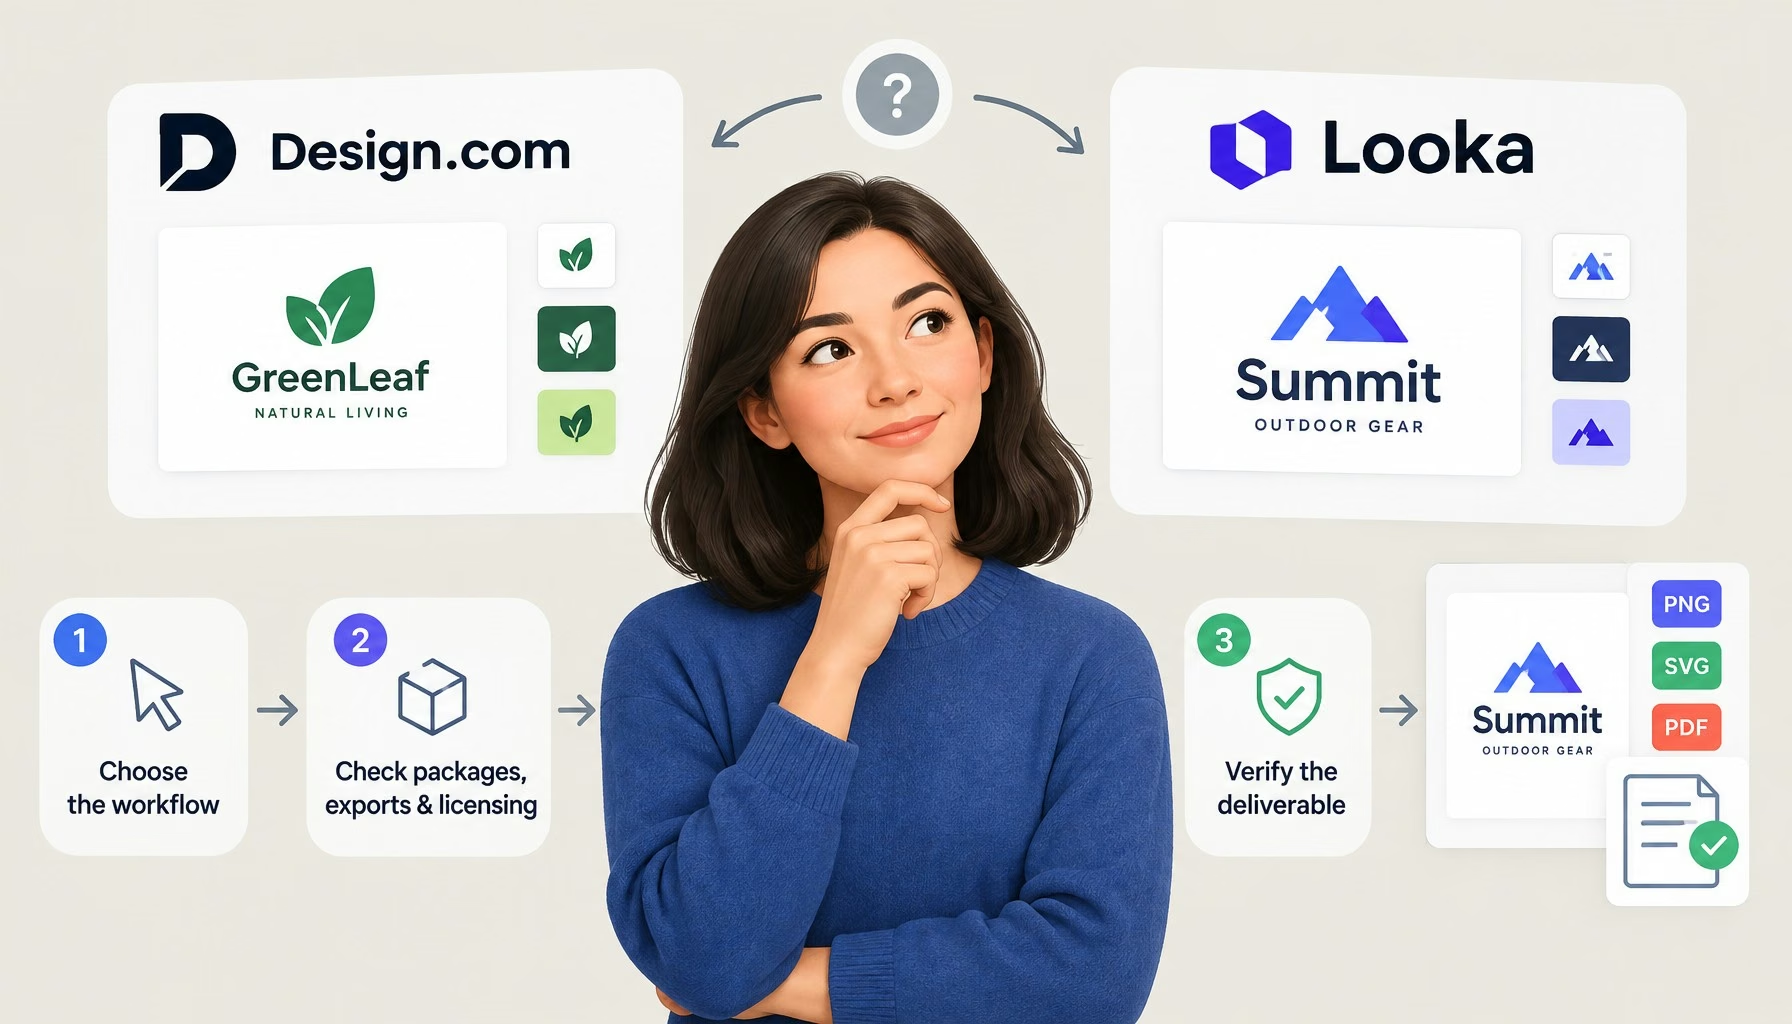
Technical architecture diagram and decision framework for ai-powered logo generation: design.com vs looka
AI-Powered Logo Generation: Design.com vs Looka
Artificial Intelligence Exclusive
Retailers Should Stop Treating Every Stockout as Equal -- AI-generated illustration
Retailers Should Stop Treating Every Stockout as Equal
Business Intelligence Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Why Bad Data Is Wasting Your Marketing Efforts
Uncategorized

Why Bad Data Is Wasting Your Marketing Efforts

8 Min Read
Google Surprise: A change in intent regarding China
Uncategorized

Google Surprise: A change in intent regarding China

5 Min Read
Is Cloud Sameness Dangerous to Competitive Advantage?
Uncategorized

Is Cloud Sameness Dangerous to Competitive Advantage?

5 Min Read
No Data, No Problem (Pt 2) – Your region/division/unit is not special.
Uncategorized

No Data, No Problem (Pt 2) – Your region/division/unit is not special.

7 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

ai chatbot
How AI Website Chatbots Improve Customer Support and Lead Generation
Chatbots Exclusive
From Bolts to Bots: How AI Is Fortifying the Automotive Industry
Artificial Intelligence

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?