We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Training students on mega-scale data
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Uncategorized > Training students on mega-scale data
Uncategorized

Training students on mega-scale data

DavidMSmith
DavidMSmith
3 Min Read
Training students on mega-scale data
Illustration generated with FLUX.2 [klein 4B] via Cloudflare Workers AI.
SHARE

In a New York Times article (sub. req.) published on the weekend, IBM and Google expressed doubts that the students graduating from US universities today have the chops to deal with the mulit-terabyte datasets that are becoming commonplace online and in domains like bioscience and astronomy today. From the article:

For the most part, university students have used rather modest computing systems to support their studies. They are learning to collect and manipulate information on personal computers or what are known as clusters, where computer servers are cabled together to form a larger computer. But even these machines fail to churn through enough data to really challenge and train a young mind meant to ponder the mega-scale problems of tomorrow.

The article reveals how Google and IBM are promoting internet-scale research at places like the University of Washington and Purdue. But a curious omission from the article is any mention of open-source technologies that are spurring the innovation in processing and analyzing these data sets. Tools like Hadoop, for processing internet-scale data sets and R, for analyzing the processed data (most likely in some parallelized form), and other open-source projects not yet conceived, are going to be critical in this endeavour.

New York Times: Training to Climb an Everest of Digital Data

More Read

More problems for Googlemail
Data Modeling with Generalizations – The Tool Issue
An Overview of ServiceNow Reporting Approaches
How are data transformations represented in PMML?
Data, data everywhere, but where is data quality?
TAGGED:googlehadoopibmnew york timesr
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

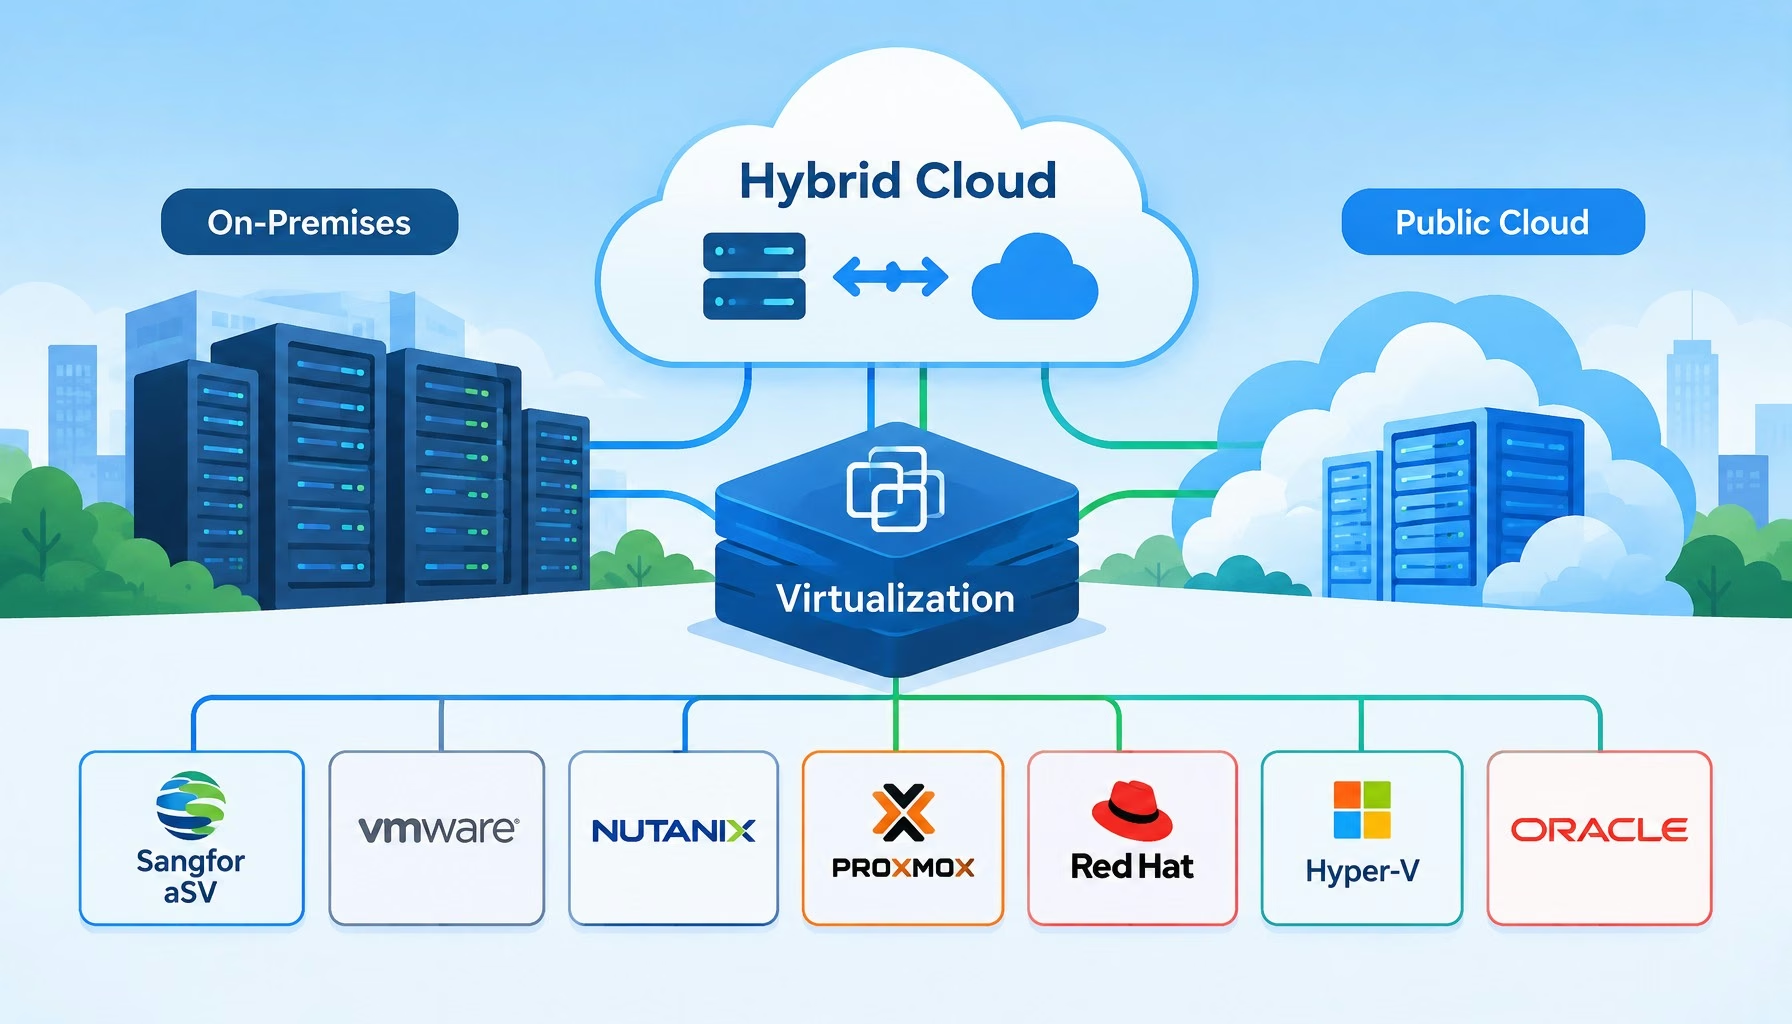
Flat editorial illustration: The article's core relationship is the hypervisor as the abstraction layer that makes hybrid cloud p
7 Best Virtualization Platforms for Hybrid Cloud Environments
Big Data
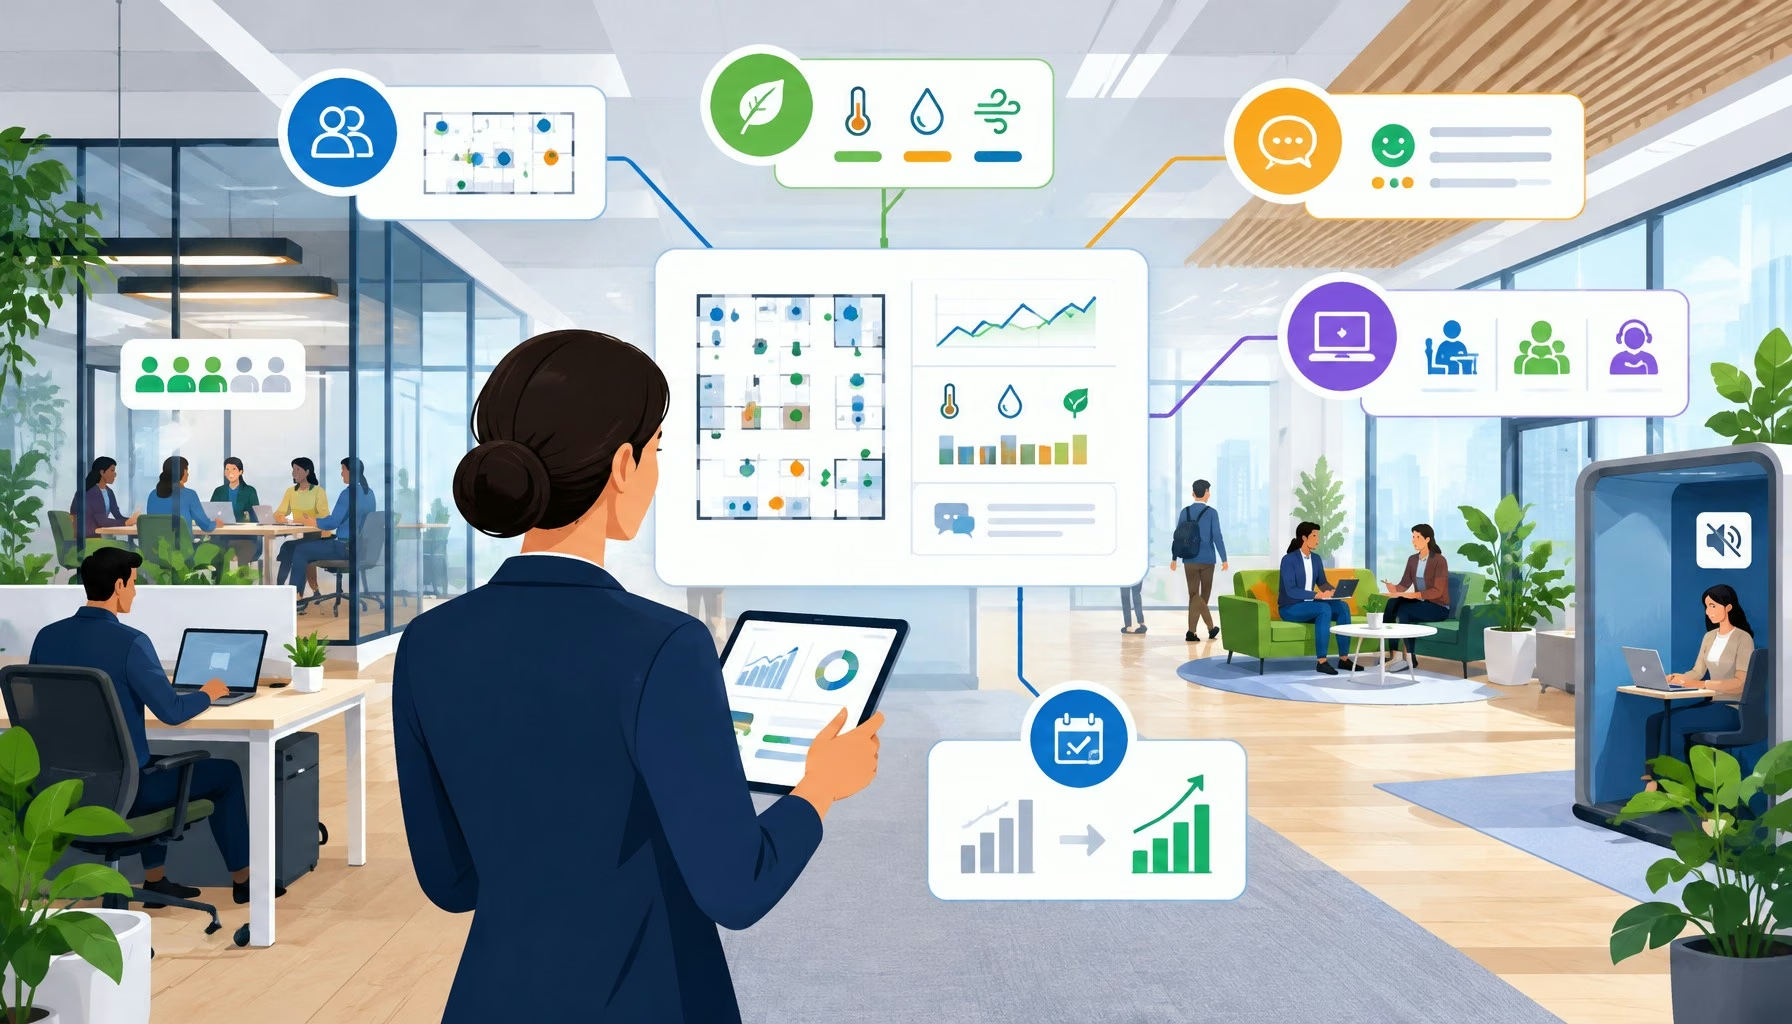
Flat editorial illustration: The article's core relationship is between aggregated workplace data (occupancy, environmental, feed
How Businesses Can Use Workplace Data to Create Better Office Environments
Big Data Business Intelligence Exclusive
Flat editorial illustration: The article's core relationship is the engineering transition from an AI prototype to a production-r
From AI Prototype to Production: Observability and Scalability Requirements for Data-Heavy SaaS Applications
Artificial Intelligence Exclusive
Preparing Data Systems and Governance for a Scaling Global Gaming Brand -- AI-generated illustration
Preparing Data Systems and Governance for a Scaling Global Gaming Brand
Big Data Infographic

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

4 Retail BI Lessons to Learn from Google's Nexus Fail
Uncategorized

4 Retail BI Lessons to Learn from Google’s Nexus Fail

5 Min Read
Why This Snaky Python Language?
Business IntelligenceData MiningPredictive Analytics

Why This Snaky Python Language?

6 Min Read
What does Google know about you?
Data MiningExclusive

What does Google know about you?

5 Min Read
Applications of R at Google
R Programming Language

Applications of R at Google

3 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

The Art of Conversation: Enhancing Chatbots with Advanced AI Prompts
Chatbots
Artificial Intelligence for eCommerce: A Closer Look
Artificial Intelligence

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?