We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Text Mining on Financial News
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Uncategorized > Text Mining on Financial News
Uncategorized

Text Mining on Financial News

ThemosKalafatis
ThemosKalafatis
5 Min Read
Text Mining on Financial News
Illustration generated with Qwen Image.
SHARE

As discussed previously, an analyst should give specific attention to problem representation particularly when we are dealing with text data. We are going to discuss a way to do this. However, something has to give and there is no perfect solution for this task.

First of all we have to find the source of the news : It could be financial news sites such as Bloomberg, Financial Times, or RSS Feeds URLs such as the ones provided by MarketWatch. RSS Feeds might be a better solution because there is already some predetermined categorization of news according to the feed type and this can be great help for some analysts.

After finding the news sources and making the necessary code to get the actual information we could end up with the following text file :


You can see that i use a ‘^’ separator to differentiate between :

1) A date stamp,
2) A date string
3) The news string
4) A characterization of the news (important or unimportant)
5) A categorization of the financial news.

This simple file could provide the basis for a training file for text categorization. Assuming that we have trained algorithms to automatically classify news, we could use a news classifier to first categorize news to important or unimportant and pass only the important news to a second classifier which will do the detailed classification of the news.

Another option is to use clustering : You can imagine that the solution detailed above has a tremendous amount of work depending on how much data you are planning to collect…so too much data means too much work, less data could mean -usually but not always- less accuracy.

But how could clustering be performed on such data? Simply, we just use field number (4) on our training text file to train a clustering algorithm and then see what ‘classes’ the algorithm has come up with.

So let’s see a small example about clustering : This is a capture from WEKA just before the clustering process :


As you can see i have produced a training file which essentially contains the ‘buzzwords’ of financial news : barrel, recession, Yen, Euro, ECB, price, consumer, etc. The file is then analyzed by K-means algorithm to extract clusters of the same ‘buzzwords’. Each cluster is assigned a number so each news header ultimately falls onto one cluster number.

After running the K-Means algorithm i ended up with 16 clusters. Let’s see two instances that K-Means decided that they should fall under cluster ‘6’ :

Instance_number : 130.0

Fear
Decrease
US
Economy
Futures

and

Instance_number : 174.0

Fear
Decrease
US
Price
Oil
Banking
Recession

So the first instance is about fear of drop in US Economy which results in Futures in US dropping and the second instance must be -something about- a decrease of Oil prices and Banking stocks because of the fear of US recession. Not bad at all…

But not so fast : Clustering presents a lot of problems later in the process. Remember that what we are after, is to combine text mining and data mining together to better understand how the markets react. Should one use classification or clustering? There are many more things to take under consideration and for obvious reasons i cannot disclose all the details of such a project…but i am hoping to give to the interested reader a good enough introduction on the subject.
Link to original post

Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is workload-by-workload decision-making for cloud migration, where s
Which Workloads Should Move to the Cloud?
Cloud Computing Exclusive IT
Flat editorial illustration: The article positions data governance as a strategic board-level concern rather than a purely techni
Why Data Governance Is Becoming a Board-Level Business Priority
Big Data Exclusive Policy and Governance
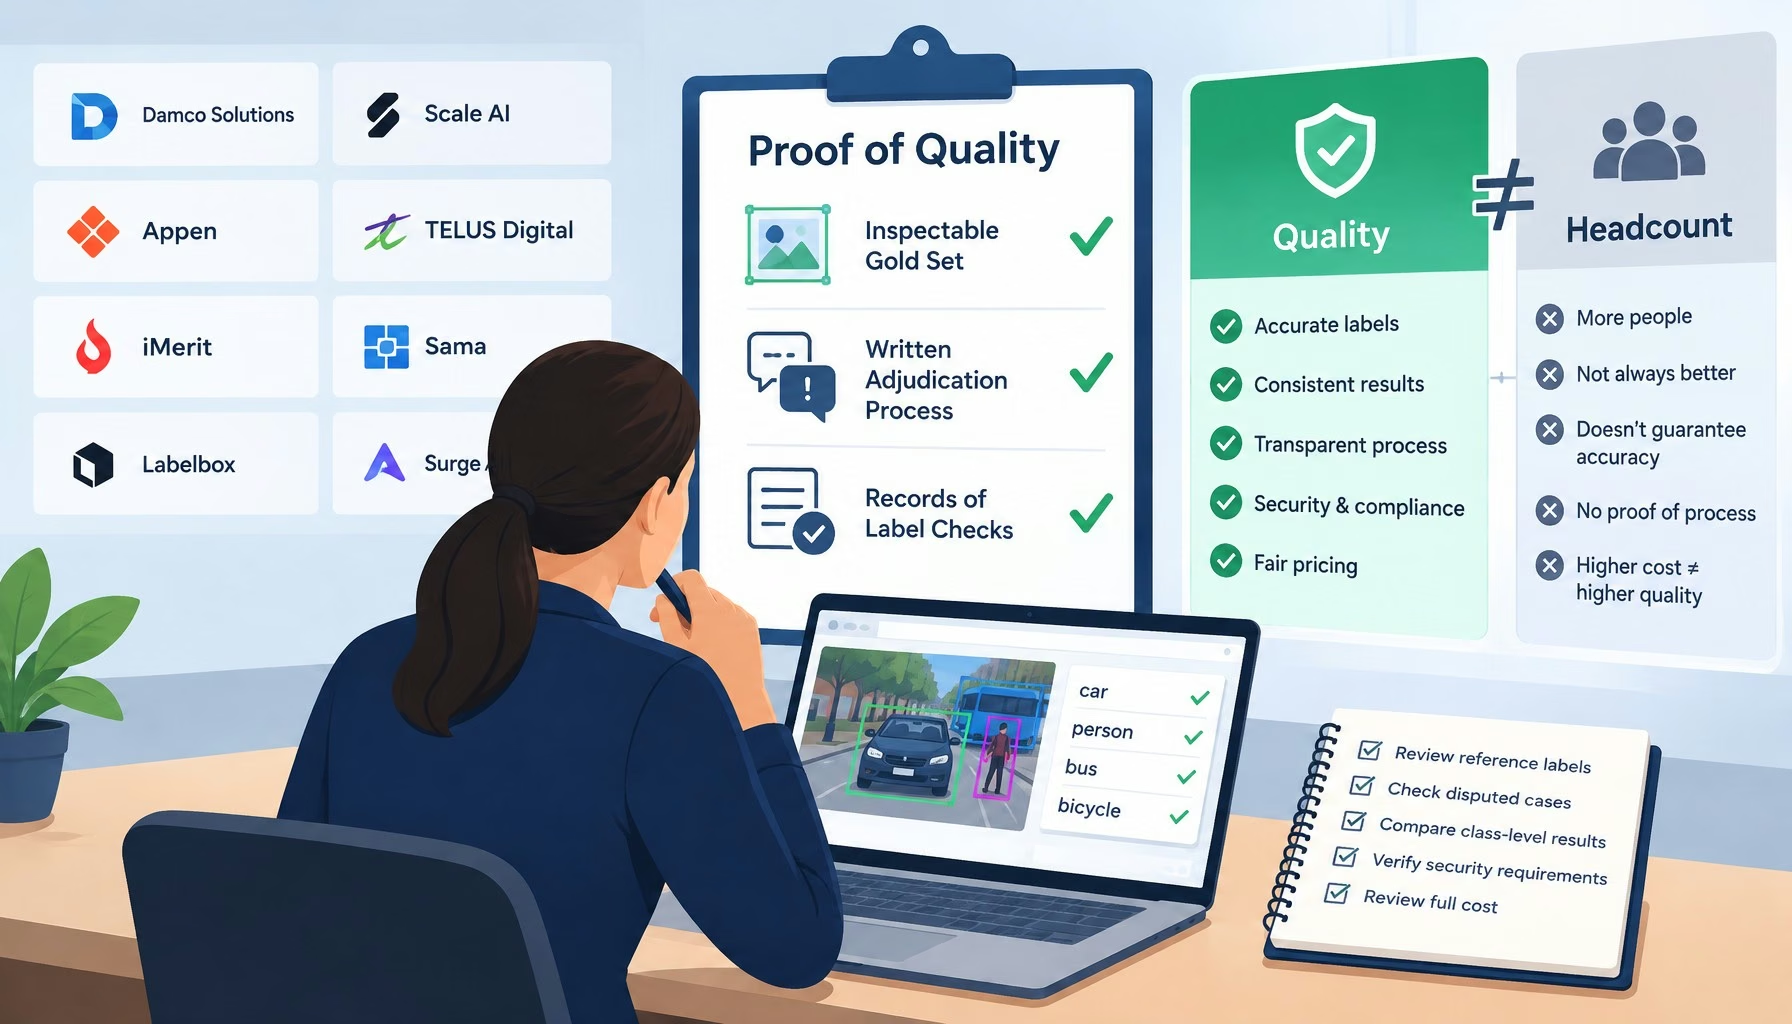
Flat editorial illustration: The article argues that data annotation quality should be measured by inspectable gold sets, written
The Top Data Annotation Companies Are Separated by Proof of Quality, Not Headcount
Big Data Exclusive
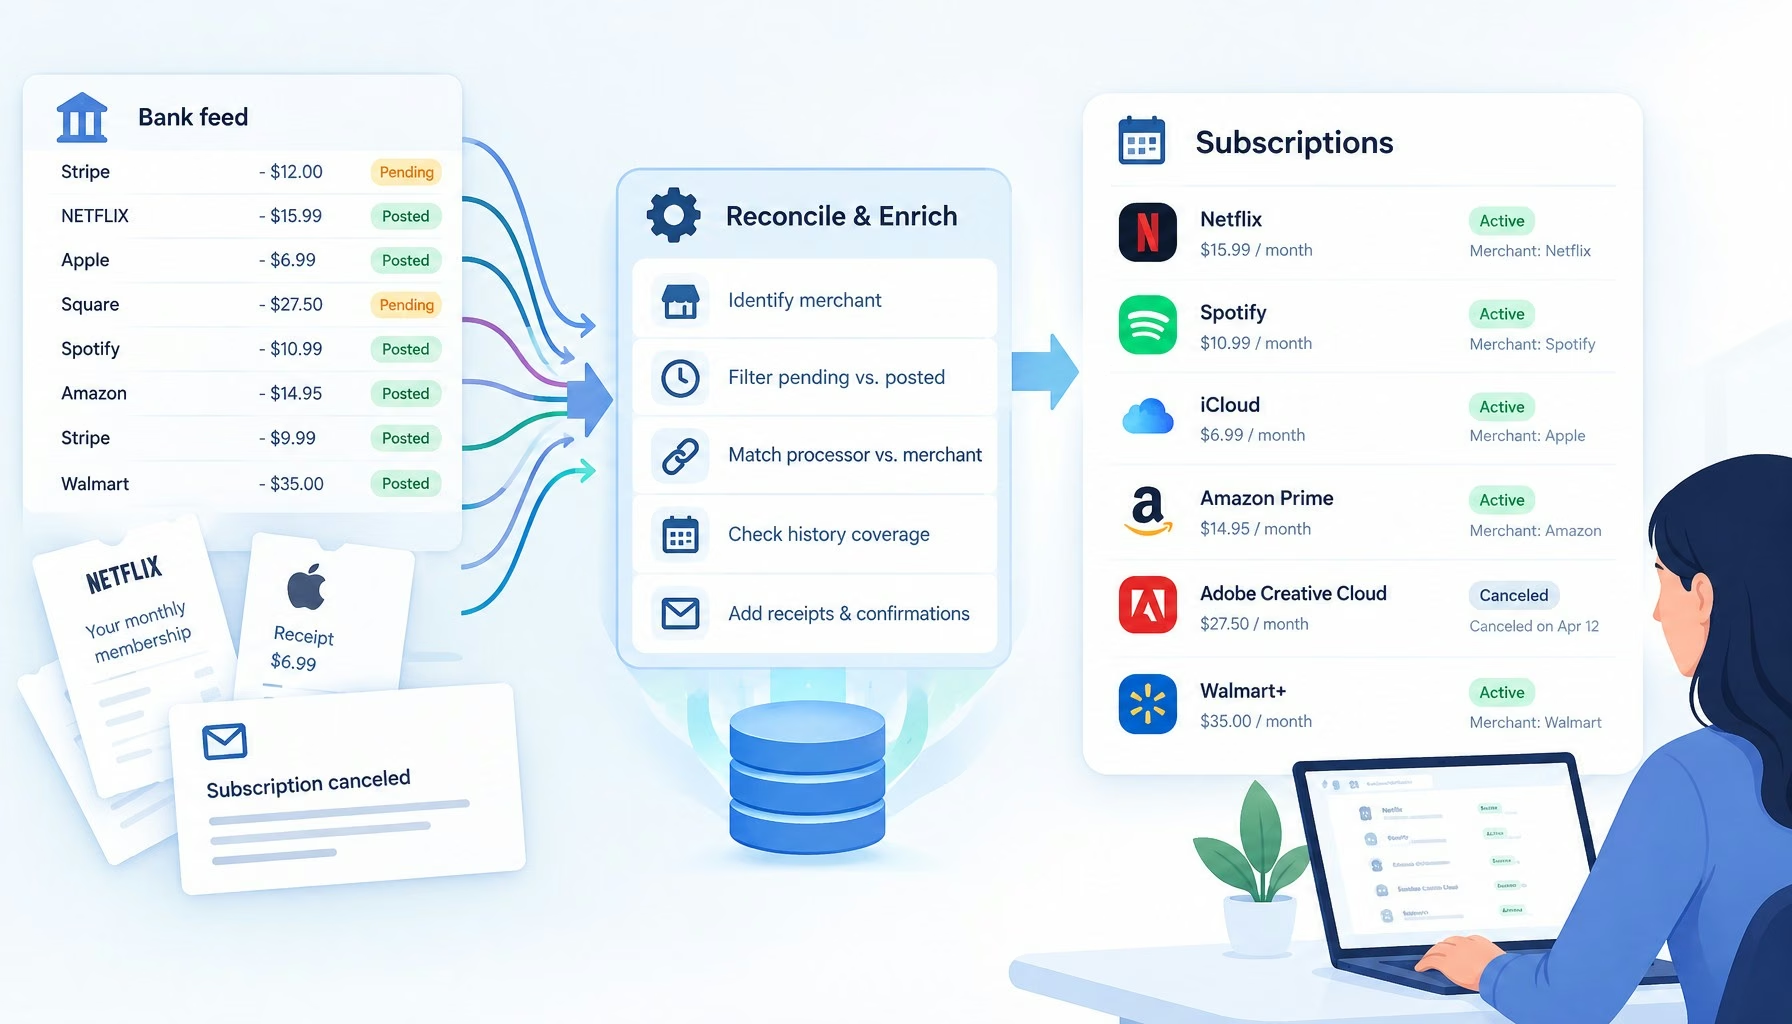
Flat editorial illustration: The article's core relationship is the gap between raw bank-feed records and reliable subscription i
Subscription Trackers Have a Transaction Data Problem
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Cisco Announces “Significant Innovations” in its Unified Computer Servers Exclusively for Data Centers
Uncategorized

Cisco Announces “Significant Innovations” in its Unified Computer Servers Exclusively for Data Centers

3 Min Read
Kotter and the Knowing-Doing Gap
Uncategorized

Kotter and the Knowing-Doing Gap

5 Min Read
My Interview with Ajay Ohri
Uncategorized

My Interview with Ajay Ohri

6 Min Read
Web services should be both federated and extensible
Uncategorized

Web services should be both federated and extensible

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

AI chatbots
AI Chatbots Can Help Retailers Convert Live Broadcast Viewers into Sales!
Chatbots
How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?