We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Panos Ipeirotis Speaking at LinkedIn about Crowdsourcing!
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Business Intelligence > Knowledge Management > Panos Ipeirotis Speaking at LinkedIn about Crowdsourcing!
Knowledge Management

Panos Ipeirotis Speaking at LinkedIn about Crowdsourcing!

Daniel Tunkelang
Daniel Tunkelang
4 Min Read
Panos Ipeirotis Speaking at LinkedIn about Crowdsourcing!
Illustration generated with FLUX.2 [Klein 9B] via local ComfyUI.
SHARE

Sharing knowledge is part of our core culture at LinkedIn, whether it’s through hackdays or contributions to open-source projects. We actively participate in academic conferences, such as KDD, SIGIR, RecSys, and CIKM, as well as industry conferences like QCON and Strata.

Beyond sharing our own knowledge, we provide a platform for researchers and practitioners to share their insights with the technical community. We host an Tech Talk series at our Mountain View headquarters that we open up to the general public. Some of our recent speakers include Coursera founders Daphne Koller and Andrew Ng, UC-Berkeley professor Joe Hellerstein,  and Hadapt Chief Scientist Daniel Abadi. It’s an excellent opportunity for people with shared professional interests can reconnect with people they know, as well as make new connections. For those who cannot attend, we offer a live stream.

Our next talk will be by Panos Ipeirotis, a professor at NYU and one of the world’s top experts on crowdsourcing. Here is a full description:

Crowdsourcing: Achieving Data Quality with Imperfect Humans
Friday, September 7, 2012 at 3:00 PM
LinkedIn (map)
More Read

Documents: Your Information Lifeblood
3 Secrets of a Successful Business Intelligence Strategy
Big Data and the SME: Prepare to Succeed
Great Analytics Vendors: 5 Must-Have Traits
How to Improve Your Receivables Position With Better Risk Analysis

Crowdsourcing is a great tool to collect data and support machine learning — it is the ultimate form of outsourcing. But crowdsourcing introduces budget and quality challenges that must be addressed to realize its benefits.

In this talk, I will discuss the use of crowdsourcing for building robust machine learning models quickly and under budget constraints. I’ll operate under the realistic assumption that we are processing imperfect labels that reflect random and systematic error on the part of human workers. I will also describe our “beat the machine” system engages humans to improve a machine learning system by discovering cases where the machine fails and fails while confident on being correct. I’ll use classification problems that arise in online advertising.

Finally, I’ll discuss our latest results showing that mice and Mechanical Turk workers are not that different after all.

Panos Ipeirotis is an Associate Professor and George A. Kellner Faculty Fellow at the Department of Information, Operations, and Management Sciences at Leonard N. Stern School of Business of New York University. His recent research interests focus on crowdsourcing and on mining user-generated content on the Internet. He received his Ph.D. degree in Computer Science from Columbia University in 2004, with distinction. He has received three “Best Paper” awards (IEEE ICDE 2005, ACM SIGMOD 2006, WWW 2011), two “Best Paper Runner Up” awards (JCDL 2002, ACM KDD 2008), and is also a recipient of a CAREER award from the National Science Foundation.

If you’re in the Bay Area, I encourage you to attend in person — Panos is a great speaker, and it’s also a great opportunity to network with other attendees. If not, then you can follow on the live stream.

The event is free, but please sign up on the event page. See you next week!
TAGGED:crowdsourcinglinkedin
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article connects AI-generated avatar variants with disciplined, measurable video experiments. A
How to Use an AI Avatar Generator to Run Measurable Video Experiments
Artificial Intelligence Exclusive
Flat editorial illustration: The article’s core relationship is between growing compute density and adaptable rack hardware that
6 Details That Make a Data Centre’s Server Room Easier to Scale
Best Practices Data Management Exclusive IT
Flat editorial illustration: The article’s core relationship is a transfer of discipline from regulated laboratories to analytics
What Business Intelligence Teams Can Learn from Lab Data Governance
Business Intelligence Exclusive
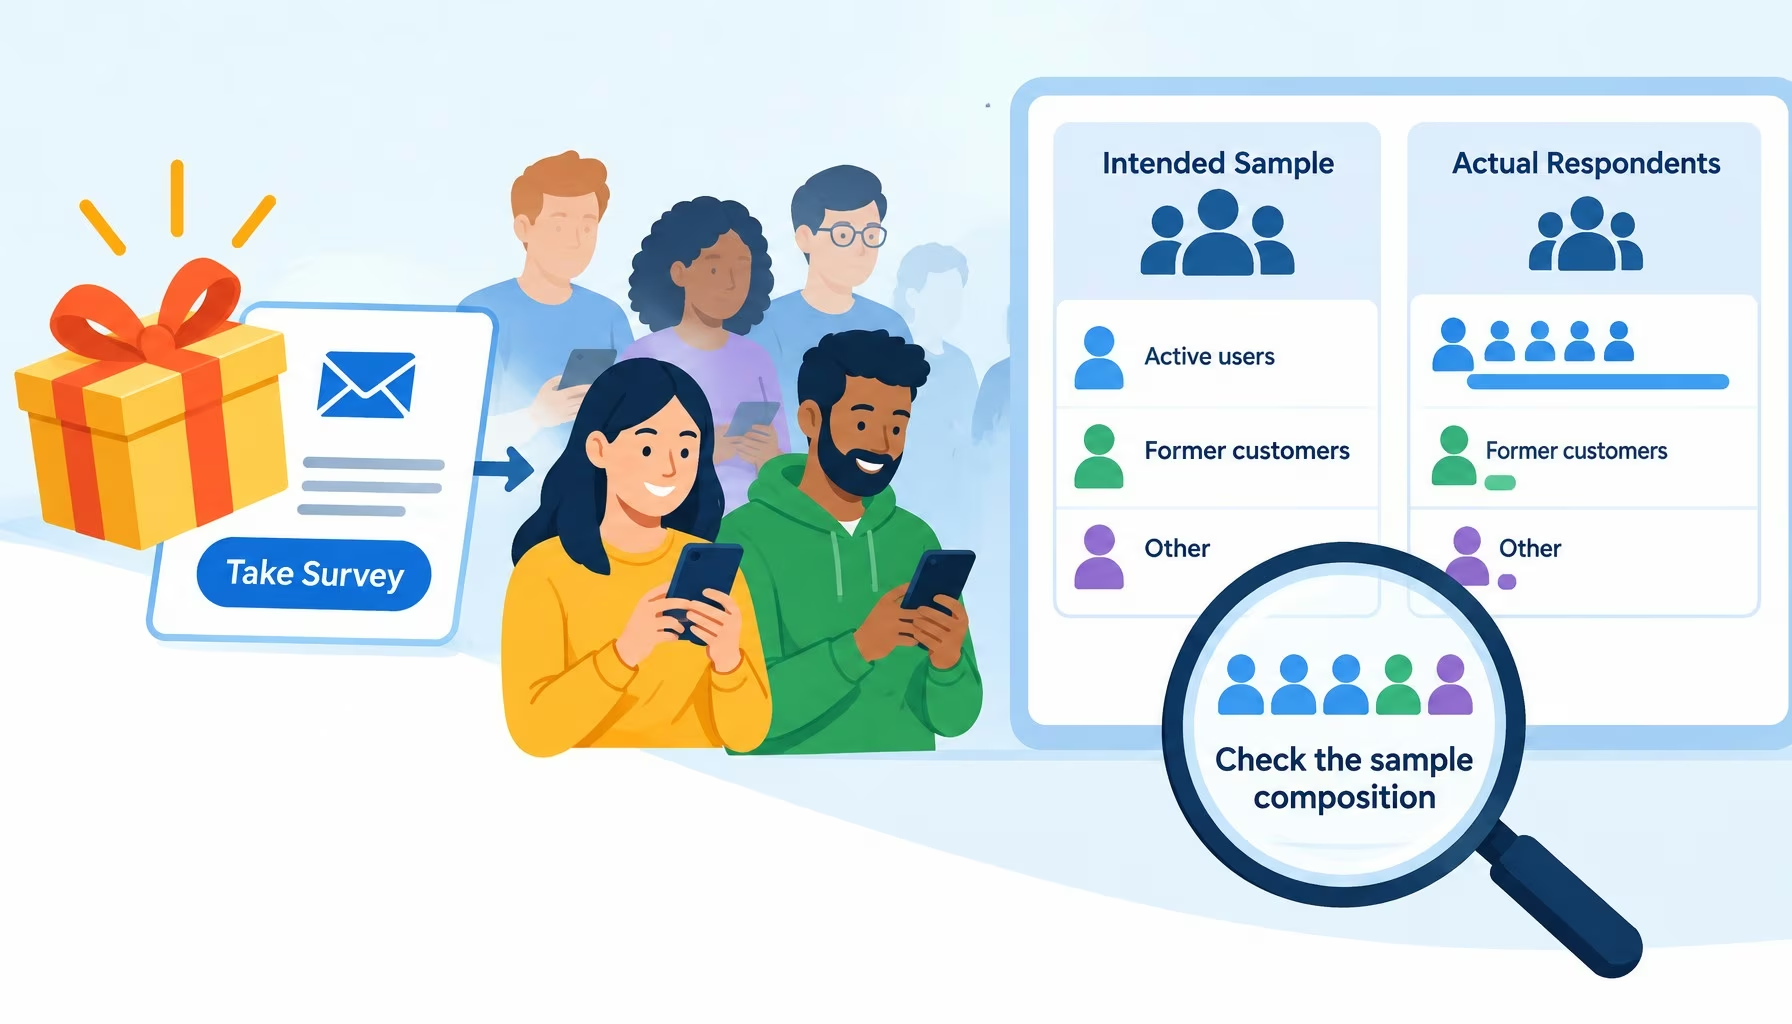
Flat editorial illustration: A guaranteed reward can raise participation while skewing the respondent pool toward active customer
Incentive-Driven Response Bias: Auditing Sample Composition Before You Trust Survey Data
Big Data Data Quality Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

#21: Here's a thought...
Data Mining

#21: Here’s a thought…

7 Min Read
Social Data on the Top 4 Social Media Channels: How They Use Each Other
AnalyticsBig DataExclusiveSocial DataSocial Media Analytics

Social Data on the Top 4 Social Media Channels: How They Use Each Other

4 Min Read
use AI to automate linkedin messaging
Artificial Intelligence

Implementing AI to Automate LinkedIn Messaging

10 Min Read
Turbo-Charge Data Scientist Productivity with a Data Catalog
Big DataData QualityPolicy and Governance

Turbo-Charge Data Scientist Productivity with a Data Catalog

8 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive
How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?