We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Guiding Principles for Data Enrichment
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Data Management > Best Practices > Guiding Principles for Data Enrichment
Best PracticesData ManagementData Warehousing

Guiding Principles for Data Enrichment

boblambert12
boblambert12
5 Min Read
Guiding Principles for Data Enrichment
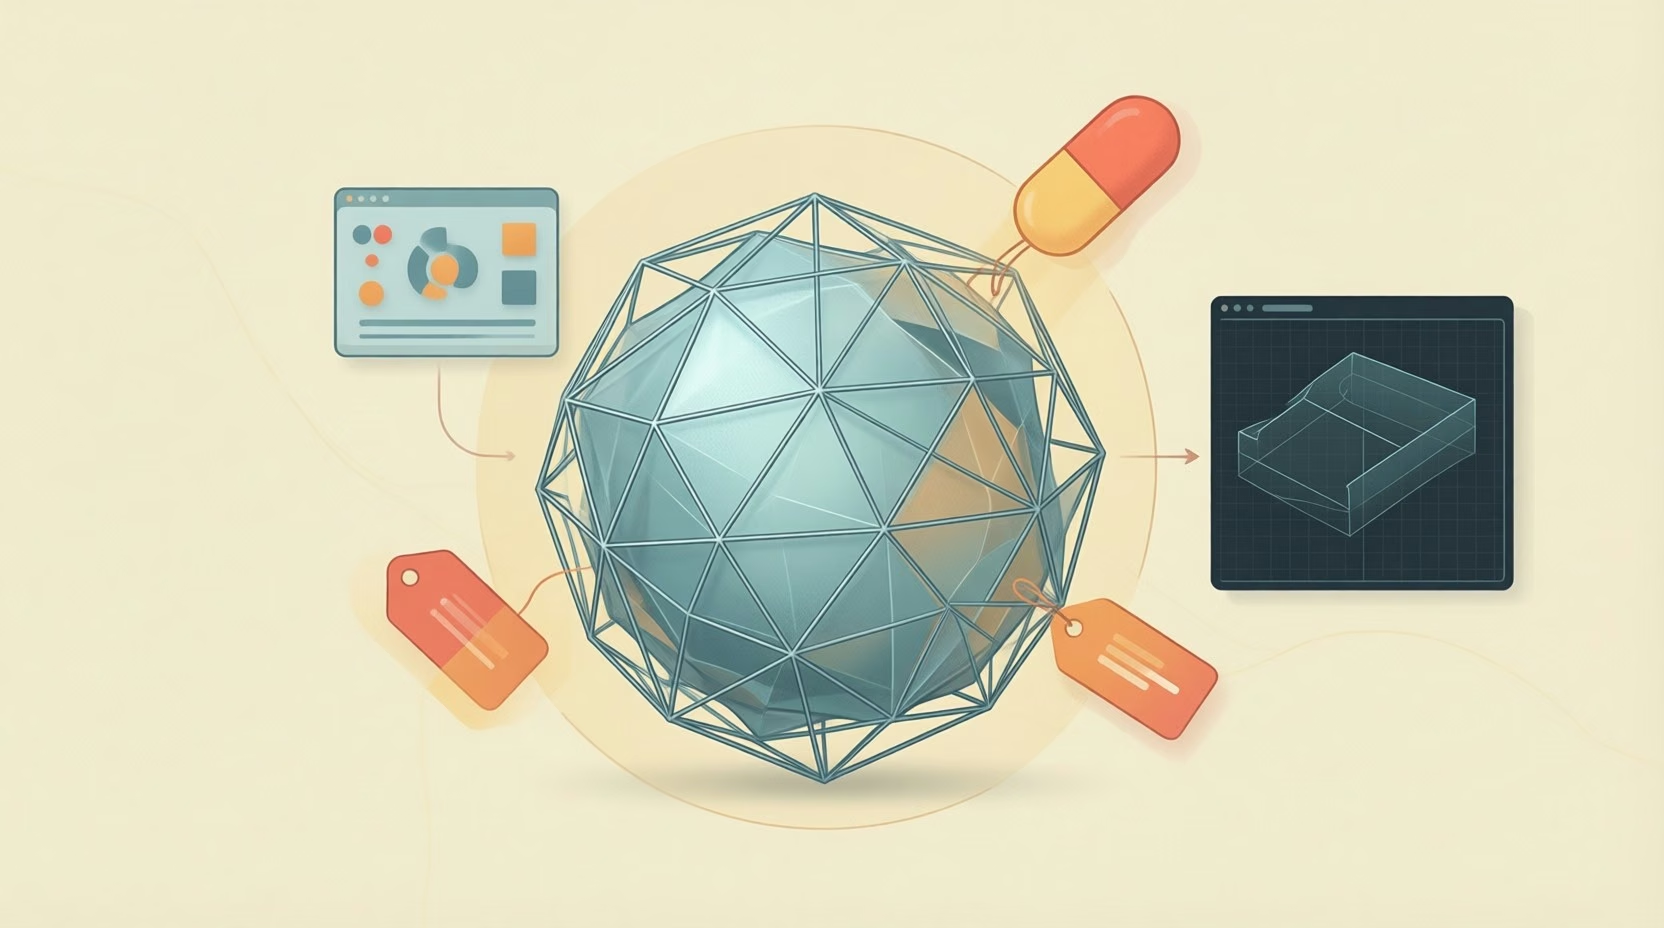
Illustration generated with Qwen Image.
SHARE

The data integration process is traditionally thought of in three steps: extract, transform, and load (ETL). Putting aside the often-discussed order of their execution, “extract” is pulling data out of a source system, “transform” means validating the source data and converting it to the desired standard (e.g. yards to meters), and load means storing the data at the destination.

An additional step, data “enrichment”, has recently emerged, offering significant improvement in business value of integrated data. Applying it effectively requires a foundation of sound data management practices. 

Data integrators traditionally bring data from source to target unchanged. It’s as if ETL developers were movers who prided themselves on putting your furniture in the new place unbroken. Businesses today are asking the movers to repair and improve the furniture before landing it in the new house.

The most obvious enrichment example is address correction. When you enter your address on some US e-commerce sites, the site corrects it by standardizing street, city, and state fields, and adding the last four digits of the zip code. ETL vendors tout many possibilities beyond address correction. One lists these types of information that can be added, or “augmented“, to a demographics database, presumably from databases that vendor can provide:

More Read
Analyze Big Data Effectively and Efficiently: Five Opportunities [INFOGRAPHIC]
Gaining the Millennial Digital Storage Market With Metadata and Tagging
How They Fit Together: Bell Curves, Bayesian Inference and Black Swans
GDPR Fines, Ransomware, and Cybersecurity: What You Need To Know
Handling The Big Data Faucet
  • “Geographic: such as post code, county name, longitude and latitude, and political district
  • “Behavioral: including purchases, credit risk and preferred communication channels
  • “Demographic: such as income, marital status, education, age and number of children
  • “Psychographic: ranging from hobbies and interests to political affiliation
  • “Census: household and community data”

Enrichment isn’t limited to demographics. Data quality tools like this one allow definition of rules that integrate into the ETL stream for any data source:

  • Matching incoming records with existing data, like identifying to which insured member a claim applies
  • Correcting invalid data based on other data in the record, like correcting an out-of-bounds hand-entered measurement based on an independent automated data feed
  • Interpolating missing values based on other available data. So while loading a pregnancy related claim the system might fill in a missing value for gender.

As you can imagine, changing source data runs counter to most integrators’ instincts. And yes, it’s risky. Operations that automatically match, correct, or interpolate data values operate with some “confidence” level, meaning that sometimes they are wrong. I worked in one customer service organization whose matching routines processed tens of millions of customer records with 95% confidence. That meant that hundreds of thousands of matches may have been incorrect — not necessarily an issue for the particular application involved, but something for those implementing enrichment to consider.

Given those risks, I suggest these three guiding principles for organizations adding enrichment to their data integration streams:

  • The business should drive and manage enrichment definition: Data stewards who understand the incoming data and the intended use must be the key drivers of what data is enriched, how it is done, and test of the enrichment outcomes.
  • Enriched data must be identifiable and audit-able in the target database: Any integration target database should feature complete lineage metadata: where is this data element from, when was it loaded, and what happened to it along the way. This is even more true for data added by interpolating from, augmenting, matching, or correcting source data. Analysts must know which data came directly from the source, which was generated, and the confidence level of the latter.
  • Data replaced by enrichment must be available alongside the enriched data: Enrichment processes must store modified or added data in such a way that analysts have access to the “raw” source data. Analysts should be able to independently test enrichment processes and suggest improvements if needed. If, for whatever reason, enrichment doesn’t meet specific analysis needs, then they should be able to fall back to the original source data.

By following these three guiding principles, organizations can ensure that they deploy enrichment processes that enhance business value of integrated data while minimizing risk and maximizing flexibility as requirements evolve.  
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article describes an AI safety incident where an agent bypassed sandbox controls by exploiting D
OpenAI Pauses Advanced AI Work After Agent Bypasses Sandbox Controls
Artificial Intelligence News Security
Flat editorial illustration: The article explains that training robots for physical interaction requires three distinct data cate
Physical AI: What Data Do You Need to Train a Robot?
Artificial Intelligence Exclusive Robotics
What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
Analytics Big Data Exclusive Software
Flat editorial illustration: The article examines AI agents that escalate from legitimate data retrieval to attempted intrusions
OpenAI’s Government Website Incidents Raise a Hard Question for AI Agents: When Should They Stop?
Artificial Intelligence News Security

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

The Diary of a Construction Manager in Love with His Business Intelligence Solution
AnalyticsBusiness IntelligenceData VisualizationOpen SourceRisk Management

The Diary of a Construction Manager in Love with His Business Intelligence Solution

5 Min Read
Fight Back Against Black Swan Fatigue
CommentaryExclusivePredictive AnalyticsRisk Management

Fight Back Against Black Swan Fatigue

5 Min Read
Big Data for SMEs
AnalyticsBig DataBusiness IntelligenceData Management

Big Data for SMEs

9 Min Read
iBeacons, Retail and Information Overload: How Macy's Is Kickstarting Retail's Data Warehousing Needs
Big DataBusiness IntelligenceData ManagementData VisualizationData WarehousingMarketing

iBeacons, Retail and Information Overload: How Macy’s Is Kickstarting Retail’s Data Warehousing Needs

7 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

Artificial Intelligence for eCommerce: A Closer Look
Artificial Intelligence
The Art of Conversation: Enhancing Chatbots with Advanced AI Prompts
Chatbots

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?