We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Why normalization matters with K-Means
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Big Data > Data Mining > Why normalization matters with K-Means
Data MiningPredictive Analytics

Why normalization matters with K-Means

DeanAbbott
DeanAbbott
4 Min Read
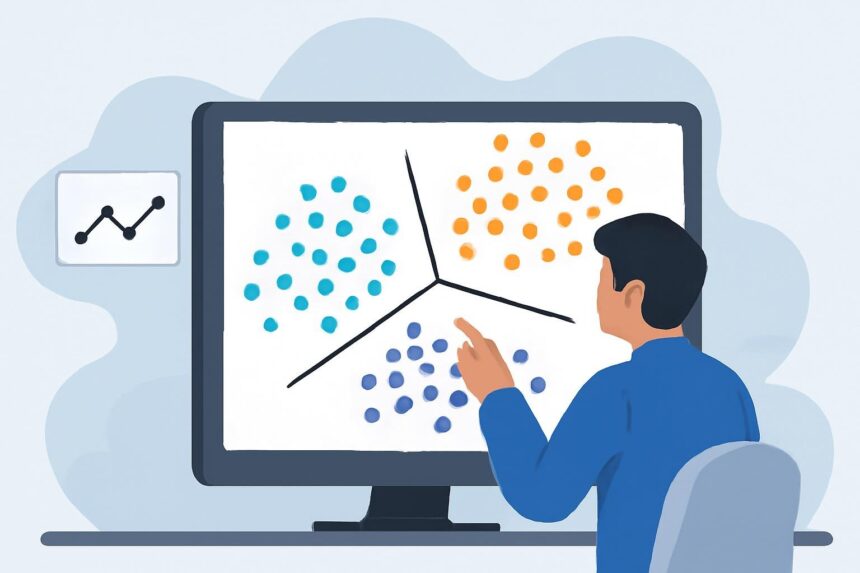
Why normalization matters with K-Means
Illustrative image generated with OpenAI gpt-image-1.
SHARE

A question about K-means clustering in Clementine was posted here. I thought I knew the answer, but took the opportunity to prove it to myself.

I took the KDD-Cup 98 data and just looked at four fields: Age, NumChild, TARGET_D (the amount the recaptured lapsed donors gave) and LASTGIFT. I took only four to make the problem simpler, and chose variables that had relatively large differences in mean values (where normalization might matter). Also, another problem with the two monetary variables is that they are both skewed positively (severely so).

The following image shows the results of two clustering runs: the first with raw data, the second with normalized data using the Clementine K-Means algorithm. The normalization consisted of log transforms (for TARGET_D and LASTGIFT) and z-scores for all (the log transformed fields, AGE and NUMCHILD). I used the default of 5 clusters.

Here are the results in tabular form. Note that I’m reporting unnormalized values for the “normalized” clusters even though the actual clusters were formed by the normalized values. This is purely for comparative purposes.

More Read

Online to Offline Conversions
Real-Time Analytics and Storm Tracking: How Utilities Can Keep Customers Out of the Dark
Apache Spark Use Cases
First Look – Incanto
Data Scientist: Sexiest Job on the Planet

Note that:
1) the results are different, as measure by counts in each cluster
2) the unnormalized clusters are dominated by TARGET_D and LASTGIFT–one cluster contains the large values and the remaining have little variance.
3) AGE and NUMCHILD have some similar breakouts (40s with more children and 40s with fewer children for example).

So, the conclusion is (to answer the original question) K-Means in Clementine does not normalize the data. Since Euclidean distance is used, the clusters will be influenced strongly by the magnitudes of the variables, especially by outliers. Normalizing removes this bias. However, whether or not one desires this removal of bias depends on what one wants to find: sometimes if one would want a variable to influence the clusters more, one could manipulate the clusters precisely in this way, by increasing the relative magnitude of these fields.

One last issue that I didn’t explore here, is the effects of correlated variables (LASTGIFT and TARGET_D to some degree here). It seems to me that correlated variables will artificially bias the clusters toward natural groupings of those variables, though I have never proved the extent of this bias in a controlled way (maybe someone can point to a paper that shows this clearly).
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is workload-by-workload decision-making for cloud migration, where s
Which Workloads Should Move to the Cloud?
Cloud Computing Exclusive IT
Flat editorial illustration: The article positions data governance as a strategic board-level concern rather than a purely techni
Why Data Governance Is Becoming a Board-Level Business Priority
Big Data Exclusive Policy and Governance
Flat editorial illustration: The article argues that data annotation quality should be measured by inspectable gold sets, written
The Top Data Annotation Companies Are Separated by Proof of Quality, Not Headcount
Big Data Exclusive
Flat editorial illustration: The article's core relationship is the gap between raw bank-feed records and reliable subscription i
Subscription Trackers Have a Transaction Data Problem
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Big DataBusiness IntelligenceCollaborative DataCRMModelingPredictive AnalyticsSocial Data

How Big Data Is Driving Airline Loyalty Programs

8 Min Read
Analytics Moves To The Core: Reporting from the Gartner Summit
AnalyticsBusiness IntelligenceData WarehousingPredictive Analytics

Analytics Moves To The Core: Reporting from the Gartner Summit

5 Min Read
A Look into Big Data Applications for Law Enforcement
Predictive Analytics

A Look into Big Data Applications for Law Enforcement

6 Min Read
Predictive Analytics: 8 Things to Keep in Mind (Part 3)
Business IntelligenceData MiningPredictive Analytics

Predictive Analytics: 8 Things to Keep in Mind (Part 3)

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive
Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?