We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    Flat editorial illustration: The article is about joining public web signals with internal business metrics so BI teams can inter
    Alternative Data in BI: Bringing Public Web Data Into Your Dashboards
    23 Min Read
    Flat editorial illustration: The article is about automating the collection, preparation, and delivery of marketing data across p
    From Data to Dashboards: 5 Marketing Reporting Automation Software Picks
    12 Min Read
    Flat editorial illustration: The article contrasts passive follower totals with a behavioral path from attention and trust to cli
    Creator Analytics Beyond Follower Count: Seven Metrics That Measure Audience Behavior
    11 Min Read
    Flat editorial illustration: The article connects AI and marketing analytics with managerial judgment grounded in consumer behavi
    How an Online MBA in Marketing Connects AI and Data Analytics
    11 Min Read
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Preparing Yourself to Move to Apache Spark
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Software > Hadoop > Preparing Yourself to Move to Apache Spark
Big DataData ManagementHadoopMapReduceUnstructured Data

Preparing Yourself to Move to Apache Spark

kingmesal
kingmesal
6 Min Read
Preparing Yourself to Move to Apache Spark
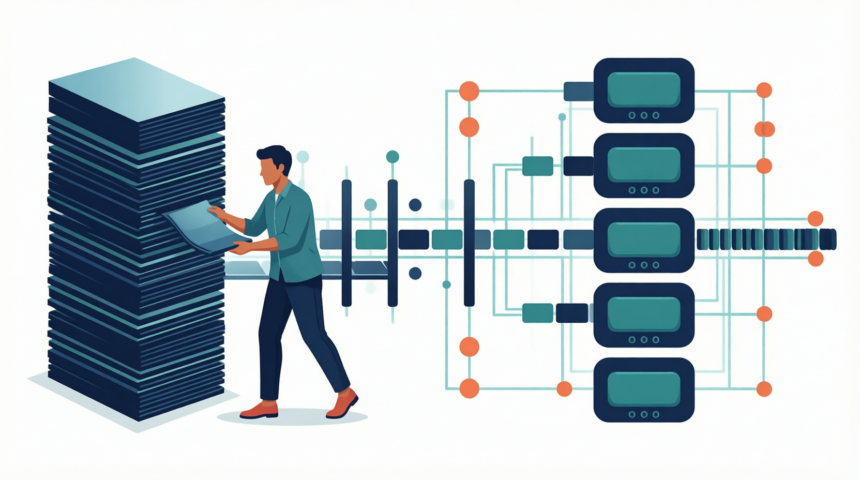
Illustration generated with Qwen Image.
SHARE

IT is an industry that’s always moving. While some things will never go out of style, like the Unix development model and knowing how to design algorithms properly, often you have to throw out what seems like a perfectly good tool or development style in search of something new.

Contents
  • Map and Reduce
  • Partitioning
  • Counters
  • Serialization
  • Conclusion

While MapReduce has been the mainstay of Hadoop processing, Apache Spark is now taking the throne as the way to handle distributed computation. The reasons are obvious: Spark is very fast due to its use of Resilient Distributed Datasets, or RDDs, and it has a clean programming model.

If you’ve been using the older MapReduce framework, you might wonder how much you need to learn before you can jump in and start using Spark. Fortunately, it’s easy to convert what you already know from MapReduce to Spark.

Map and Reduce

The biggest difference from MapReduce is how the Map and Reduce options are implemented.
More Read

5 Big Data eCommerce Tricks To Maximize Your Sales
Pssst … How Much Money For Your Personal Data?
Big Data Challenges Of Industry 4.0 Worth Considering
Has Your Data Quality Been Naughty or Nice?
SAS , R and NYT – The Sequel

To understand this, you need to know how RDDs, Spark’s main data structure, work. RDDs allow for two kinds of operations on data: transformations and actions.

Transformationsare operations that change or filter operations in some way. Transformations are done nondestructively, keeping track of the original data. In a cluster, these changes can be spread out across different nodes. The master node keeps track of these different versions (called lineages) and can rebuild them on another node if one fails. It’s like having a giant RAID. An actionreturns some kind of result.

Given Hadoop’s history, one of the biggest transformations is map(), while reduce() is an action. As with their MapReduce counterparts, map() applies a function to a list, while reduce() aggregates data into a result. The big difference from MapReduce is that these operations are methods exposed by the RDDs themselves.

The programming model is much clearer under Spark than it is under MapReduce. MapReduce is written in Java, which, while not a bad programming language on its own, can be pretty bureaucratic in the way it makes you declare variables. Spark is written in Scala, a much cleaner functional language similar to Lisp or Haskell. 

A program to count lines might take about ten lines or so to write—but you can do it in a few lines of code in Spark with an example borrowed from the Apache Spark Cheat Sheet:

val word1=fm.map(word=>(word,1))
val wrdCnt=word1.reduceByKey(_+_)

What this does is create a variable with the word count in it. We’ve defined the word count by creating key-value pairs with all of the lines, with a value of one in the first line. The second line uses reduceByKey to add all of the keys together. The “_+_” is a placeholder variable meant to add all of the values by key. It’s worth remembering that in Spark, RDDs operate on strings rather than key/value pairs.

We could have squeezed all of this into one line:

val wrdCnt=lines.map(line => (line.length, 1)).reduceByKey(_ + _)

This shows that Spark operations can easily be chained together.

Partitioning

Even though Spark on its own is very fast, you’ll want to make sure that all of the jobs are partitioned well across all your nodes. RDDs can be repartitioned in a customer manner, including by key, or value or even hashing the values.

Counters

You can use counters to count items, such as the line example we showed you earlier. While this can be done using MapReduce, Spark exposes something called accumulators, which are much more powerful. In addition to integers, you can also count using floating point.

Serialization

Spark and MapReduce can translate parallel operations back into serial data structures. In both systems, it’s possible to customize how this happens. In Spark, you have a choice of systems, from the default Java implementation to the Kryo version. All you really have to do is set a variable in the Hadoop configuration file.

Conclusion

If this article has whetted your appetite, you might want to try exploring the Spark documentation resources that are available. When you’re ready for a more advanced playground, this is a great resource to get you started with Spark in your own Sandbox.


TAGGED:big data analytics
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article is about joining public web signals with internal business metrics so BI teams can inter
Alternative Data in BI: Bringing Public Web Data Into Your Dashboards
Big Data Business Intelligence Exclusive Web Analytics
Flat editorial illustration: A SaaS-editorial scene showing product usage, support patterns, and renewal feedback informing a fle
Using Product Usage Analytics and Support Data to Build a B2B Product Roadmap
Business Intelligence Infographic
From Hiring To Payroll: Managing HR Data Across Business Systems -- AI-generated illustration
From Hiring To Payroll: Managing HR Data Across Business Systems
Big Data Business Intelligence Infographic
Flat editorial illustration: The article is about automating the collection, preparation, and delivery of marketing data across p
From Data to Dashboards: 5 Marketing Reporting Automation Software Picks
Analytics Business Intelligence Exclusive Marketing

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Splunk: Bringing Big Data Analysis to the Rest of Us
Data QualityData VisualizationHadoop

Splunk: Bringing Big Data Analysis to the Rest of Us

5 Min Read
Using Building Analytics to Mitigate the Costs of Construction Mistakes
Analytics

Using Building Analytics to Mitigate the Costs of Construction Mistakes

8 Min Read
Hadoop pushes, pulls Big Data analytics into mainstream (Part Two)
AnalyticsBusiness IntelligenceCommentaryData VisualizationData WarehousingDecision ManagementHadoopKnowledge Management

Hadoop pushes, pulls Big Data analytics into mainstream (Part Two)

8 Min Read
Report from the 2012 Hadoop Summit
AnalyticsHadoop

Report from the 2012 Hadoop Summit

21 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive
From Bolts to Bots: How AI Is Fortifying the Automotive Industry
Artificial Intelligence

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?