We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Key Words Through Graph Entropy Hierarchical Clustering
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Analytics > Text Analytics > Key Words Through Graph Entropy Hierarchical Clustering
Text Analytics

Key Words Through Graph Entropy Hierarchical Clustering

cristian mesiano
cristian mesiano
4 Min Read
Key Words Through Graph Entropy Hierarchical Clustering
Illustration generated with FLUX.2 [klein 4B] via Cloudflare Workers AI.
SHARE

In the last post I showed how to extract key words from a text through a principle called graph entropy.
Today I’m going to show another application of the graph entropy in order to extract clusters of key words.
Why
The key words of a document depict the main topic of the content, but if the document is big, often, there are many different sub topics related to the main.

In this perspective, a clusters of keywords should make easier for the reader the identification of the key points of a document.

In the last post I showed how to extract key words from a text through a principle called graph entropy.
Today I’m going to show another application of the graph entropy in order to extract clusters of key words.

More Read

Is Big Data for Market Research?
Does It Take a Scientist to Find Gold in Big Data?
Hands-On Text Analytics Workshop, TAW NYC – Early Bird Pricing Ends Soon
Technologies and Analyses in CBS’ Person of Interest
5 Common Use Cases for Hadoop in Retail

Why
The key words of a document depict the main topic of the content, but if the document is big, often, there are many different sub topics related to the main.

In this perspective, a clusters of keywords should make easier for the reader the identification of the key points of a document.

Moreover, imagine to implement a search engine based on clusters of relevant words instead of the common indexing of atomic words: it enables documents comparison, taxonomies definition, and much more!

How
The definition of graph entropy I’m studying on, assigns to each word of the document a relevance score and a sub graph of words topologically closed to it.

The clustering should maximize the relevance score obtained merging two words in the same cluster.

It’s easy to understand that we have to face a combinatoric maximization problem.

The idea is to take advantage of the Simulated annealing (a bit revisited and adapted to the scope) in order to identify sub-optimal merging solution at each step of the merging phase of the hierarchical clustering.

Experiment
I decided to adopt as document test the complete version of the file we used in the last post: Nuclear_weapon.
Here you are the clusters of first 100 relevant words extracted:

The three clusters obtained.
 

It’s interesting to highlight the following considerations:

  • The first cluster merged together words as “material,uranium, plutonium, isotope” and “war, attack, arm“, and also “proliferation, movement, control, development“.
  • The second cluster (which has the lowest rank) aggregates words as “japan, japanese, place, israel, iraq,american“, and “ton, tnt, yeld”  
  • The third cluster (which has the highest rank) describes quite well the primary topic, merging all the most important words of the document! 

Of course, the procedure is still in “incubator” phase, and the accuracy of the clusters rests on the performance of the Annealing clustering (…maybe different algorithms in this context perform better… but just to show a rough solution I guess it’s enough :D)

This is the optimization process for the last merging stage (I presume that temperature schedule requires an adjustment):

Optimization curve through Simulated Annealing Hierarchical Clustering (last merging stage)


Next steps:
Looking forward to receive comments, and suggestions.
…It would be interesting using such methodology to create a new kind of full text search engine, totally independent by frequency of the words and frequency of visits.

The doc
here you are the document parsed and colored through the clustering assignment (have been highlighted just the first 100 relevant features ranked through the Graph Entropy method).
Stay tuned
cristian.

Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

How Restaurant POS and Ordering Data Reveal Generational Customer Patterns -- AI-generated illustration
How Restaurant POS and Ordering Data Reveal Generational Customer Patterns
Exclusive Infographic
From Trucks To Data: How Telematics Can Improve Freight Transportation -- AI-generated illustration
From Trucks To Data: How Telematics Can Improve Freight Transportation
Big Data Exclusive Infographic
The Airflow Problems Hiding Inside Data Centers -- AI-generated illustration
The Airflow Problems Hiding Inside Data Centers
Big Data Exclusive Infographic
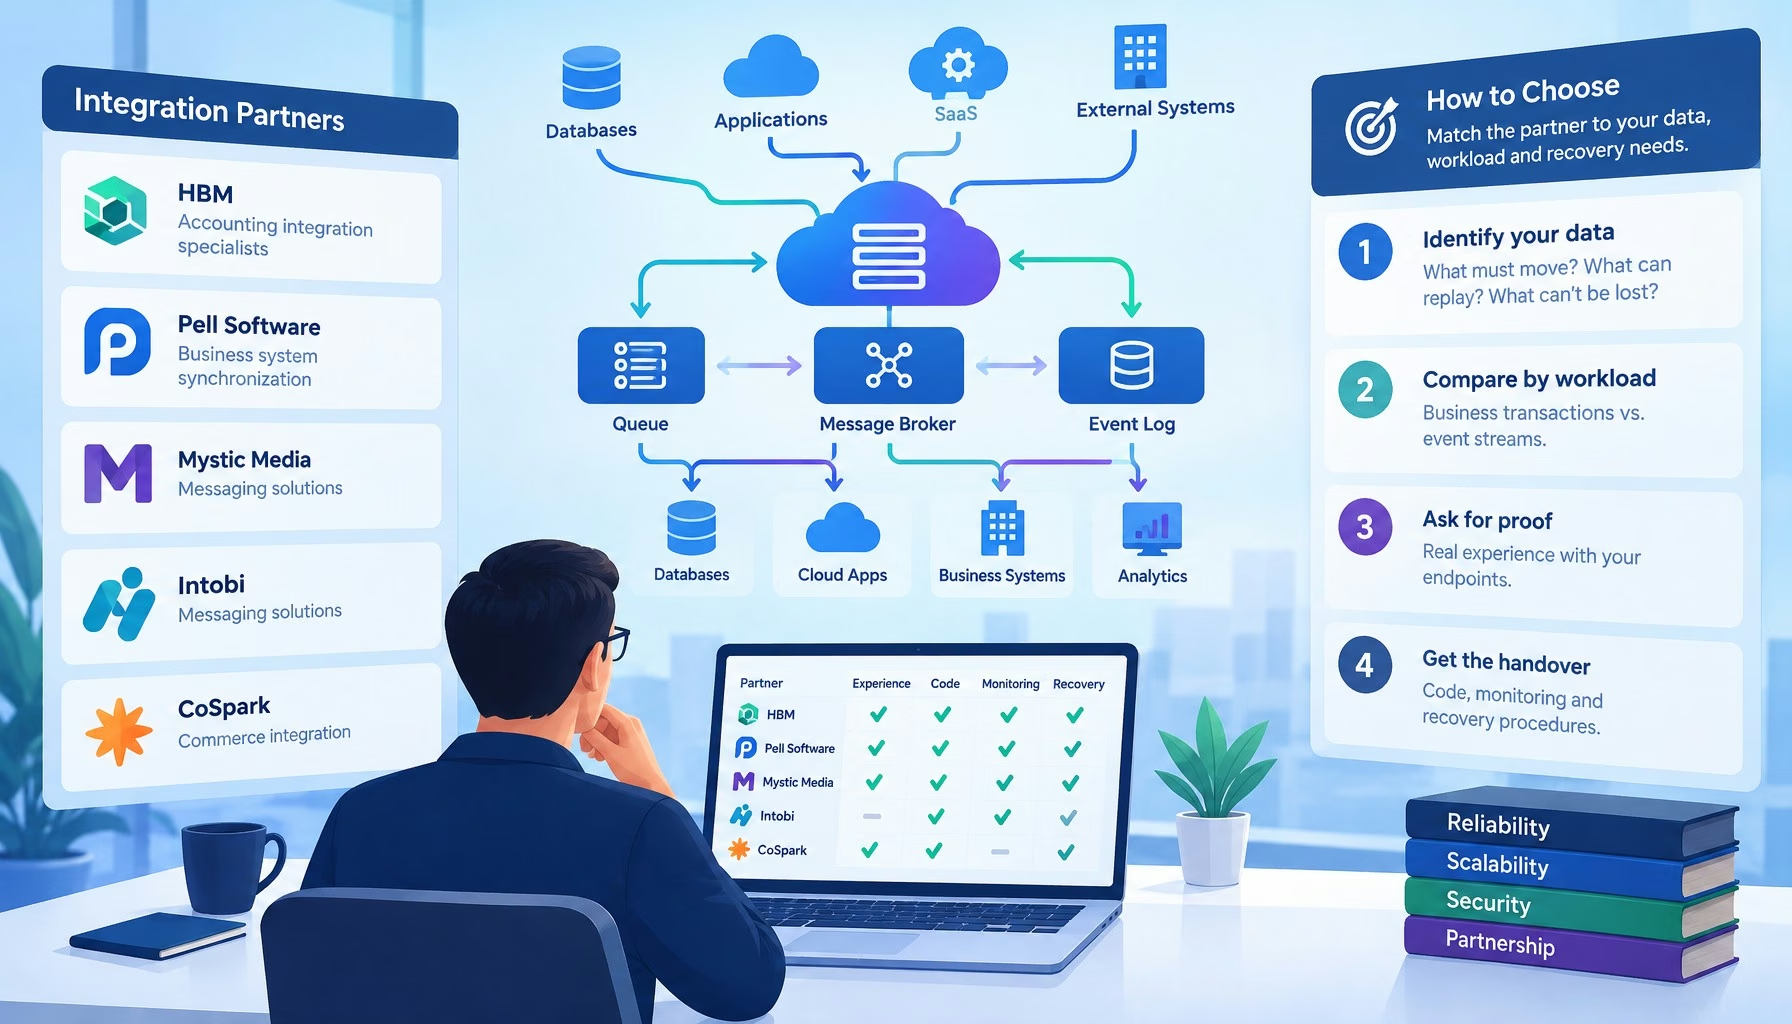
Technical architecture diagram and decision framework for choosing an integration partner for data pipelines: service bus, brokers, and azure-native middleware compared
Choosing an Integration Partner for Data Pipelines: Service Bus, Brokers, and Azure-Native Middleware Compared
Development Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Is Facebook Taking Big Data Analytics Too Far?
AnalyticsBig DataBusiness IntelligenceData ManagementData MiningModelingPolicy and GovernancePredictive AnalyticsPrivacySocial DataText AnalyticsTransparencyWeb Analytics

Is Facebook Taking Big Data Analytics Too Far?

6 Min Read
Measuring the Strong Signal of the Customer’s Voice
AnalyticsBest PracticesBusiness IntelligenceMarket ResearchPredictive AnalyticsText AnalyticsWeb Analytics

Measuring the Strong Signal of the Customer’s Voice

17 Min Read
Factual's Crosswalk API
Text Analytics

Factual’s Crosswalk API

4 Min Read
Text Mining and Pronouns
Text Analytics

Text Mining and Pronouns

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

Artificial Intelligence for eCommerce: A Closer Look
Artificial Intelligence
How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?