We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: A Closer Look at RDDs
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Big Data > Data Warehousing > A Closer Look at RDDs
Data Warehousing

A Closer Look at RDDs

kingmesal
kingmesal
6 Min Read
A Closer Look at RDDs
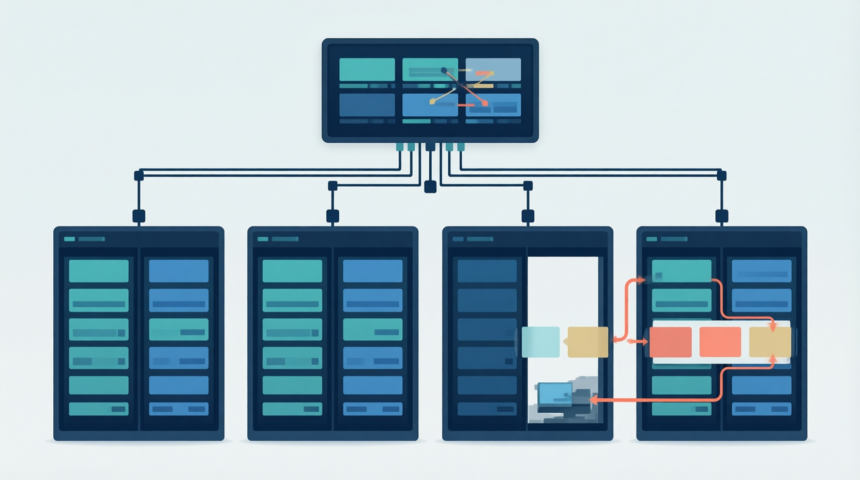
Illustration generated with Qwen Image.
SHARE

Apache Spark has gotten a lot of attention for its fast processing of large amounts of data. But how does it get up to speed? The biggest reason that Spark is so fast is its use of the Resilient Distributed Dataset, or RDD. 

These RDDs are the heart of Spark—the engine that allows it to process so much data so quickly and reliably.

What Are RDDs?

RDDs are a data structure that’s distinctive of Apache Spark. The “resilient” part comes from the fact that Spark ensures a degree of safety when dealing with data. Operations on RDDs are split into two categories: transformations and actions. (This will be explained later in the article.) Operations on data are made out of chained transformations, which makes it easy to recover from machine loss.
More Read

Delivering Data Warehousing and BI Projects using Agile
B2B CRM: The Right Contact Mix for Your Customer Relationship
3 Reasons Hadoop is Heading to the Cloud
Beware of Big Data Technology Zealotry
What’s an IT Data Warehouse? And Why Do You Need One?

Since MapR made its name as a company supporting Hadoop, it’s not surprising that distributed filesystems are a major focus for Spark. RDDs can be distributed across many nodes, being controlled by a “master” node. If a “slave” machine goes down, the data can be reconstructed from other nodes, like a giant RAID system. Hadoop comes in by providing the reliable, distributed HDFS system to store the data.

RDDs also hold as much data as possible in memory. With powerful nodes, most clusters shouldn’t have any problem.

Lazy Evaluation

You might think that having all of this data in memory might be as slow as molasses, but Spark borrows a technique from functional programming languages like Haskell. RDD operations are lazily evaluated. That means that the operations aren’t actually executed until they’re needed. This lets you specify some complicated operations without suffering the performance hits.

You could work out an algorithm in the interactive Spark shell, do something else, then ask for some output. If you find that it takes a long time, you can put it into a script to be run in batch mode.

This is in contrast to eager evaluation, where everything’s evaluated immediately.

Transformations vs. Actions

Transformations make changes to data, such as sorting, counting, or filtering items that meet certain criteria. These transformations simply return a new RDD from the old one nondestructively. In case of a failure, RDDs can be rebuilt from other transformations, as operations on data are made of chained transformations. Transformations include filtering, mapping, and reducing, as well as operations derived from set theory, such as unions and intersections. 

The Spark documentation shows all of the transformations you can make to your data. You can build all kinds of complex transformations to explore your data out of these simple building blocks.

Actions are operations that produce some kind of output. Actions include counting elements in an RDD, flattening them into arrays, and retrieving the first N items from an RDD. You can also save RDDs in a text file for exporting.

Lineage

A lot of the resiliency in RDDs comes from lineages. As mentioned earlier, transformations are nondestructive, preserving the earlier RDD. Spark relies on lineages, which are records of all the previous versions of RDDs. Since all transformations are made out of other transformations, if a node fails, the master can reconstruct the data out of the lineage on other nodes.

Of course, that assumes that nothing bad has happened to driver application and whether it is running in client or cluster mode. In any case, the lineage feature is very powerful and allows a great degree of safety, but you should focus on good practices such as keeping up-to-date backups and having an off-site backup plan for data that really matters. If you can afford it, you might want to build clusters in another area for continuity. These days, it’s also easy to use cloud providers to have clusters in different places without having to wire up servers yourself.

Conclusion

The heart of a good program is, as any really talented programmer will tell you, the data structures, rather than the algorithm. RDDs provide a good data structure for Big Data because of their reliability combined with their simplicity. With Spark and RDDs, the only limit will be your imagination, especially when backed by the support of MapR’s Spark distribution.

Take a deeper dive into Spark with the free interactive eBook: Getting Started with Spark: From Inception to Production, by James A. Scott.

Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
Analytics Big Data Exclusive Software
Flat editorial illustration: The article examines AI agents that escalate from legitimate data retrieval to attempted intrusions
OpenAI’s Government Website Incidents Raise a Hard Question for AI Agents: When Should They Stop?
Artificial Intelligence News Security
Flat editorial illustration: The article's core relationship is the alignment between customer behavioral data (visit frequency,
Data-Driven Loyalty: How Restaurants Use Behavioral Analytics to Optimize Revenue
Exclusive
Flat editorial illustration: The article's core relationship is that reliable eCommerce attribution depends on a unified, well-st
How eCommerce Data Teams Can Build Attribution That Holds Up
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

The Datafication of People and Stuff and Things
Big DataBusiness IntelligenceData MiningData WarehousingHadoopSocial DataUnstructured DataWorkforce Data

The Datafication of People and Stuff and Things

5 Min Read
Is Big Data at Risk of Unleashing Big Brother?
AnalyticsData MiningData WarehousingPolicy and GovernancePrivacy

Is Big Data at Risk of Unleashing Big Brother?

7 Min Read
Hadoop in Advertising & Media: Is Data Analytics Making Old Media New?
AnalyticsBig DataCloud ComputingData MiningData VisualizationData WarehousingHadoopHardwareITMapReduceMarketingMarketing AutomationOpen SourcePredictive AnalyticsSentiment AnalyticsSocial DataSocial Media AnalyticsSoftwareSQLUnstructured DataWeb AnalyticsWorkforce AnalyticsWorkforce Data

Hadoop in Advertising & Media: Is Data Analytics Making Old Media New?

5 Min Read
"Data Science": what's in a name?
CommentaryData MiningData Warehousing

“Data Science”: what’s in a name?

3 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive
Artificial Intelligence for eCommerce: A Closer Look
Artificial Intelligence

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?