We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Budgeting Time on a Modeling Project
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Analytics > Modeling > Budgeting Time on a Modeling Project
Modeling

Budgeting Time on a Modeling Project

DeanAbbott
DeanAbbott
3 Min Read
Budgeting Time on a Modeling Project
Illustration generated with FLUX.2 [Klein 9B] via local ComfyUI.
SHARE

Within the time allotted for any empirical modeling project, the analyst must decide how to allocate time for various aspects of the process.  As is the case with any finite resource, more time spent on this means less time spent on that.  I suspect that many modelers enjoy the actual modeling part of the job most.  It is easy to try “one more” algorithm: Already tried logistic regression and a neural network?  Try CART next.

Within the time allotted for any empirical modeling project, the analyst must decide how to allocate time for various aspects of the process.  As is the case with any finite resource, more time spent on this means less time spent on that.  I suspect that many modelers enjoy the actual modeling part of the job most.  It is easy to try “one more” algorithm: Already tried logistic regression and a neural network?  Try CART next.

Of course, more time spent on the modeling part of this means less time spent on other things.  An important consideration for optimizing model performance, then, is: Which tasks deserve more time, and which less?

Experimenting with modeling algorithms at the end of a project will no doubt produce some improvements, and it is not argued here that such efforts be dropped.  However, work done earlier in the project establishes an upper limit on model performance.  I suggest emphasizing data clean-up (especially missing value imputation) and creative design of new features (ratios of raw features, etc.) as being much more likely to make the model’s job easier and produce better performance.
More Read

In Praise of Industry Models
Why Predictive Analytics is Important and More
Protecting Public Data
Keeping Singapore Green with Data and Design
How Data Visualization Can Benefit SMBs

Consider how difficult it is for a simple 2-input model to discern “healthy” versus “unhealthy” when provided the input variables height and weight alone.  Such a model must establish a dividing line between healthy and unhealthy weights separately for each height.  When the analyst uses instead the ratio of weight to height, this becomes much simpler.  Note that the commonly used BMI (body mass index) is slightly more complicated than this, and would likely perform even better.  Cross categorical variables is another way to simplify the problem for the model.  Though we deal with a process we call “machine learning”, is is a pragmatic matter to make the job as easy as possible for the machine.

The same is true for handling missing values.  Simple global substitution using the non-missing mean or median is a start, but think about the spike that creates in the variable’s distribution.  Doing this over multiple variables creates a number of strange artifacts in the multivariate distribution.  Spending the time and energy to fill in those missing values in a smarter way (possibly by building a small model) cleans up the data dramatically for the downstream modeling process.
— Post by Will Dwinnell
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is workload-by-workload decision-making for cloud migration, where s
Which Workloads Should Move to the Cloud?
Cloud Computing Exclusive IT
Flat editorial illustration: The article positions data governance as a strategic board-level concern rather than a purely techni
Why Data Governance Is Becoming a Board-Level Business Priority
Big Data Exclusive Policy and Governance
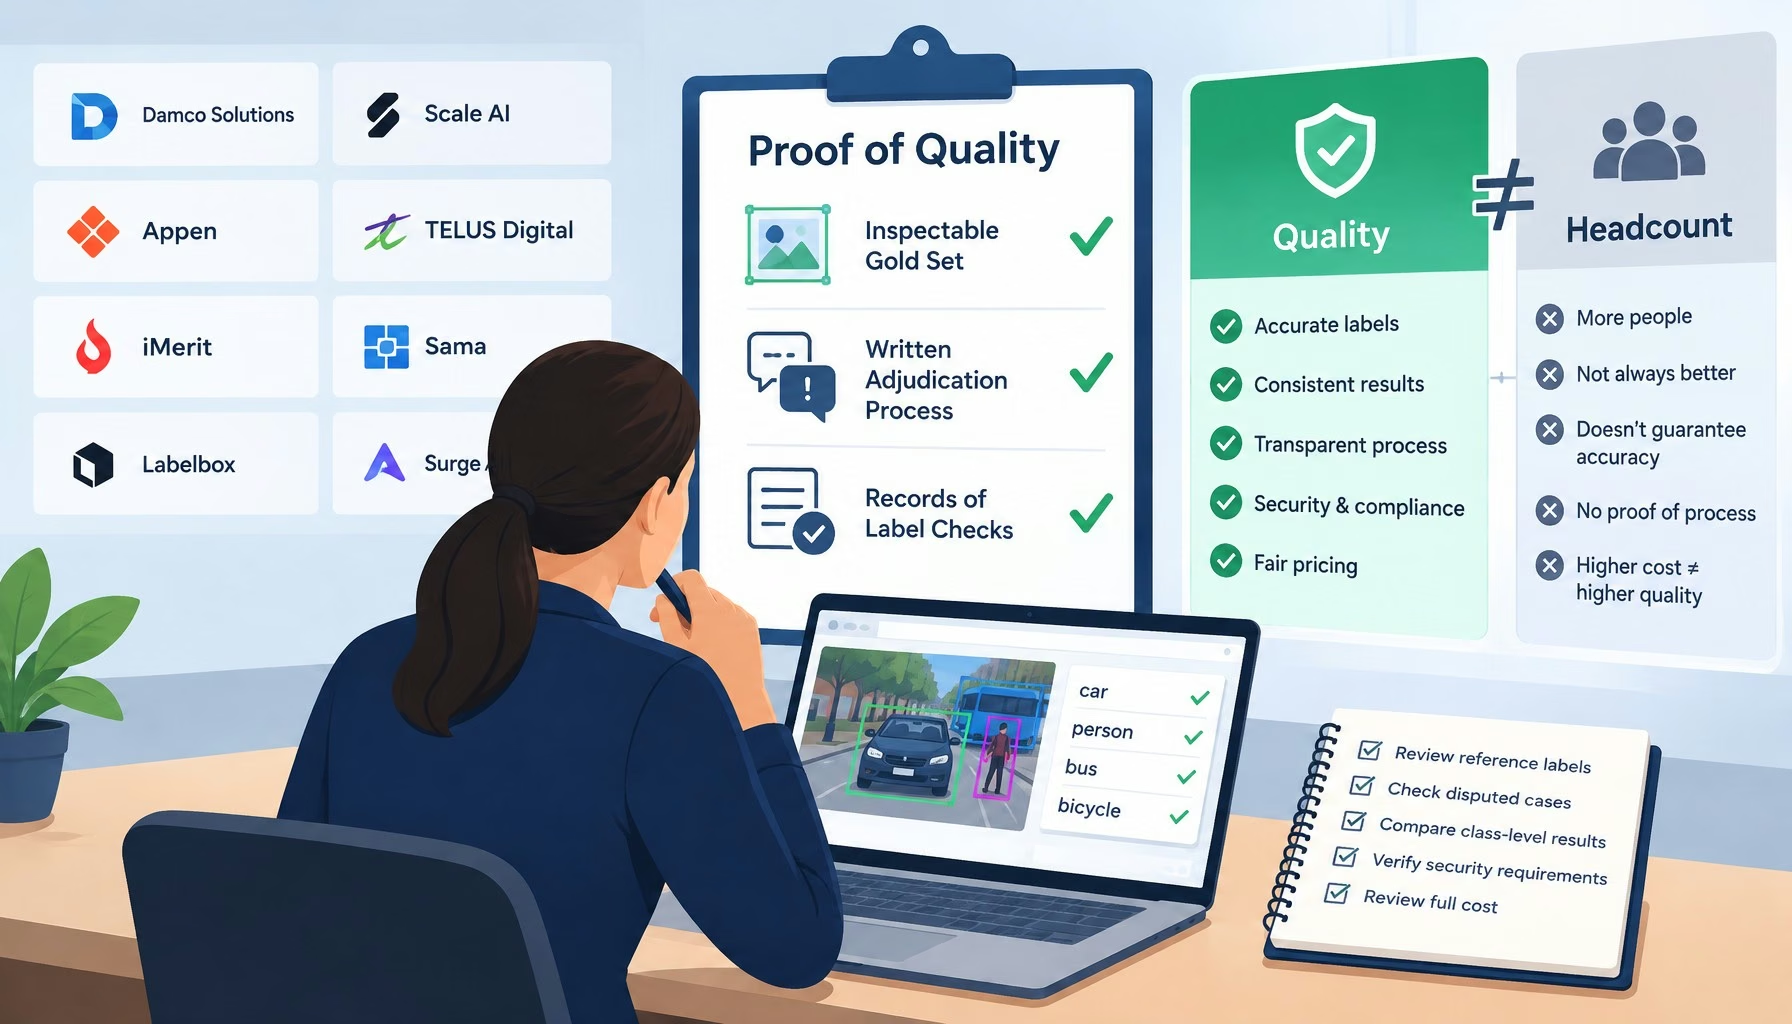
Flat editorial illustration: The article argues that data annotation quality should be measured by inspectable gold sets, written
The Top Data Annotation Companies Are Separated by Proof of Quality, Not Headcount
Big Data Exclusive
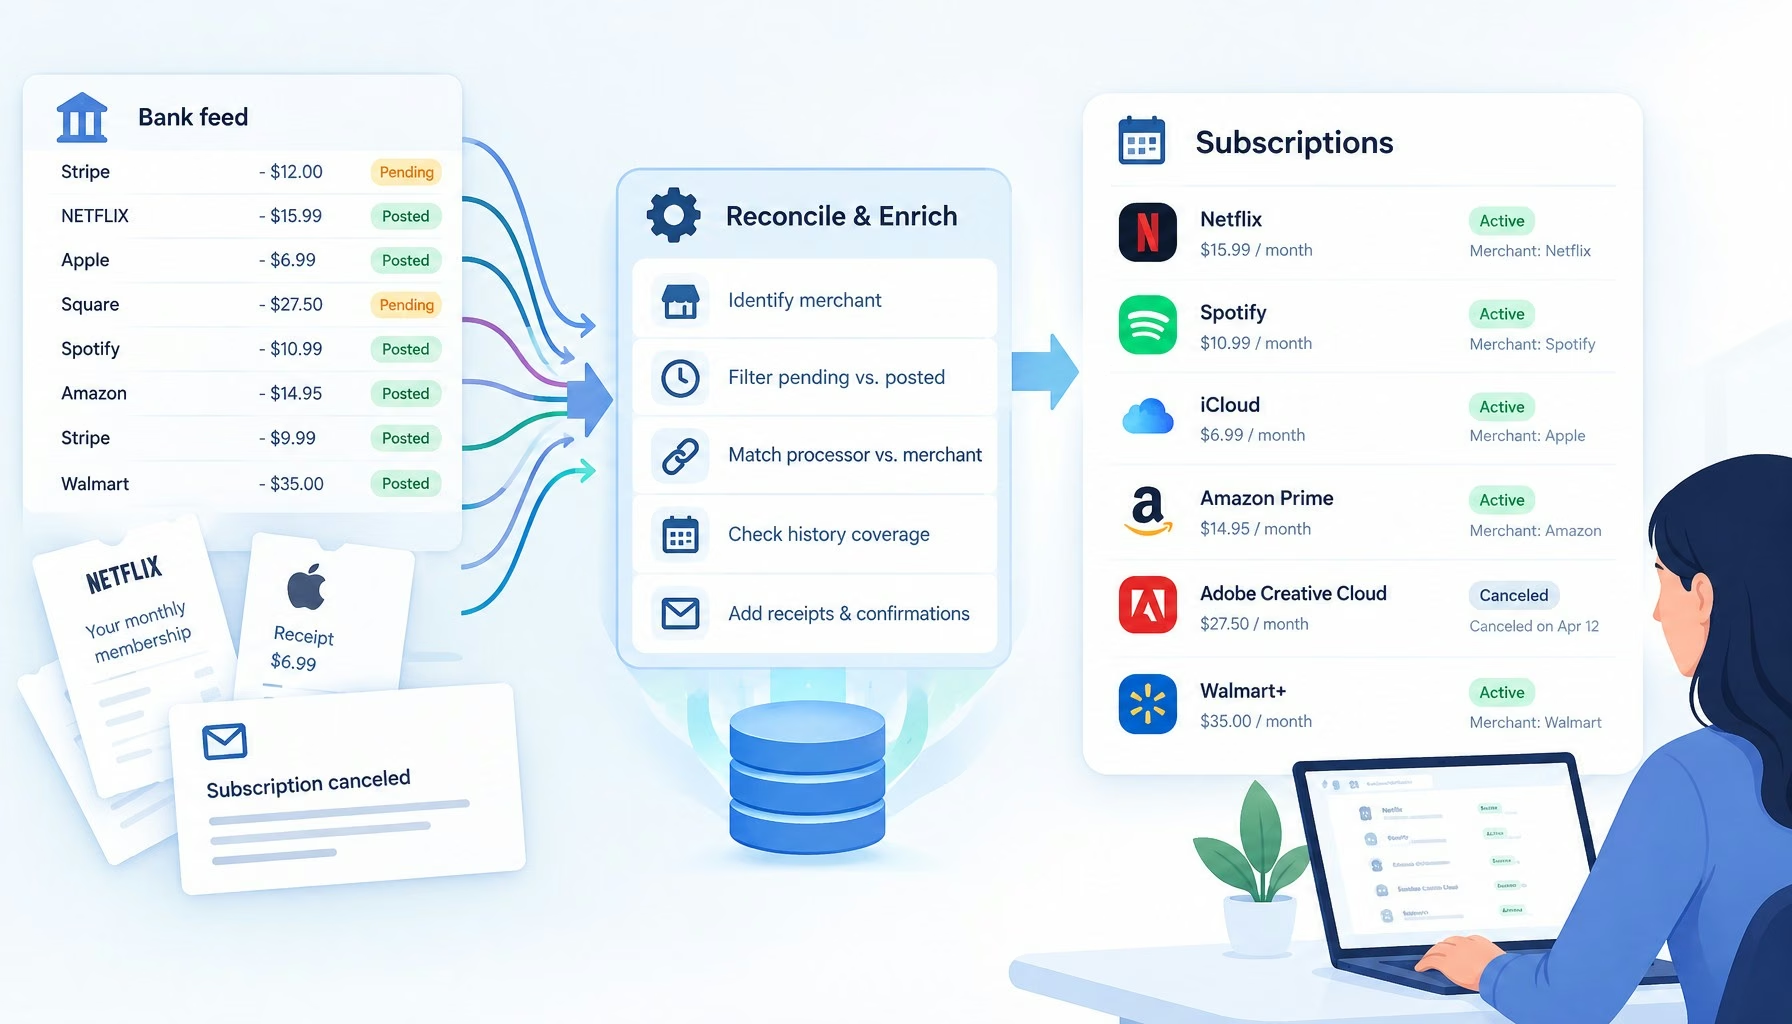
Flat editorial illustration: The article's core relationship is the gap between raw bank-feed records and reliable subscription i
Subscription Trackers Have a Transaction Data Problem
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

New Generation of Technology Will Rely on Analytics, Study Shows
AnalyticsBig DataBusiness IntelligenceData ManagementData QualityITModelingPredictive AnalyticsWeb AnalyticsWorkforce Analytics

New Generation of Technology Will Rely on Analytics, Study Shows

4 Min Read
Harvard Gets Access to Twitter Data Stream to Predict Foodborne Illness Outbreaks
AnalyticsBig DataBusiness IntelligenceData MiningExclusiveModelingPredictive AnalyticsSocial DataText Analytics

Harvard Gets Access to Twitter Data Stream to Predict Foodborne Illness Outbreaks

4 Min Read
When Ideology Reigns Over Data
AnalyticsCollaborative DataCommentaryData QualityExclusiveModelingPolicy and GovernanceStatisticsTransparency

When Ideology Reigns Over Data

6 Min Read
Thanks, Big Data: America's Drinking Habits Predict the Election
AnalyticsBig DataModelingPredictive AnalyticsWeb Analytics

Thanks, Big Data: America’s Drinking Habits Predict the Election

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive
AI chatbots
AI Chatbots Can Help Retailers Convert Live Broadcast Viewers into Sales!
Chatbots

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?