We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: A Guide to Spark Streaming – Code Examples Included
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Big Data > Data Mining > A Guide to Spark Streaming – Code Examples Included
Big DataData MiningHadoopMapReduceUnstructured Data

A Guide to Spark Streaming – Code Examples Included

kingmesal
kingmesal
6 Min Read
A Guide to Spark Streaming - Code Examples Included
Illustration generated with Qwen Image.
SHARE

Apache Spark is great for processing large amounts of data over large clusters, but wouldn’t it be great if you could process data in near real time? You can with Spark Streaming.

Contents
  • What Is Spark Streaming?
  • What kinds of data can you analyze?
  • DStream and RDDs
  • Spark Streaming Transformations
  • Conclusion

What Is Spark Streaming?


Spark Streaming is a special SparkContext that you can use for processing data quickly in near-time. It’s similar to the standard SparkContext, which is geared toward batch operations. Spark Streaming uses a little trick to create small batch windows (micro batches) that offer all of the advantages of Spark: safe, fast data handling and lazy evaluation combined with real-time processing. It’s a combination of both batch and interactive processing.

You can adjust the window for processing latency down to half a second, but this is more memory intensive. Spark Streaming is used for everything ranging from credit card fraud detection to the identification of threats on the Internet.

What kinds of data can you analyze?

You might be wondering what kind of data you can ingest into Apache Spark. The short answer is pretty much everything.
More Read

human resource data
The Integration of Employee Experience with Enterprise Data Tools
The Future of Big Data, Visualized [INFOGRAPHIC]
How Data Became Big
Client Scheduling Data: How Past Behavior Predicts The Future
It’s Time to Ditch Scarcity Thinking

More specifically, you can import data from Twitter, Flume, Kafka, ZeroMQ, a custom feed, and HDFS. You can also export into HDFS, as well as other databases, applications, and dashboards.

DStream and RDDs

How is all this possible? It all comes down to the primary data type of Spark: the RDD, or Resilient Distributed Dataset. An RDD is an abstraction of the data that’s held in memory, which is a lot faster than storing and fetching things from disk. This already gives you a significant speed boost over other systems.

RDDs are also safer to use because the transformations keep the original data in lineages, returning new RDDs with the transformations applied. This allows Spark to reconstruct the data with all the changes should something go wrong with one of the nodes in the cluster, such as a power failure.

DStream takes the concept of RDDs and applies it to streams. A DStream is simply a stream of RDDs, giving all of the advantages of speed and safety in near real time. The DStream API offers a limited set of transformations compared to the standard Apache Spark.

Spark Streaming Transformations

If you’re wondering what kind of transformations you can do on DStreams, they’re pretty similar to the standard Spark transformations.

We’ll borrow some examples from the Apache Spark Reference Card to give you a taste. Let’s pretend we’re reading data over some kind of stream, such as from a social media feed. 

Let’s start our Spark Streaming Context:

val ssc = new StreamingContext(sc, Seconds(1))
val lines = ssc.socketTextStream(“localhost”, 9999)

For example, map(func) takes func as an argument and applies it to each element, returning a new RDD.

Here’s an example multiplying each line by 10:

lines.map(x=>x.toInt*10).print()

We’ll send some data with the Netcat or nc program available on most Unix-like systems. Spark is reading from port 9999, so we’ll have to make sure Netcat points there.

prompt> nc –lk 9999
12
34

Here’s what the output looks like:

120
340

flatmap() is similar, but can return 0 or more items.

This example splits text, putting each word on separate lines:

lines.flatMap(_.split(” “)).print()

Let’s try it with the string “Spark is fun”:

prompt> nc –lk 9999
Spark is fun

And here’s the output:

Spark
is
fun

count() is obvious enough. It counts the number of data elements.

We can count the lines in our stream:

lines.flatMap(_.split(” “)).count()

And here are some lines:

prompt> nc –lk 9999
say
hello
to
spark

The output should be 4.

reduce() is similar, but applies a function as an argument to the data elements instead of just adding them.

We can use this to add up all the numbers:

lines.map(x=>x.toInt).reduce(_+_).print()

And let’s get some numbers into Spark Streaming:

prompt> nc –lk 9999
1
3
5
7

The answer should be 16.

countByValue() counts the number of occurrences of each data set.

We can use this to count the number of times each word occurs:

lines.countByValue().print()

We’ll include some duplicate lines just to show you how it works:

prompt>nc –lk 9999
spark
spark
is
fun
fun

The output will look like this:

(is,1)
(spark,2)
(fun,2)

An alternate way we could do this is by using the reduceByKey() function:

val words = lines.flatMap(_.split(” “))
val wordCounts = words.map(x => (x, 1)).reduceByKey(_+_)
wordCounts.print()

Conclusion

By now, you have seen the power of Spark Streaming and what it can do for your near-real-time big data needs. If you want to experiment, you can download a private Sandbox, a full virtual machine with Apache Spark that you can play around with.
TAGGED:big data
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is workload-by-workload decision-making for cloud migration, where s
Which Workloads Should Move to the Cloud?
Cloud Computing Exclusive IT
Flat editorial illustration: The article positions data governance as a strategic board-level concern rather than a purely techni
Why Data Governance Is Becoming a Board-Level Business Priority
Big Data Exclusive Policy and Governance
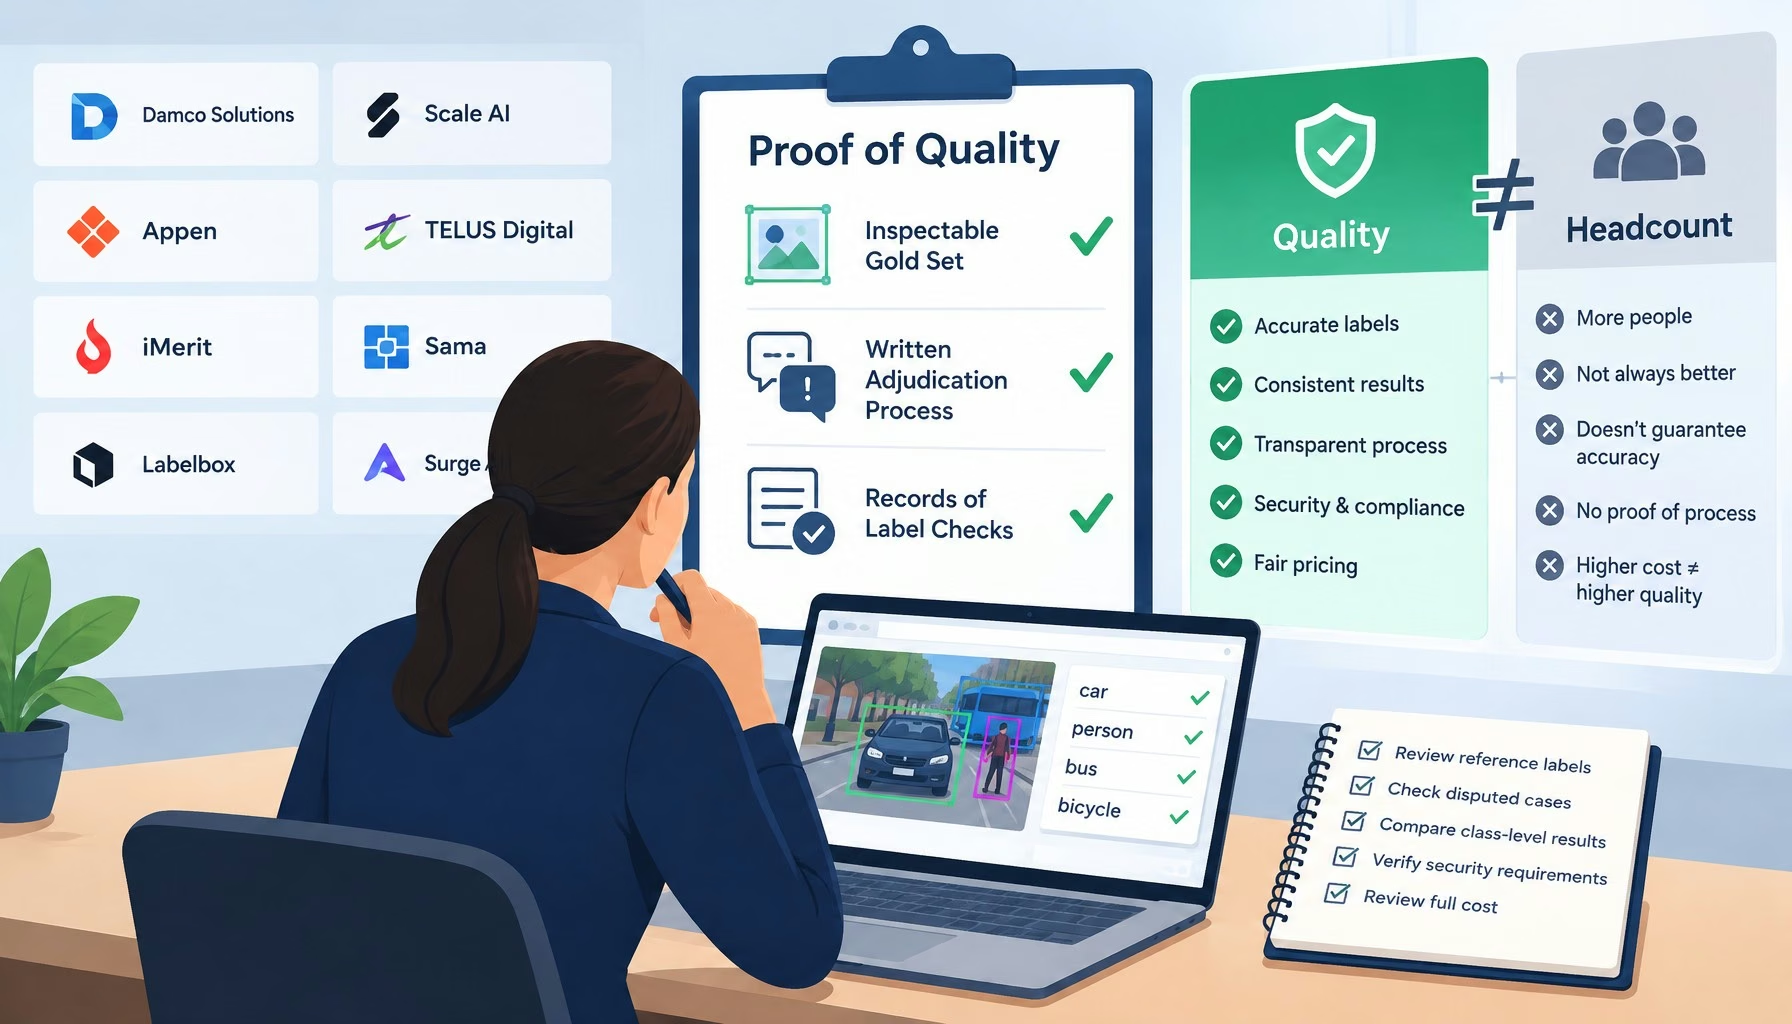
Flat editorial illustration: The article argues that data annotation quality should be measured by inspectable gold sets, written
The Top Data Annotation Companies Are Separated by Proof of Quality, Not Headcount
Big Data Exclusive
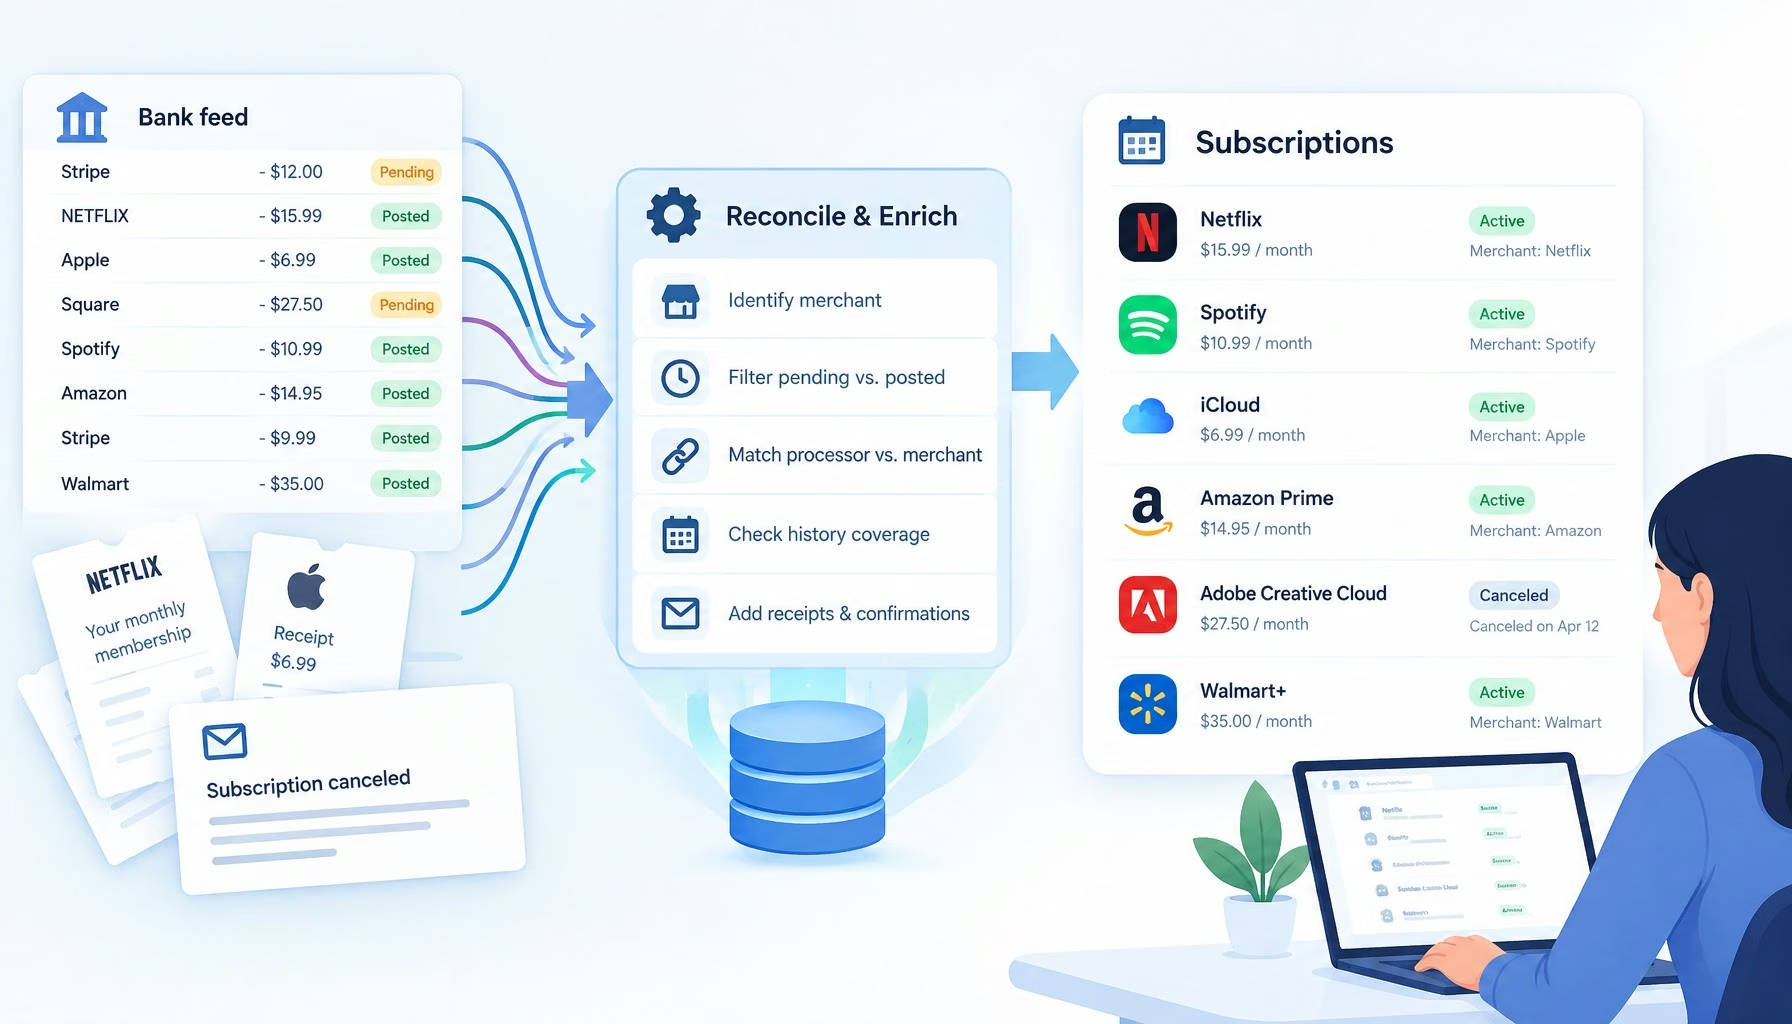
Flat editorial illustration: The article's core relationship is the gap between raw bank-feed records and reliable subscription i
Subscription Trackers Have a Transaction Data Problem
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Big Data is Transforming the Future of WordPress Hosting
Big DataExclusive

Big Data is Transforming the Future of WordPress Hosting

8 Min Read
5 Ways to Improve Organizational Learning with Big Data Analytics
AnalyticsWorkforce Analytics

5 Ways to Improve Organizational Learning with Big Data Analytics

7 Min Read
Socialytics: Social Analytics Earns Its Portmanteau
AnalyticsBusiness IntelligenceData ManagementSocial Media Analytics

Socialytics: Social Analytics Earns Its Portmanteau

3 Min Read
The 5 Most Important Criminal DNA And Crime Data Sources
Big DataExclusive

The 5 Most Important Criminal DNA And Crime Data Sources

9 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

From Bolts to Bots: How AI Is Fortifying the Automotive Industry
Artificial Intelligence
5 Great Tips for Using Data Analytics for Website UX
Big Data

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?