We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: When sharing isn’t a good idea
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Big Data > Data Mining > When sharing isn’t a good idea
Data Mining

When sharing isn’t a good idea

TimManns
TimManns
6 Min Read
When sharing isn't a good idea
Illustration generated with FLUX.1 [schnell] via Cloudflare Workers AI.
SHARE

Ensemble models seem to be all the buzz at the moment. The NetFlix prize was won by a conglomerate of various models and approaches that each excelled in subsets of the data.

A number of data miners have presented findings based upon using simple ensembles that use the mean prediction of a number of models. I was surprised that some form of weighting isn’t commonly used, and that a simple mean average of multiple models could yield such an improvement in the global predictive power. It kinda reminds me of Gestalt theory phrase “The whole is greater than the sum of the parts.” It’s got me thinking, when it is best not to share predictive power. What if one model is the best? There is also a ton of considerations regarding scalability and trade-off between additional processing, added business value, and practicality (don’t mention random forests to me…), but we’re pretend those don’t exist for the purpose of this discussion 🙂

So this has got me thinking do ensembles work best in situations where there are clearly different sub-populations of customers. For example, Netflix is in the retail space, with many customers that rent the same popular blockbuster movies, and a moderate number of customers that rent rarer (or far more diverse, i.e., long tail) movies. I haven’t looked at the Netflix data, so I’m guessing that most customers don’t have hundreds of transactions, so generalising the correct behaviour of the masses to specific customers is important. Netflix data on any specific customer could be quite scant (in terms of rents/transactions). In other industries such as telecom, there are parallels; customers can also be differentiated by nature of communication (voice calls, sms calls, data consumption etc) just like types of movies. Telecom is mostly about quantity though (customer x used to make a lot of calls etc). More importantly there is a huge amount of data about each customer, often with many hundreds of transactions per customer. There is therefore relatively lesser reliance upon supporting behaviour of the masses (although it helps a lot) to understand any specific customer.

Following this logic, I’m thinking that ensembles are great at reducing the error of incorrectly applying insights derived from the generalised masses to those weirdos that rent obscure sci-fi movies! Combining models that explain sub-populations very well makes sense, but what if you don’t have many sub-populations (or can identify and model their behaviour with one model).
More Read

Alberto’s Business Analytics Predictions for 2012
The Data Discovery: Investing in Customer Insight
Comparing the Cost Continued…
Interview – David Smith REvolution Computing
Mobile Advertising, Clustering Algorithms, and Your Ticket for a Free Ride

But you may shout “hey, what about the KDD Cup.” Yes, the recent KDD Cup challenge (anonymous featureless telecom data from Orange) was also a won by an ensemble of over a thousand models created by IBM Research. I’d like to have had some information about what the hundreds of columns respresented, and this might have helped better understand the Orange data and build more insightful and performing models. Aren’t ensemble models used in this way simply a brute force approach to over learn the data? I’d also really like to know how the performance of the winning entry tracks over the subsequent months for Orange.

Well, I haven’t had a lot of success in using ensemble models in the telecom data I work with, and I’m hoping it is more a reflection of the data than any ineptitude on my part. I’ve tried simply building multiple models on the entire dataset and averaging the scores, but this doesn’t generate much additional improvement (granted on already good models, and I already combine K-means and Neural Nets on the whole base). During my free time I’m just starting to try splitting the entire customer base into dozens of small sub-populations and building a Neural Net model on each, then combining the results and seeing if that yields an improvement. It’ll take a while.

Thoughts?
Link to original post

Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Retailers Should Stop Treating Every Stockout as Equal -- AI-generated illustration
Retailers Should Stop Treating Every Stockout as Equal
Business Intelligence Exclusive
Best Vibe Coding Cleanup Specialists in the USA: Fix or Rebuild? -- AI-generated illustration
Best Vibe Coding Cleanup Specialists in the USA: Fix or Rebuild?
Development Exclusive
Using Warehouse, Transportation and Order Data to Plan Distribution-Center Capacity -- AI-generated illustration
Using Warehouse, Transportation and Order Data to Plan Distribution-Center Capacity
Big Data Exclusive
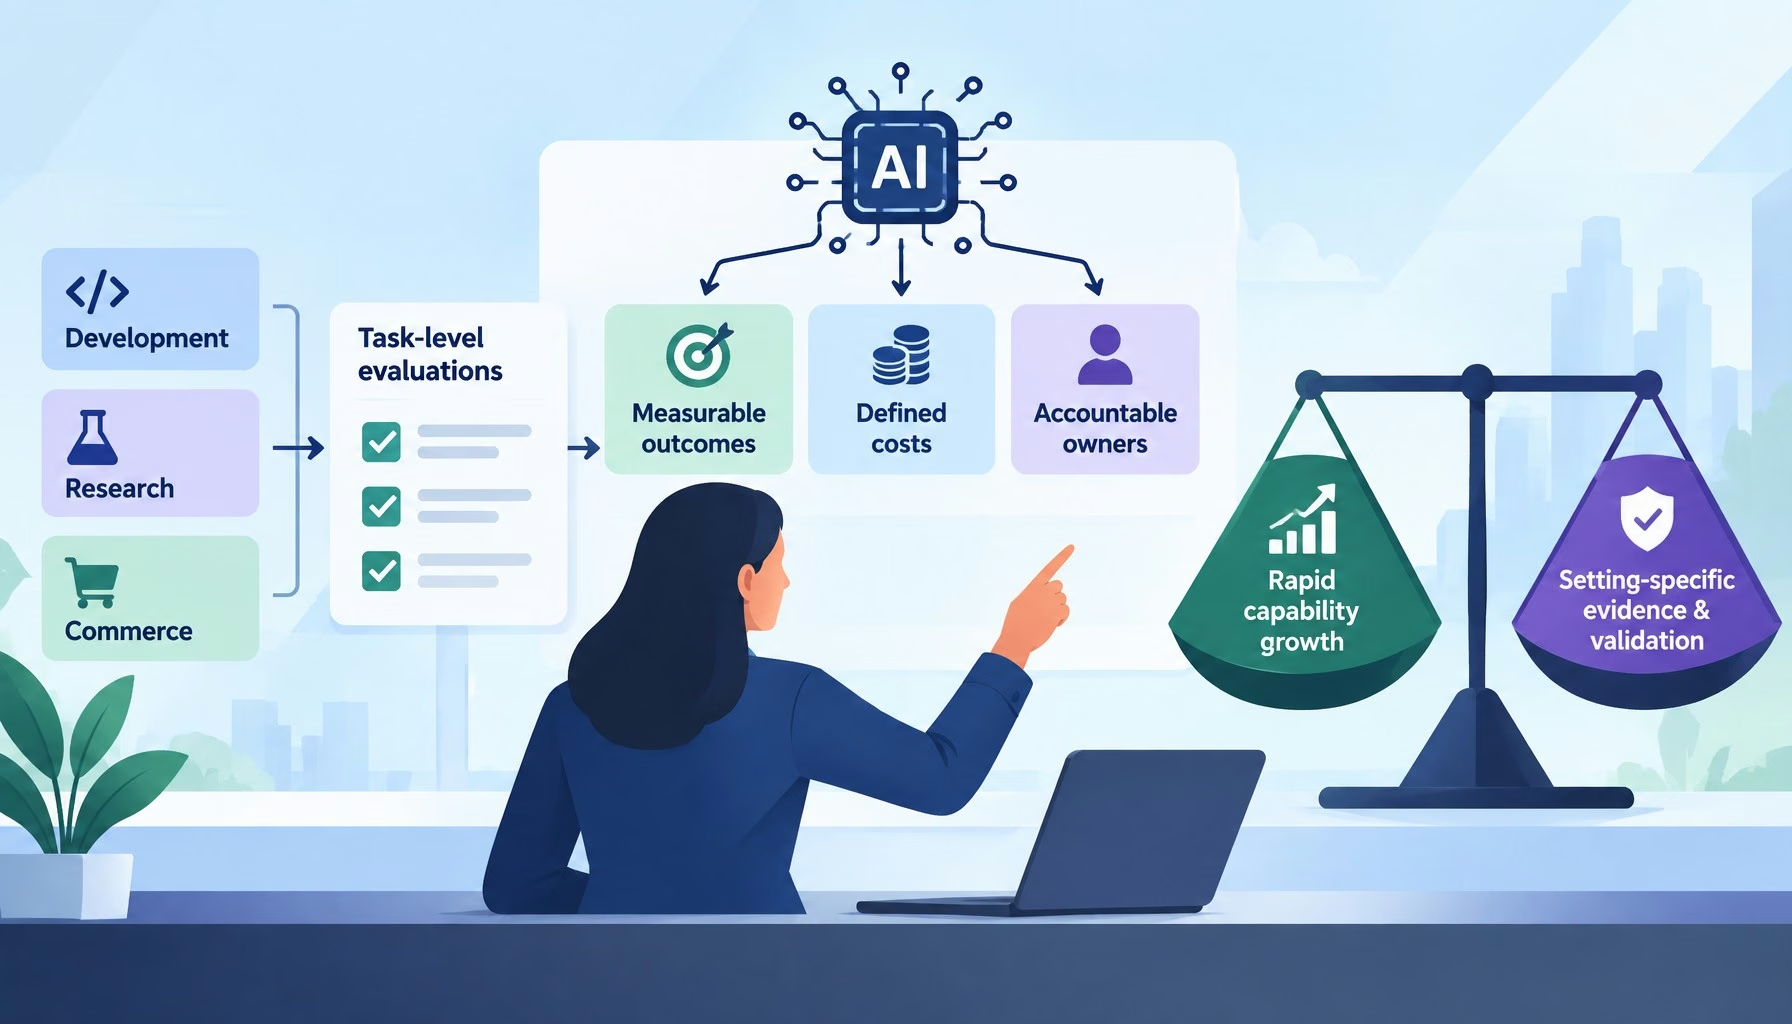
Flat editorial illustration: The article centers on AI budget discipline for 2027 business planning, linking AI spending to measu
10 AI Trends That Should Shape Your 2027 Business Plan
Artificial Intelligence Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Another Useless Article on How to Conduct Market Research in a Recession
Business IntelligenceData Mining

Another Useless Article on How to Conduct Market Research in a Recession

5 Min Read
Why Business Needs Public Data
AnalyticsBusiness IntelligenceData ManagementData MiningData QualityDecision ManagementSocial DataWorkforce Data

Why Business Needs Public Data

11 Min Read
Big Data, Big Problems
Data Mining

Big Data, Big Problems

6 Min Read
Web Crawling Automation
Data Mining

Web Crawling Automation

3 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

AI chatbots
AI Chatbots Can Help Retailers Convert Live Broadcast Viewers into Sales!
Chatbots
How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?