We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Reflecting on Times Open
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Uncategorized > Reflecting on Times Open
Uncategorized

Reflecting on Times Open

Daniel Tunkelang
Daniel Tunkelang
7 Min Read
Reflecting on Times Open
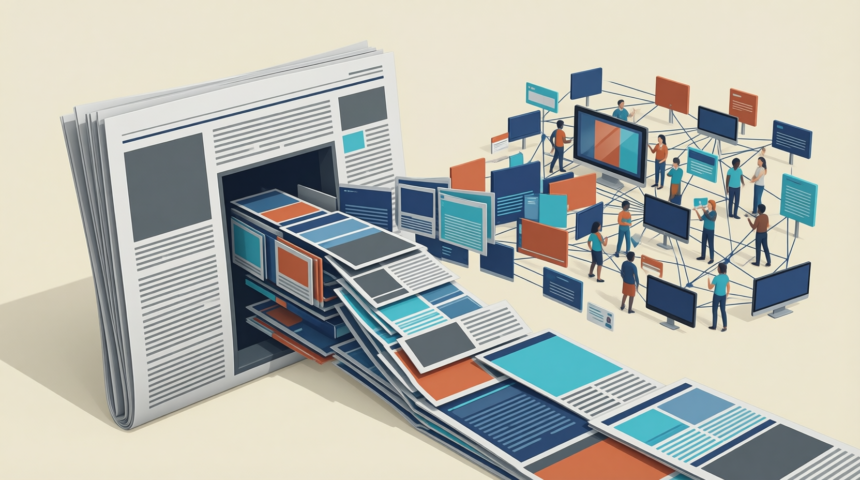
Illustration generated with Qwen Image.
SHARE

Like everyone else who managed to get into the standing room only event (or at least everyone I had a chance to meet there), I had a great time at Times Open, the New York Times’s coming out party for its APIs. I won’t try to summarize, since Taylor Barstow has already done that superbly (also, check out his nytexplorer app!).

Also, people have commented about the intense Twitter conversations that took place during the presentations. I feel strongly that they added to the event (see my response to Owen Thomas on Valleywag). And, by no coincidence, I want to use this space to talk about what I felt to be the most interesting topic that came up through the event: the handling of user-generated content.

The New York Times is one of the world’s oldest and most prestigious media brands. As their CEO  Janet Robinson proudly told us, the paper has won 98 Pulitzer Prizes, more than any other newspaper. Moreover, she added, they have been around for 158 years and plan to be around for another 158 years. For perspective, some folks don’t even give the New York Times 158 days to live! Despite the thei recent financial troubles, I think they’re here for the long haul–and not because I  have any financial interest in their success. Rather, it is because I see the vast numbers of people who look to the New York Times as something more than news wire with a pretty logo.

They care about the most personal aspects of the paper, like its columnists. When Tim O’Reilly called attention to science and technology writer John Markoff, everyone turned to him, eager to put a face on a writer whom many of us have been reading since before there was a World Wide Web. With all respect for the Associated Press, I can imagine that they or their staff command this sort of devotion. Personality makes a big difference, and personality comes from people.
More Read

The Big Data Contrarians: New LinkedIn Big Data Community
Refusing to Answer Census Race Question
Guest Post by Brent Arslaner: The Next Generation of Lead Generation
Email Marketing Isn’t Dead!
Top Big Data Challenges Revisited

But of course there are far more people reading the New York Times than writing it. Those people increasingly want to play a more active role. They do so in various ways today:

  • Contributing to the “Most Popular” stats by email articles to one another.
  • Commenting on the select  articles that offer this opportunity.
  • Linking to articles in their blog posts, tweets, and other social media.

Here is an audience eager to participate! But there’s a big catch: the New York Times is paranoid of diluting its brand equity by mixing up user contributions with their carefully vetted writing. As a result, all comments are moderated, and their aggregation of blogs linking to articles is a limited, proprietary system (Blogrunner). The New York Times wants to have its cake and eat it–all the benefits from users’ active engagement without the costs of diluting their brand.

I think their APIs make this possible, at least in theory. Someone else can now repurpose New York Times content, allow others to annotate it, etc. The concern now is licensing and monetization. Surely the New York Times won’t simply let someone else mirror their site with looser restrictions about user-generated content. Or will it, for the right price?

Money issues aside, can readers get used to the idea that authorship and its associated brand equity is independent of the site on which content appears? Can media brands embrace such a new world? And, if user-generated content starts to blur the line between readers and writers, does a media company morph from a publisher to that of a professional editor-in-chief of a sprawling graph of writers and amateur editors?

These questions, which strike me as some the key questions for the future of newspapers, stuck in my mind as I left Times Open. I’m curious what others think? Are these the right questions? And, if they are, what are the answers?
Link to original post

Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article explains that training robots for physical interaction requires three distinct data cate
Physical AI: What Data Do You Need to Train a Robot?
Artificial Intelligence Exclusive Robotics
What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
Analytics Big Data Exclusive Software
Flat editorial illustration: The article examines AI agents that escalate from legitimate data retrieval to attempted intrusions
OpenAI’s Government Website Incidents Raise a Hard Question for AI Agents: When Should They Stop?
Artificial Intelligence News Security
Flat editorial illustration: The article's core relationship is the alignment between customer behavioral data (visit frequency,
Data-Driven Loyalty: How Restaurants Use Behavioral Analytics to Optimize Revenue
Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

The Importance of Data Experimentation
Uncategorized

The Importance of Data Experimentation

4 Min Read
Push vs. Pull Supply Chain Models: What You Need to Know
Uncategorized

Push vs. Pull Supply Chain Models: What You Need to Know

5 Min Read
Data Cleansing vs Data Maintenance: Which One Is Most Important?
Uncategorized

Data Cleansing vs Data Maintenance: Which One Is Most Important?

5 Min Read
The Thin Edge of the Wedge for Virtual Reality
Uncategorized

The Thin Edge of the Wedge for Virtual Reality

1 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

5 Great Tips for Using Data Analytics for Website UX
Big Data
AI chatbots
AI Chatbots Can Help Retailers Convert Live Broadcast Viewers into Sales!
Chatbots

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?