We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
    cybersecurity efforts
    How Behavioral Analytics and AI Are Redefining Cybersecurity for Boca Raton Businesses
    14 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: What is Hadoop?
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Big Data > Data Mining > What is Hadoop?
Business IntelligenceData MiningData WarehousingPredictive Analytics

What is Hadoop?

TonyBain
TonyBain
5 Min Read
What is Hadoop?
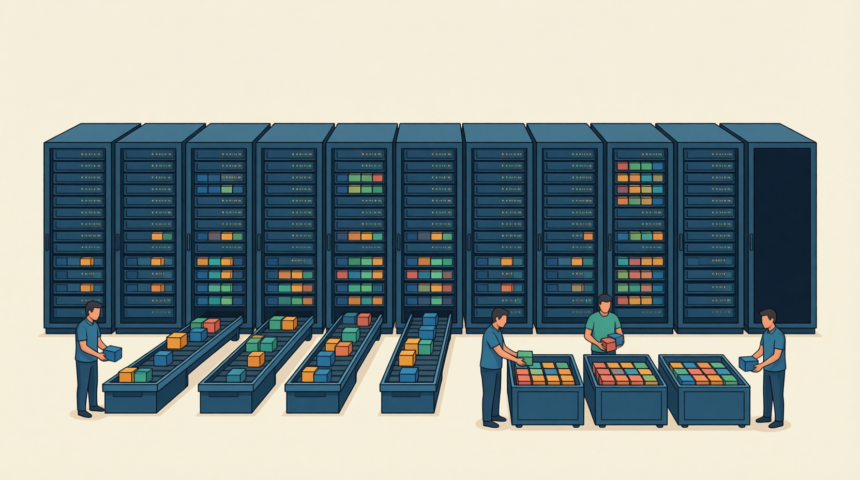
Illustration generated with Qwen Image.
SHARE

Image via CrunchBase

Ok so you are setting out to build the next Google and are considering using a Map/Reduce based data access strategy over traditional SQL.  Just as you need a database server to process SQL queries you also require the underlying infrastructure to manage your data and to execute your Map/Reduce routines.  Hadoop is one such system that is gaining acceptance, being co-developed and implemented for data analytics purposes at Yahoo and Facebook amongst others.

Hadoop is the system that allows unstructured data to be distributed across hundreds or thousands of machines forming shared nothing clusters, and the execution of Map/Reduce routines to run on the data in that cluster.  Hadoop has its own filesystem which replicates data to multiple nodes to ensure  if one node holding data goes down, there are at least 2 other nodes from which to retrieve that piece of information.  This protects the data availability from node failure, something which is critical when there are many nodes in a cluster (aka RAID at a server level).

So will Hadoop outperform a RDBMS?  Well unless you are dealing with very large volumes of unstructured data (hundreds of GB, TB’s or PB’s) and have large numbers of machines available you will likely find the performance of Hadoop running a Map/Reduce query much slower than a comparable SQL query on a relational database.  Hadoop uses a brute force access method whereas RDBMS’s have optimization methods for accessing data such as indexes and read-ahead.  The benefits really do only come into play when the positive of mass parallelism is achieved, or the data is unstructured to the point where no RDBMS optimizations can be applied to help the performance of queries.  Indeed benchmarks from the Hadoop site show performance significantly slower in straight line query performance when compared to a relational DB on small scale tests.
More Read

Big Data and the Evolution of Supply Chain Planning
Marketing Planning Improves Performance
Social Engineering — Hacking by Asking
Using Predictive Analytics to Fight Crime
Recurring Revenue Strategies for the AI Business Era
 
MySql 5.0.27Hadoop-0.15.2
DataB-tree disk table (MyISAM)Text files (access_log)
Machine12
Rows5,914,6695,914,669
Results100100
Time4.43 sec172.30 sec

But with all benchmarks everything has to be taken into consideration.  For example, if the data starts life in a text file in the file system (e.g. a log file) the cost associated with extracting that data from the text file and structuring it into a standard schema and loading it into the RDBMS has to be considered.  And if you have to do that for 1000 or 10,000 log files that may take minutes or hours or days to do (with Hadoop you still have to copy the files to its file system).  It may also be practically impossible to load such data into a RDBMS for some environments as data could be generated in such a volume that a load process into a RDBMS cannot keep up.  So while using Hadoop your query time may be slower (speed improves with more nodes in the cluster) but potentially your access time to the data may be improved. 

Also as there aren’t any mainstream RDBMS’s that scale to thousands of nodes, at some point the sheer mass of brute force processing power will outperform the optimized, but restricted on scale, relational access methods.

So while Hadoop and Map/Reduce are gaining more popularity it shouldn’t be considered a like for like alternative to a relational RDBMS for most applications.  It is a specialized tool with a specialized set of criteria that need to be fulfilled to achieve benefit over more traditional approaches.

Related articles by Zemanta
  • Yahoo Search Wants to Be More Like Google, Embraces Hadoop
  • Yahoo’s Supercomputing Initiative Running Hadoop

Link to original postInnovations in information management

Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Illustration of mobile analytics dashboards with ad performance charts connected to backend databases
11 Best Sisense Alternatives for Embedded Analytics
Business Intelligence Exclusive
Analyst points at colorful circular data dashboard on screen - information technology business metrics
How Fragmented Workplace Tech Undermines Reliable Business Metrics and Reporting
Cloud Computing Exclusive Infographic IT
Using Multi-Source Data and Analytics to Detect Operational Drift Across Franchise Networks -- AI-generated illustration
Using Multi-Source Data and Analytics to Detect Operational Drift Across Franchise Networks
Exclusive Infographic
Beyond The First Impression: The Long-Lasting Impact Of Sensory Marketing -- AI-generated illustration
Beyond The First Impression: The Long-Lasting Impact Of Sensory Marketing
Infographic Marketing

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

A Poorly Managed Company’s Tour Guide: Performance Mangement and the 'Mesdup' Corporation
Business IntelligencePredictive Analytics

A Poorly Managed Company’s Tour Guide: Performance Mangement and the ‘Mesdup’ Corporation

11 Min Read
Information-age Stimulus
Business Intelligence

Information-age Stimulus

20 Min Read
Huge Benefits of Business Intelligence for Your Company
Business Intelligence

Huge Benefits of Business Intelligence for Your Company

8 Min Read
Safeguarding Patient Data in EHRs
Data MiningData WarehousingSecurity

Safeguarding Patient Data in EHRs

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

AI chatbots
AI Chatbots Can Help Retailers Convert Live Broadcast Viewers into Sales!
Chatbots
The Art of Conversation: Enhancing Chatbots with Advanced AI Prompts
Chatbots

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?