We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Why Does Latent Semantic Analysis Work?
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Uncategorized > Why Does Latent Semantic Analysis Work?
Uncategorized

Why Does Latent Semantic Analysis Work?

Daniel Tunkelang
Daniel Tunkelang
4 Min Read
Why Does Latent Semantic Analysis Work?
Illustration generated with Qwen Image.
SHARE

Warning to regular readers: this post is a bit more theoretical than average for this blog.

Peter Turney has a nice post today about “SVD, Variance, and Sparsity“. It’s actually a follow-up to a post last year entitled “Why Does SVD Improve Similarity Measurement?” that apparently has remained popular despite its old age in blog years.

For readers unfamiliar with singular value decomposition (SVD), I suggest a brief detour to the Wikipedia entry on latent semantic analysis (also known as latent semantic indexing). In a nutshell, latent semantic analysis is an information retrieval techinque that applies SVD to the term-document matrix of a corpus in order to reduce this sparse, high-dimensional matrix to a denser, lower-dimensional matrix whose dimensions correspond to the “latent” topics in the corpus.

Back to Peter’s thesis. He’s observed that document similarity is more accurate in the lower-dimensional vector space produced by SVD than in the space defined by the original term-document matrix. This isn’t immediately obvious; after all, SVD is a lossy approximation of the term-document matrix, so you might expect accuracy to decrease.
More Read

IBM Will Take Varicent for Sales Performance Management
Leadership Lessons in Data Quality – Part 1
Data pre-processing in PMML and ADAPA – A Primer
Spice Up Your Spreadsheets: Boosting BI with Google Spreadsheets
No Wait in Kuwait – But Some Weight

In his 2007 post, Peter offers three hypotheses for why SVD improves the similarity measure:

  1. High-order co-occurrence: Dimension reduction with SVD is sensitive to high-order co-occurrence information (indirect association) that is ignored by PMI-IR and cosine similarity measures without SVD. This high-order co-occurrence information improves the similarity measure.
  2. Latent meaning: Dimension reduction with SVD creates a (relatively) low-dimensional linear mapping between row space (words) and column space (chunks of text, such as sentences, paragraphs, or documents). This low-dimensional mapping captures the latent (hidden) meaning in the words and the chunks. Limiting the number of latent dimensions forces a greater correspondence between words and chunks. This forced correspondence between words and chunks (the simultaneous equation constraint) improves the similarity measurement.
  3. Noise reduction: Dimension reduction with SVD removes random noise from the matrix (it smooths the matrix). The raw matrix contains a mixture of signal and noise. A low-dimensional linear model captures the signal and removes the noise. (This is like fitting a messy scatterplot with a clean linear regression equation.)

In today’s follow-up post, he drills down on this third hypothesis, noting that noise can come from either variance and sparsity. He then proposes independently adjusting the sparsity-smoothing and variance-smoothing effects of SVD to split this third hypothesis into two sub-hypotheses.

I haven’t done much work with latent semantic analysis. But work that I’ve done with other statistical information retrieval techinques, such as using Kullback-Leibler divergence to measure the signal of a document set, suggest a similar benefit from preprocessing steps that reduce noise. Now I’m curious about the relative benefits of variance vs. sparsity reduction.
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is workload-by-workload decision-making for cloud migration, where s
Which Workloads Should Move to the Cloud?
Cloud Computing Exclusive IT
Flat editorial illustration: The article positions data governance as a strategic board-level concern rather than a purely techni
Why Data Governance Is Becoming a Board-Level Business Priority
Big Data Exclusive Policy and Governance
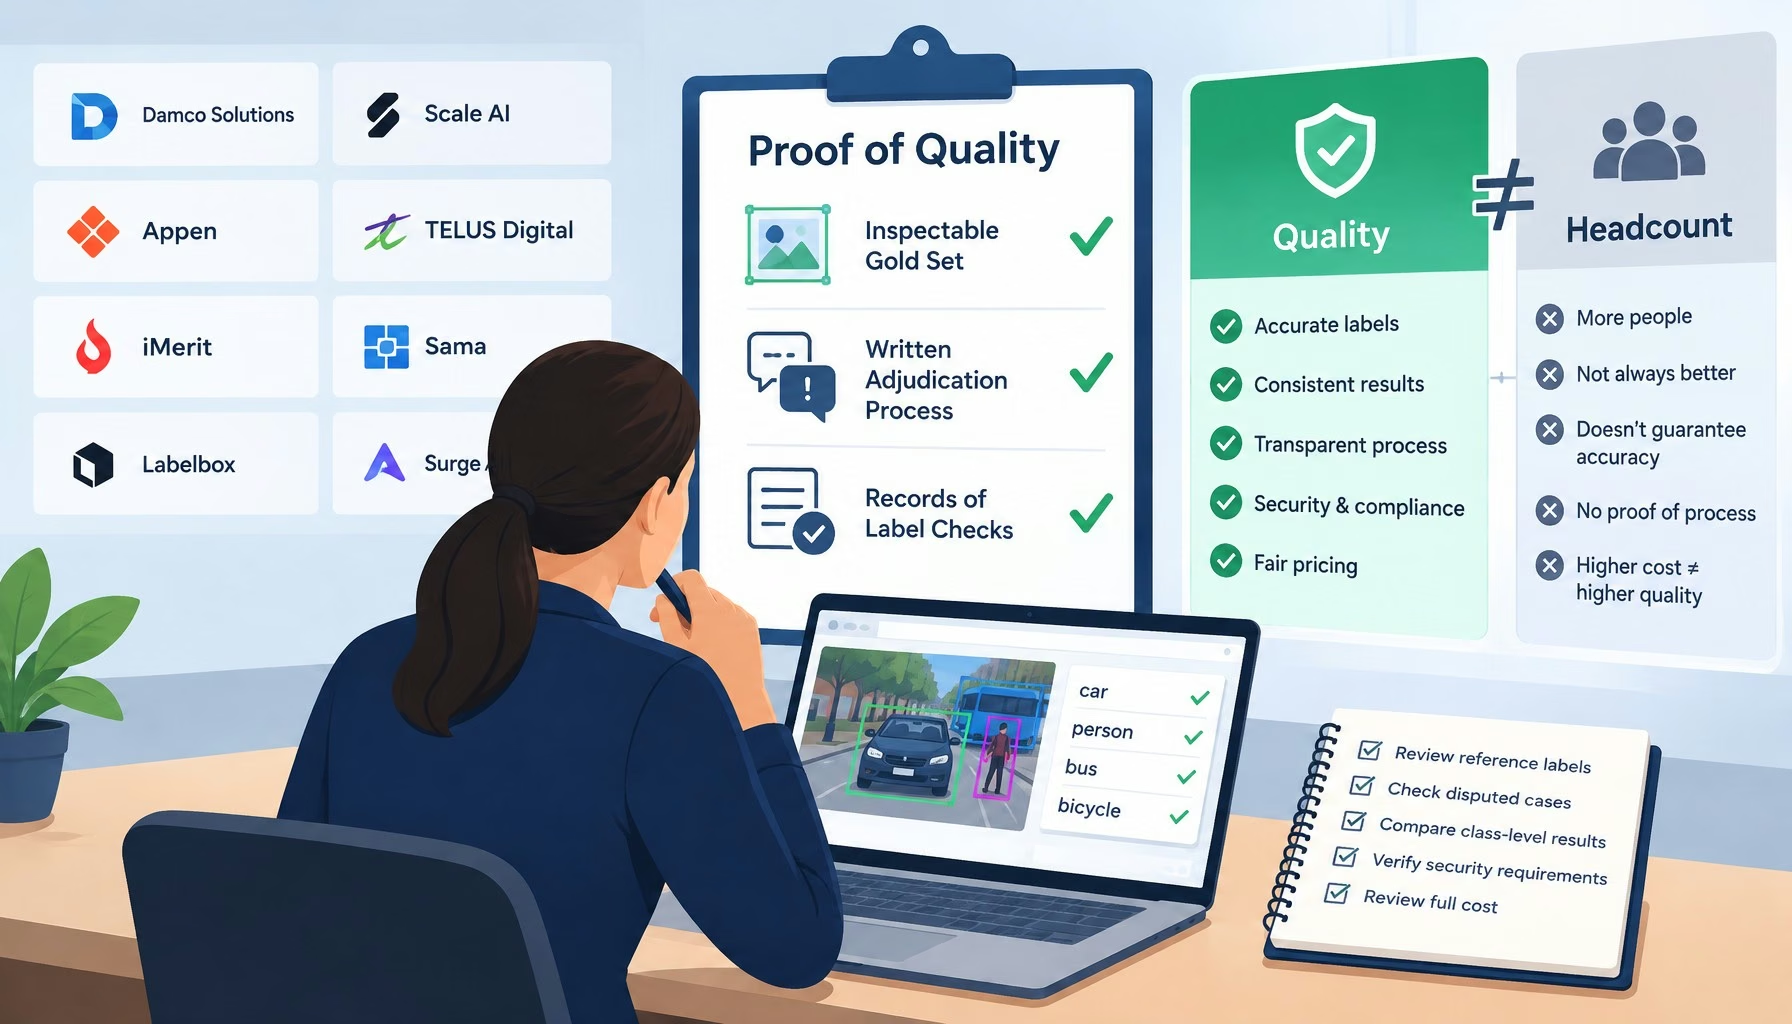
Flat editorial illustration: The article argues that data annotation quality should be measured by inspectable gold sets, written
The Top Data Annotation Companies Are Separated by Proof of Quality, Not Headcount
Big Data Exclusive
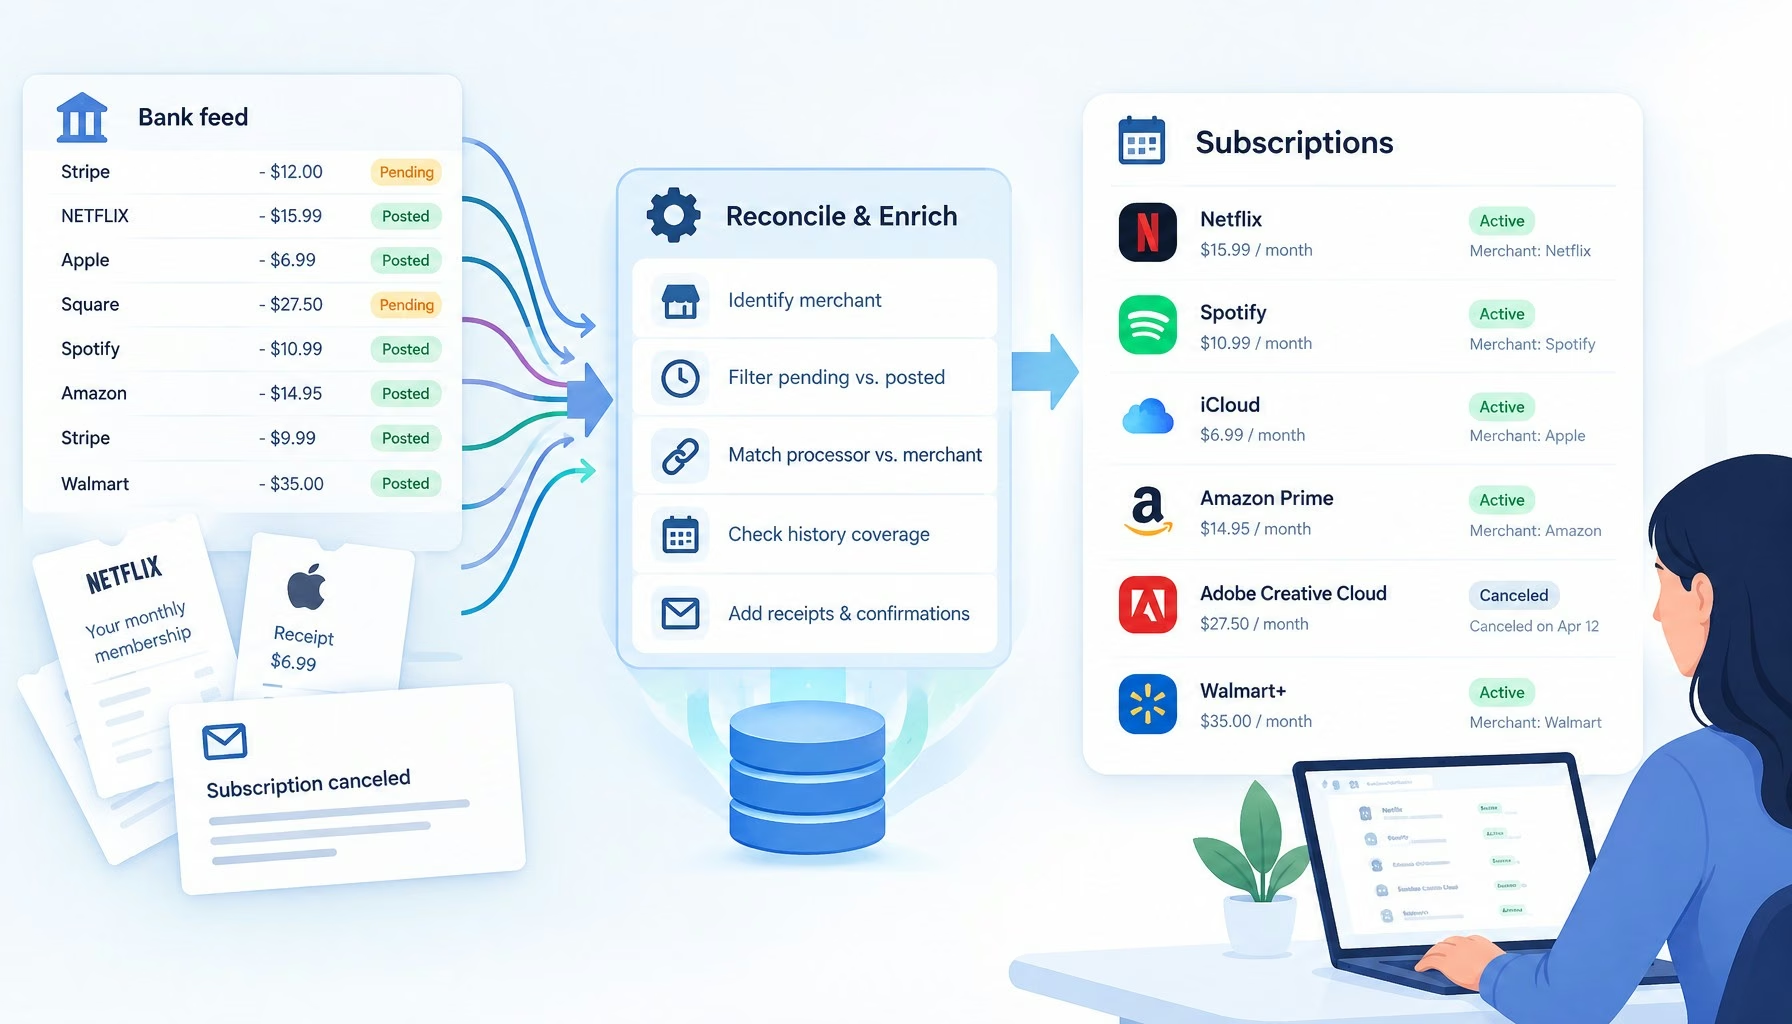
Flat editorial illustration: The article's core relationship is the gap between raw bank-feed records and reliable subscription i
Subscription Trackers Have a Transaction Data Problem
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Platform distribution risks
Uncategorized

Platform distribution risks

4 Min Read
Four and a Half Types of NoSQL Databases, and When to Use Them
Uncategorized

Four and a Half Types of NoSQL Databases, and When to Use Them

8 Min Read
Are people more willing to pay for digital goods on mobile devices?
Uncategorized

Are people more willing to pay for digital goods on mobile devices?

5 Min Read
Everybody’s on the Phone
Uncategorized

Everybody’s on the Phone

3 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

From Bolts to Bots: How AI Is Fortifying the Automotive Industry
Artificial Intelligence
The Art of Conversation: Enhancing Chatbots with Advanced AI Prompts
Chatbots

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?