We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
    cybersecurity efforts
    How Behavioral Analytics and AI Are Redefining Cybersecurity for Boca Raton Businesses
    14 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Doing Data Mining Out of Order
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Big Data > Data Mining > Doing Data Mining Out of Order
Data Mining

Doing Data Mining Out of Order

DeanAbbott
DeanAbbott
4 Min Read
Doing Data Mining Out of Order
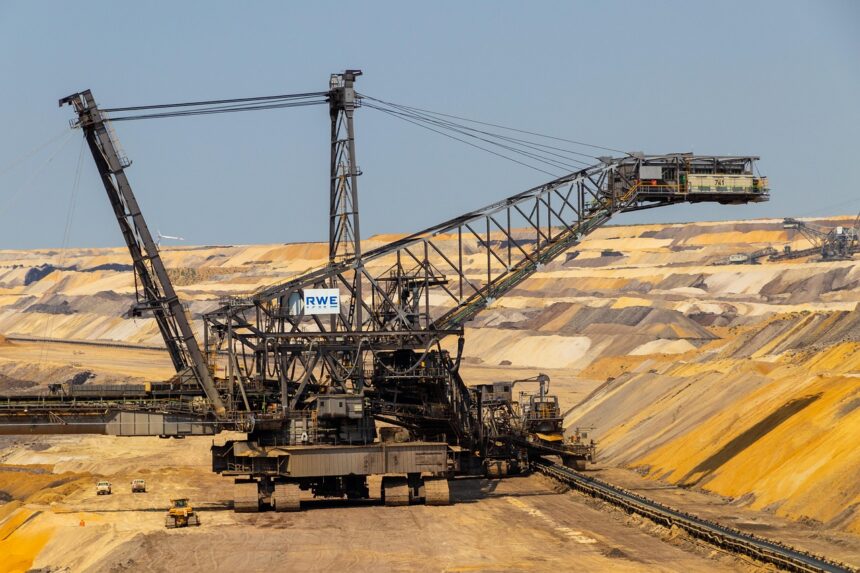
Photo by herbert2512 on Pixabay (https://pixabay.com/photos/open-pit-mining-3563106/)
SHARE

I like the CRISP-DM process model for data mining, teach from it, and use it on my projects. I commend it to practitioners and managers routinely as an aid during any data mining project. However, while the process sequence is generally the one I use, I don’t always; data mining often requires more creativity and “art” to re-work the data than we would like; it would be very nice if we could create a checklist and just run through the list on every project! But unfortunately data doesn’t always cooperate in this way, and we therefore need to adapt to the specific data problems so that the data is better prepared.

For example, on a current financial risk project I am working, the customer is building data for predictive analytics for the first time. The customer is data savvy, but new to predictive analytics, so we’ve had to iterate several times on how the data is pulled and rolled up out of the database. In particular, target variable has had to be cleaned up because of historic coding anomalies.

One primary question to resolve for this project is an all-too-common debate over what is the right level of aggregation: do we use transactional data even though some customers have many transactions and some have few, or do we roll data up to the customer level to build customer risk models. (A transaction-based model will score each transaction for risk, whereas a customer-based model will score, daily, the risk associated with each customer given the new transactions that have been added.) There are advantages and disadvantages to both, but in this case, we are building a customer-centric risk model for reasons that make sense in this particular business context.

Back to the CRISP-DM process and why it is advantageous to deviate from CRISP-DM. In this project, we jumped from Business Understanding and the beginnings of Data Understanding straight to Modeling. I think in this case, I would call it “modeling” (small ‘m’) because we weren’t building models to predict risk, but rather to understand the target variable better. We were not sure exactly how clean the data was to begin with, especially the definition of the target variable, because no one had ever looked at the data in aggregate before, only on a single customer-by-customer basis. By building models, and seeing some fields that predict the target variable “too well”, we have been able to identify historic data inconsistencies and miscoding.
More Read

Software Dependence & Model Accuracy
The Big Data Security Transformation
Why Business Needs Public Data
Data Mining Soft Skills
Analytics, Graph Search, APIs: Is Facebook Struggling with Big Data?

Now that we have the target variable better defined, I’m going back to the data understanding and data prep stages to complete those stages properly, and this is changing how the data will be prepped in addition to modifying the definition of the target variable. It’s also much more enjoyable to build models than do data prep, so for me this was a “win-win” anyway!

Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article examines AI agents that escalate from legitimate data retrieval to attempted intrusions
OpenAI’s Government Website Incidents Raise a Hard Question for AI Agents: When Should They Stop?
Artificial Intelligence News Security
Flat editorial illustration: The article's core relationship is the alignment between customer behavioral data (visit frequency,
Data-Driven Loyalty: How Restaurants Use Behavioral Analytics to Optimize Revenue
Exclusive
Flat editorial illustration: The article's core relationship is that reliable eCommerce attribution depends on a unified, well-st
How eCommerce Data Teams Can Build Attribution That Holds Up
Big Data Exclusive
Flat editorial illustration: The article's core relationship is the contrast between fragmented inherited data infrastructure (wh
Data Stack Consolidation as a Data Quality and Governance Strategy for Mid-Market Teams
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

B2B Software Startups: The SaaS Platform Dilemma
AnalyticsBest PracticesBig DataCloud ComputingCollaborative DataCRMData ManagementData MiningData VisualizationExclusiveITSocial DataSocial Media AnalyticsSoftwareWorkforce Analytics

B2B Software Startups: The SaaS Platform Dilemma

8 Min Read
The Use and Abuse of Big Data
AnalyticsBig DataData MiningPrivacySecurity

The Use and Abuse of Big Data

5 Min Read
Interview:  Dr Graham Williams
Data Mining

Interview: Dr Graham Williams

13 Min Read
Cloud Computing Lingo
Business IntelligenceData MiningData WarehousingPredictive Analytics

Cloud Computing Lingo

6 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

The Art of Conversation: Enhancing Chatbots with Advanced AI Prompts
Chatbots
Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?