We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Probabilistic Matching: Part Two
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Uncategorized > Probabilistic Matching: Part Two
Uncategorized

Probabilistic Matching: Part Two

SteveSarsfield
SteveSarsfield
6 Min Read
Probabilistic Matching: Part Two
Illustration generated with Qwen Image.
SHARE

Matching algorithms, the functions that allow data quality tools to determine duplicate records and create households, are always a hot topic in the data quality community. In a previous installment of the Data Governance and Data Quality Insider, I wrote about the folly of probabilistic matching and its inability to precisely tune match results.

To recap, decisions for matching records together with probabilistic matchers are based on three things: 1) statistical analysis of the data; 2) a complicated mathematical formula, and; 3) and a “loose” or “tight” control setting. Statistical analysis is important because under probabilistic matching, data that is more unique in your data set has more weight in determining a pass/fail on the match. In other words, if you have a lot of ‘Smith’s in your database, Smith becomes a less important matching criterion for that record. If the record has a unique last name like ‘Afinogenova’ that’ll carry more weight in determining the match.

The trouble comes when you don’t like the way records are being matched. Your main course of action is to turn the dial on the loose/tight control to see if you can get the records to match without affecting record matching elsewhere in the process. Little provision is made for precise control of what records match and what records don’t. Always, there is some degree of inaccuracy in the match.

In other forms of matching, like deterministic matching and rules-based matching, you can very precisely control which records come together and which ones don’t. If something isn’t matching properly, you can make a rule for it. The rules are easy to understand. It’s also very easy to perform forensics on the matching and figure out why two records matched, and that comes in handy should you ever have to explain to anyone exactly why you deduped any given record.
More Read

The Perfect Storm: Service Aggregation, Automation and Management
SnapLogic: Making Big Data Integration as a Service a Hadoop Reality
3 Ways Data-Driven Marketing Drives Higher ROI
3 Cloud Computing Security Holes to Watch Out For
Componentizing Software

But there is another major folly of probabilistic matching – namely performance. Remember, probabilistic matching relies heavily on statistical analysis of your data. It wants to know how many instances of “John” and “Main Street” are in your data before it can determine if there’s a match.

Consider for a moment a real time implementation, where records are entering the matching system, say once per second. The solution is trying to determine if the new record is almost like a record you already have in your database. For every record entering the system, shouldn’t the solution re-run statistics on the entire data set for the most accurate results? After all, the last new record you accepted into your database is going to change the stats, right? With medium-sized data sets, that’s going to take some time and some significant hardware to accomplish. With large sets of data, forget it.

Many vendors who tout their probabilistic matching secretly have work-arounds for real time matching performance issues. They recommend that you don’t update the statistics for every single new record. Depending on the real-time volumes, you might update statistics nightly or say every 100 records. But it’s safe to say that real time performance is something you’re going to have to deal with if you go with a probabilistic data quality solution.

Better yet, you can stay away from probabilistic matching and take a much less complicated and much more accurate approach – using time-tested pre-built business rules supplemented with your own unique business rules to precisely determine matches.
Covering the world of data integration, data governance, and data quality from the perspective of an industry insider.
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is the gap between raw bank-feed records and reliable subscription i
Subscription Trackers Have a Transaction Data Problem
Big Data Exclusive
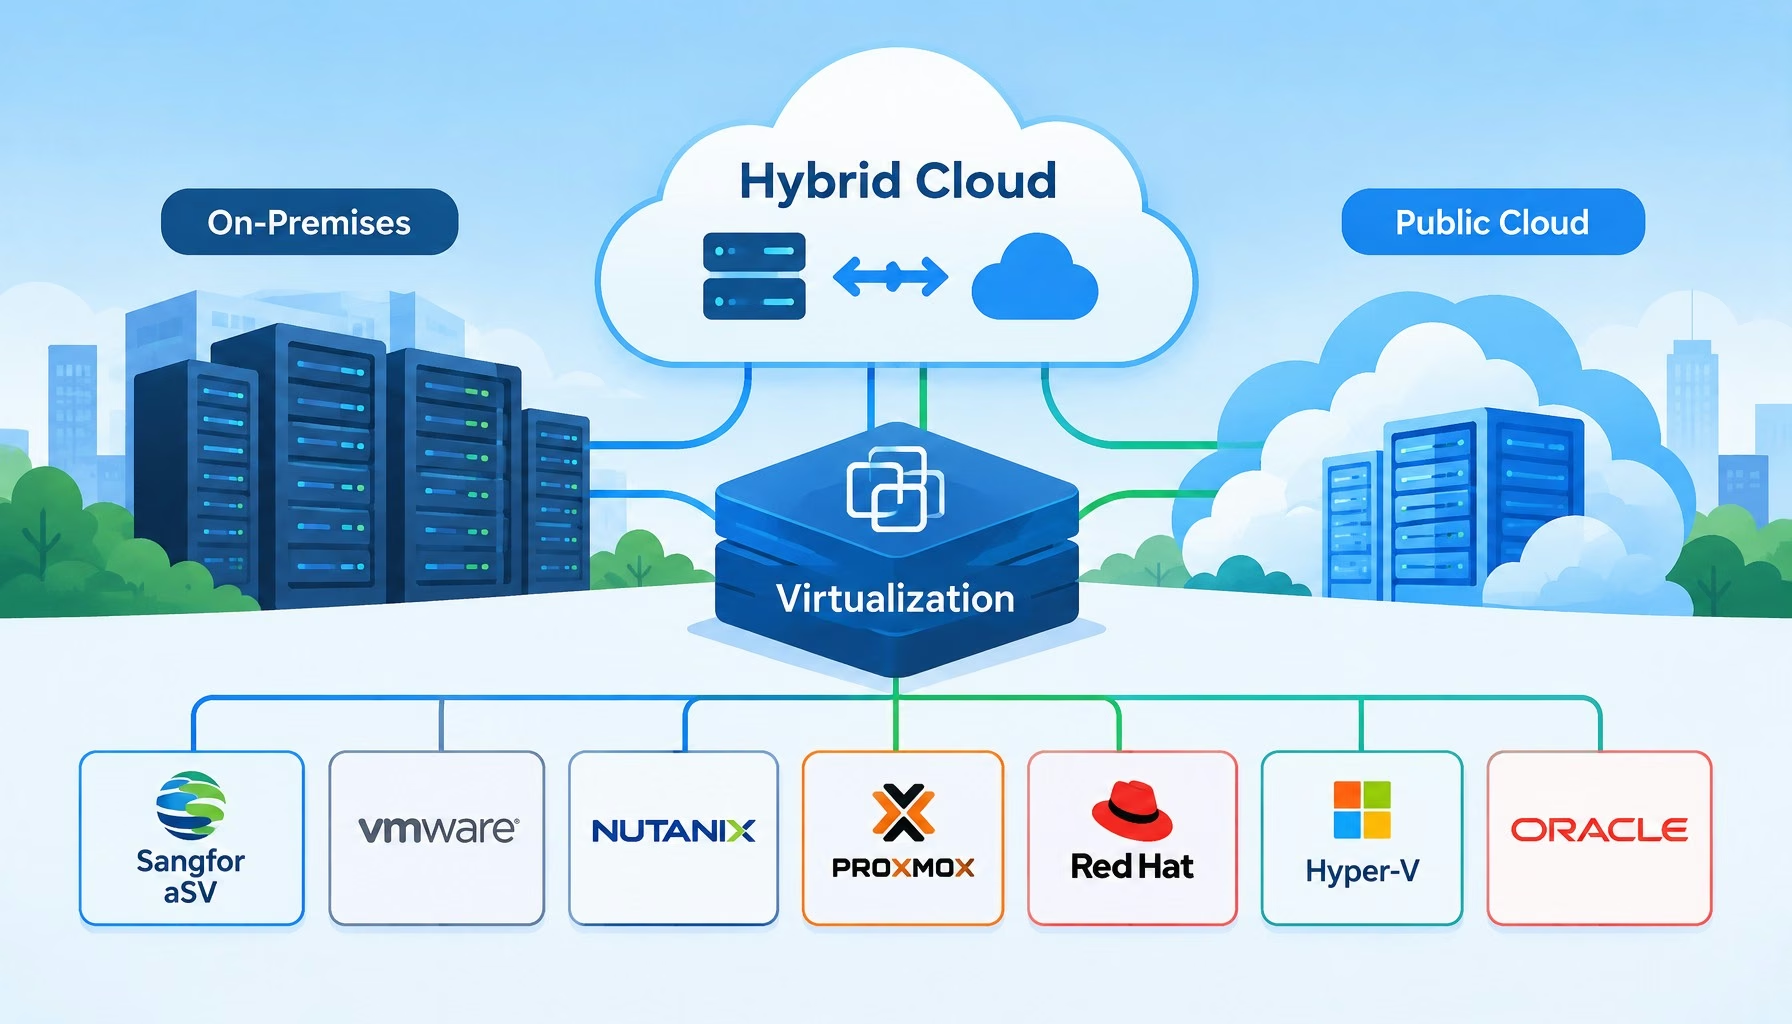
Flat editorial illustration: The article's core relationship is the hypervisor as the abstraction layer that makes hybrid cloud p
7 Best Virtualization Platforms for Hybrid Cloud Environments
Big Data
Flat editorial illustration: The article's core relationship is between aggregated workplace data (occupancy, environmental, feed
How Businesses Can Use Workplace Data to Create Better Office Environments
Big Data Business Intelligence Exclusive
Flat editorial illustration: The article's core relationship is the engineering transition from an AI prototype to a production-r
From AI Prototype to Production: Observability and Scalability Requirements for Data-Heavy SaaS Applications
Artificial Intelligence Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Python and Productivity
Uncategorized

Python and Productivity

6 Min Read
Decision Tree Bagging System (R code)
Uncategorized

Decision Tree Bagging System (R code)

9 Min Read
Does the Future Lie with Embedded BI?
Uncategorized

Does the Future Lie with Embedded BI?

8 Min Read
The Social Employee Manifesto
Uncategorized

The Social Employee Manifesto

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

AI chatbots
AI Chatbots Can Help Retailers Convert Live Broadcast Viewers into Sales!
Chatbots
ai chatbot
How AI Website Chatbots Improve Customer Support and Lead Generation
Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?