We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Terabytes of trees
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Big Data > Data Mining > Terabytes of trees
Data Mining

Terabytes of trees

DavidMSmith
DavidMSmith
4 Min Read
Terabytes of trees
Illustration generated with FLUX.2 [klein 4B] via Cloudflare Workers AI.
SHARE

I saw a very interesting talk at hosted by the SF Bay ACM last night. Google engineer Josh Herbach talked about the platform he’d implemented to build boosted and bagged trees on very large data sets using MapReduce. (A longer version of the talk will be presented at VLDB2009 later this month.) The data is distributed amongst many machines in gfs (Google Filesystem): Google Adwords data, with information on each user of Google Search and each click they have made, can run to terabytes and take three days to build a predictive tree. 

The algorithm is quite elegant: after an initialization phase to identify candidate cut-points for continuous predictors and values of categorical variables, the Map step selects a node to add a new chunk of data to, and then calculates a deviance score for a number of candidate splits. The reduce step selects the best split from the various candidates evaluated in the distributed nodes. The process repeats to create a single tree or (as is actually used in practice) a number of bagged and/or boosted trees. One interesting wrinkle: for implementation reasons, the bagged trees use sampling without replacement rather than with replacement (as bagging is usually defined). Given the amount of data, I’m not sure this makes any practical difference though. Interestingly, he did compare the results to heavily sampling the data and building the tree in-memory in R (all of his charts were done in R, too). He was quite adamant that using all of the data is “worth it” compared to sampling — and with Google’s business model of monetizing the long tail, I can believe it. 
Josh mentioned that all of the techniques he’d implemented could also be implemented using Hadoop, the open-source map-reduce application. This got me thinking that some interesting out-of-memory techniques could be implemented in R via Rhipe, using R statistics functions to implement the Map operations, and R data aggregation for the Reduce functions. Hmm, I feel a new project coming on…

SF Bay ACM: PLANET: Massively Parallel Learning of Tree Ensembles with MapReduce

Link to original post
TAGGED:hadoopMapReducer
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is workload-by-workload decision-making for cloud migration, where s
Which Workloads Should Move to the Cloud?
Cloud Computing Exclusive IT
Flat editorial illustration: The article positions data governance as a strategic board-level concern rather than a purely techni
Why Data Governance Is Becoming a Board-Level Business Priority
Big Data Exclusive Policy and Governance
Flat editorial illustration: The article argues that data annotation quality should be measured by inspectable gold sets, written
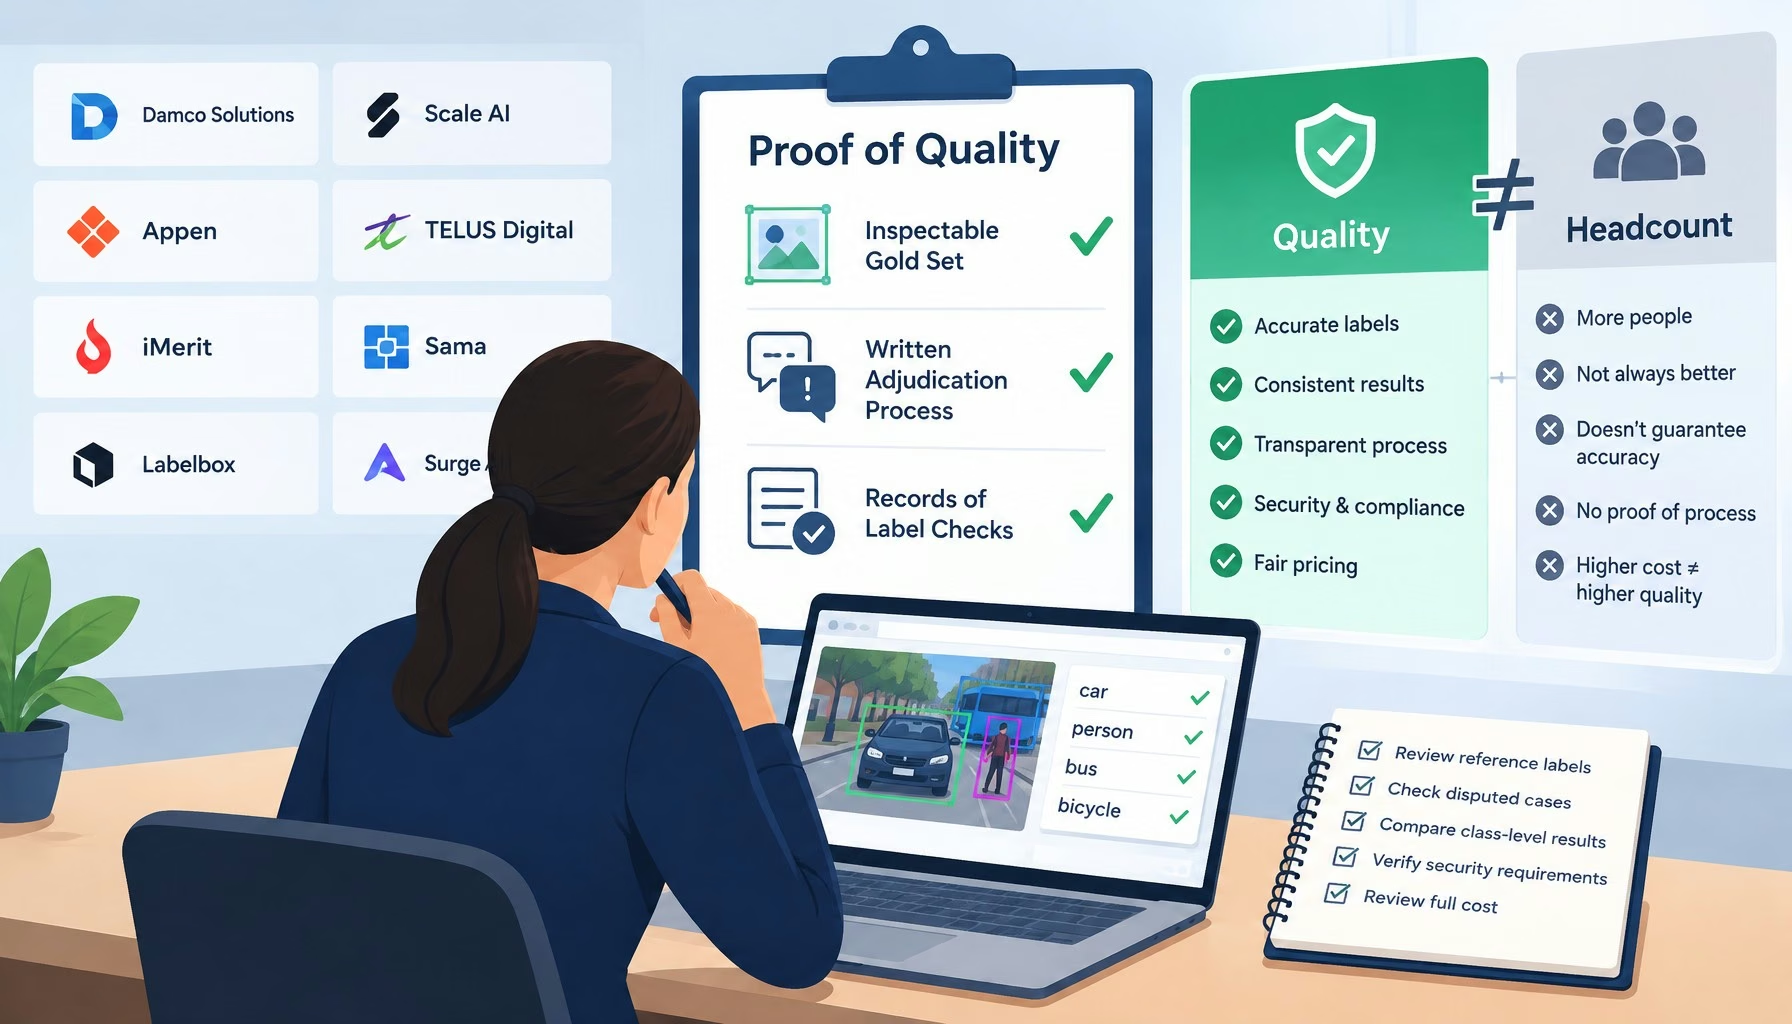
The Top Data Annotation Companies Are Separated by Proof of Quality, Not Headcount
Big Data Exclusive
Flat editorial illustration: The article's core relationship is the gap between raw bank-feed records and reliable subscription i
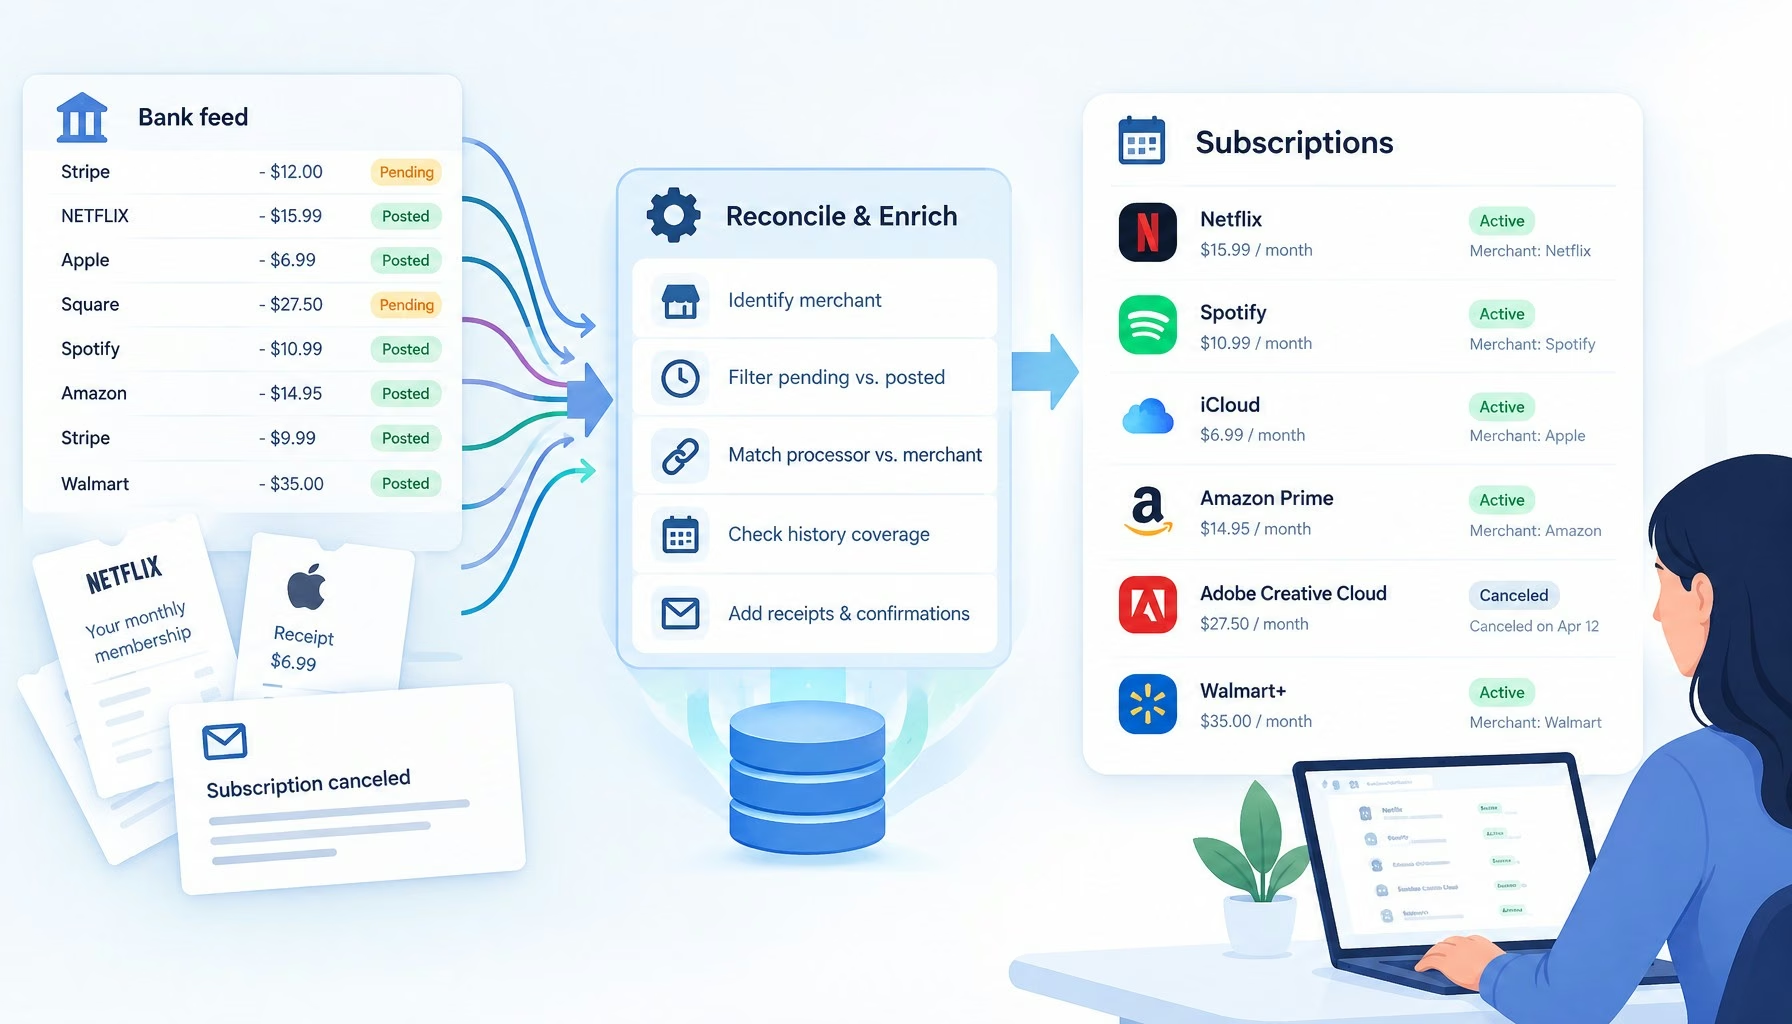
Subscription Trackers Have a Transaction Data Problem
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Is Big Data Failing?
Analytics

Is Big Data Failing?

5 Min Read
Are Public Clouds Complex Environments?
AnalyticsCloud ComputingExclusivePrivacyRisk ManagementSecurity

Are Public Clouds Complex Environments?

4 Min Read
How Big Data and Hadoop Training Programs Can Make a Big Difference
AnalyticsBig DataExclusiveHadoopSoftware

How Big Data and Hadoop Training Programs Can Make a Big Difference

5 Min Read
Map and Reduce in MapReduce: a SAS Illustration
Hadoop

Map and Reduce in MapReduce: a SAS Illustration

3 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive
5 Great Tips for Using Data Analytics for Website UX
Big Data

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?