We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Predictive modeling and today’s growing data challenges
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Business Intelligence > CRM > Predictive modeling and today’s growing data challenges
Business IntelligenceCRMData MiningPredictive Analytics

Predictive modeling and today’s growing data challenges

JamesTaylor
JamesTaylor
5 Min Read
Predictive modeling and today’s growing data challenges
Illustration generated with Qwen Image.
SHARE

Copyright © 2009 James Taylor. Visit the original article at Predictive modeling and today’s growing data challenges.

Syndicated from Smart Data Collective

Matt Kramer of Axciom and Jun Zhong of Wells Fargo discussed some of the challenges presented by data in the context of predictive models. Matt began by discussing some of the reasons for modeling – reducing costs, avoiding simplistic decisioning, predict attritition, optimize marketing spend etc. Predictive models help by ranking based on probabilities.

Creating a suitable modeling sample requires enough records (10,000-15,000) that are recent enough to be relevant (especially when times are changing fast). Axciom’s data shows that 1,200 or more instances of what it is you are trying to predict gives you a robust model. Focusing on mature/complete data is important, however, and this has to be balanced against timeliness. Appending internal or external data can make a big difference to quality of models.These samples must be checked carefully for problems. Sample bias can be damaging, so using a model on data that looks like the sample is key.
More Read

A Cautious Look at Big Data
The SMART Way to Use Big Data for Retail Businesses
Intelligence in the Cloud
CRM Paradigm Shift
The Data Trends Shaping Analytics in 2026: 10 Shifts Worth Funding

Jun discussed some marketing business issues related to data. Their two main challenges are to recognize likely purchasers and then to recognize likely purchasers that will be influenced by an action or treatment – who is proactive (will buy anyway) and who is reactive (who will buy only in response).

Propensity to Purchase models predict who is likely to buy, allowing the offers to be made only to those likely to buy. A second model, Propensity to Influence, predicts how likely someone will be influenced by a specific promotion.

To develop this second model you need to have both a treatment and a control group to see what response you get. This allows you to find the buyers in both groups and then to see what kind of people did not buy in the control group but did buy in the treatment group – these are those who only purchased because of the treatment. From this you can build the propensity to influence model. Building these models requires all the usual data cleansing, transformation, initial and ongoing validation etc.

Matt came back to talk about some challenges he sees. The ability to demonstrate incremental value and to persuade business users that modeling is necessary – that just specifying the rules explicitly would not be as useful. There are also growing restrictions on the use of certain data as a result of legal worries.

  • As other speakers have noted, it is really important to have clean control groups so that comparisons are both real and believable. If you can’t show real business benefits in terms of total value/total cost then the “lift” of the model doesn’t matter. It can be hard for companies to hold people out to keep a really clean control group – want to market to everyone.
  • Criteria – rules-  tend to be easier to understand and implement. Showing the value of the model is critical. Models tend to produce more optimal results and generally does not exclude whole groups but rather ranks them based on weighted attributes. Matt was trying to make it seem like these are either / or but of course they are not – they can and should be used in conjunction. Models can help make decision criteria better.
  • Restrictions on use of certain attributes are designed to prevent discrimination. Not much you can do about this except keep working on the modeling to find other ways to build the model. One example he gave had 55% of attributes removed dropping the lift from 3x to 1.2x. New attributes and more careful segmentation rebuilt the lift somewhat but not completely.

Not much new in this session, sadly.
Previous Next
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article’s core relationship is between growing compute density and adaptable rack hardware that
6 Details That Make a Data Centre’s Server Room Easier to Scale
Best Practices Data Management Exclusive IT
Flat editorial illustration: The article’s core relationship is a transfer of discipline from regulated laboratories to analytics
What Business Intelligence Teams Can Learn from Lab Data Governance
Business Intelligence Exclusive
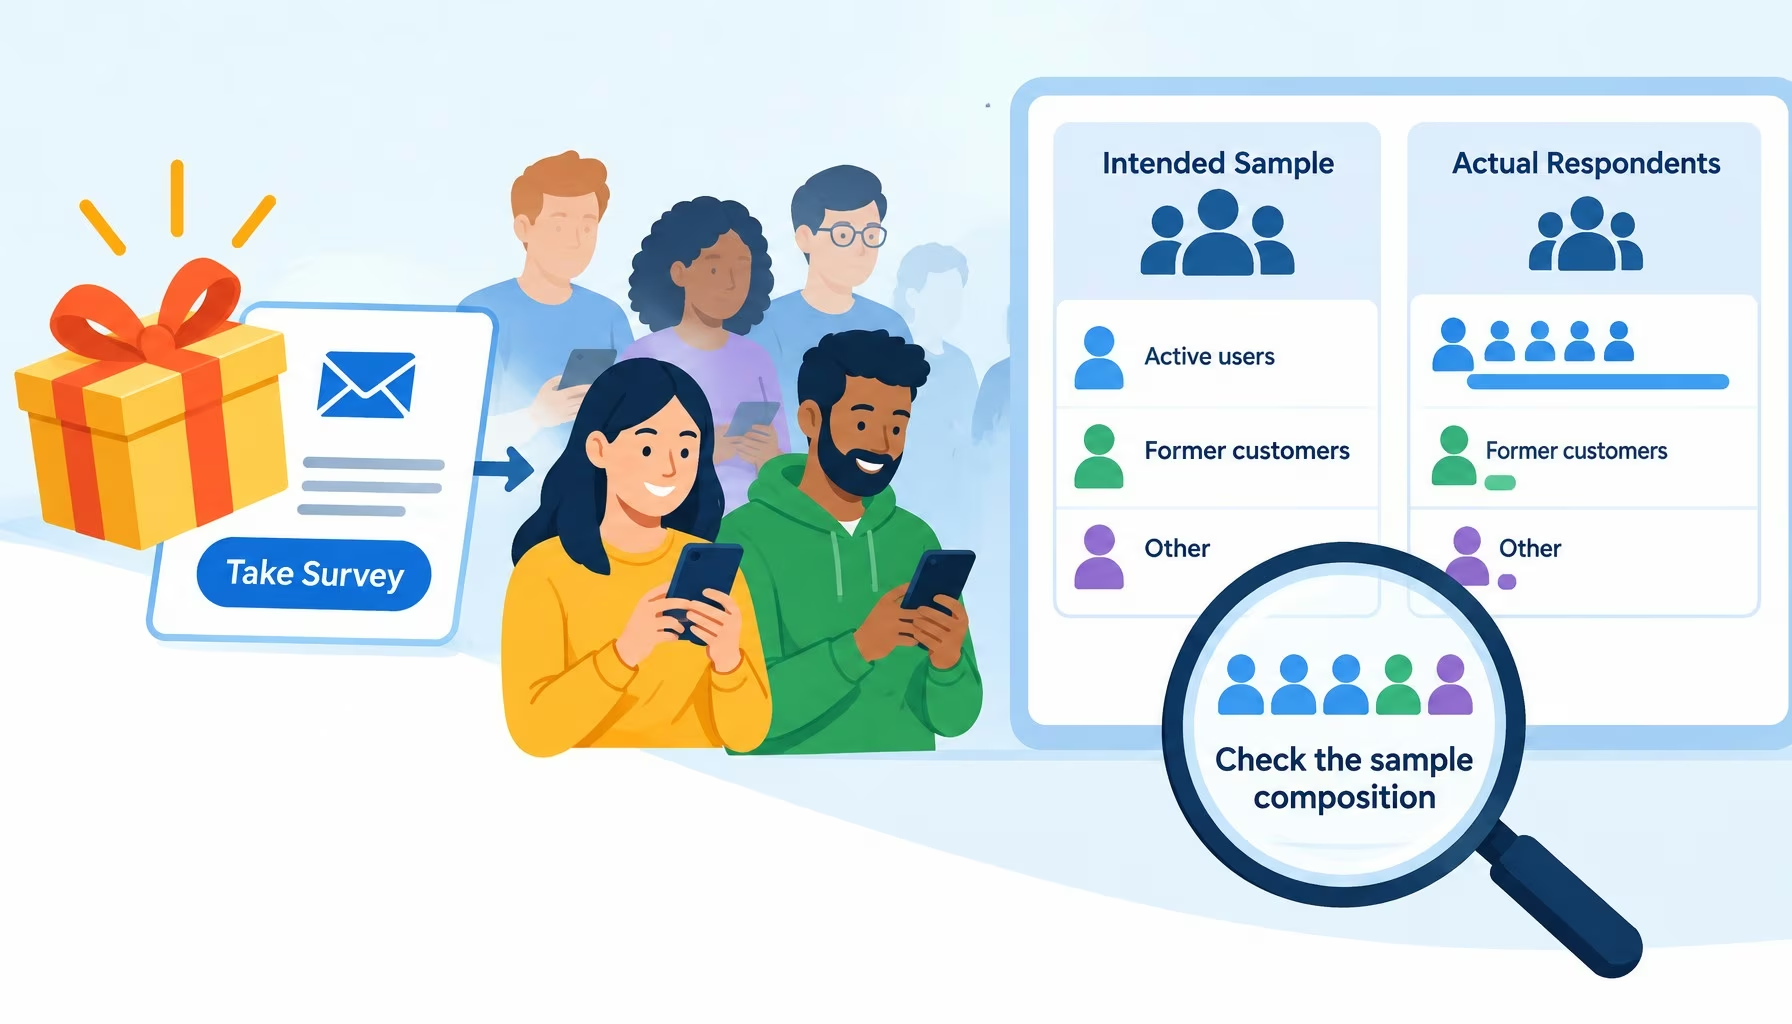
Flat editorial illustration: A guaranteed reward can raise participation while skewing the respondent pool toward active customer
Incentive-Driven Response Bias: Auditing Sample Composition Before You Trust Survey Data
Big Data Data Quality Exclusive
Flat editorial illustration: The article’s core relationship is observable blockchain activity becoming a trustworthy business me
Blockchain Dashboards Need Better Definitions, Not More Charts
Blockchain Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

Because It's the Weekend: Data Mining Wine
Data Mining

Because It’s the Weekend: Data Mining Wine

6 Min Read
Top 8 Big Data Trends That Marketers Should Care About
Big DataBusiness IntelligenceMarketingMarketing AutomationPredictive Analytics

Top 8 Big Data Trends That Marketers Should Care About

11 Min Read
Gaming the Forecast
Best PracticesBusiness Intelligence

Gaming the Forecast

4 Min Read
Is Twitter Killing Blogging?
Data MiningPredictive Analytics

Is Twitter Killing Blogging?

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

Artificial Intelligence for eCommerce: A Closer Look
Artificial Intelligence
5 Great Tips for Using Data Analytics for Website UX
Big Data

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?