
Since data mining began to take hold in the late nineties, “sampling” has become a dirty word in some circles. The Big Data frenzy is compounding this view, leading many to conclude that size equates to predictive power and value. The more data the better, the biggest analysis is the bestest.
Except when it isn’t, which is most of the time.
Data miners have some legitimate reasons for resisting sampling. For starters, the vision of data mining pioneers was empowerment of people who had business knowledge, but not statistical knowledge, to find valuable patterns in their own data and put that information into use. So the intended users of data mining tools are not trained in sampling techniques. Some view sampling as a process step that could be omitted, provided that the data mining tool can run really, really fast. Current data mining tools make sampling quite easy, so this line of resistance has withered quite a lot.
The other significant reason why data miners often choose to use all the data they have, even when they have quite a lot, is that they are looking for extreme cases. They are on a quest in search of the odd and unusual. Not everyone has pressing needs for this, but for those who have, it makes sense to work with a lot of data. For example, in intelligence or security applications, only a few cases out of millions may exhibit behavior indicative of threatening activity. So analysts in those fields have a darned good reason to go whole hog.
It’s mighty odd, though, that many people who have no clear business reason for obsessing over rare cases get their panties wound up in a bunch at the mere mention of sampling. The more that I talk to these outraged investigators, the more I believe that this simply reflects poor grounding in data analysis methods.
To put it bluntly, if you don’t sample, if you don’t trust sampling, if you insist that sampling obscures the really valuable insights, you don’t know your stuff. The best analysts, whether they call themselves analysts, scientists, statisticians or some other name, use sampling routinely. But there are many “gurus” out there spreading misleading information. Don’t buy what they are selling.
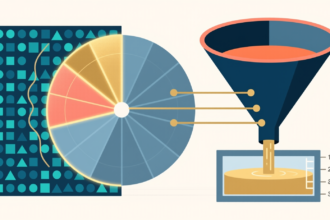
So what is a sample? A sample is small quantity of data.
Small is relative. A poll to predict election outcomes could get by with no more than a couple of thousand respondents, perhaps just a few hundred, to gauge the attitudes of millions of voters. A vial of your blood is sufficient to assess the status of all the blood in your body. Even a massive data source, with millions of millions of rows of data is still just a sample of the data that could potentially be collected from the big, wide world.
How can you know how big a sample you need? Classical statistics has methods for that, you can learn them. Data mining is much less formal, but the gist would be that if what you discover from your sample still holds water when you test on additional data and in the field, it was good enough.
In data analysis, we select samples that are representative of some bigger body of data that interests us. The big body of data does not refer to the data in your repository. In statistical theory, it’s called the “population,” which is more of an idea than a thing. The population means all the cases you want to draw conclusions about. So that may include all the data in your repository, as well as data that has been recorded in some other resources you cannot access. It can also include cases that have taken place, but for which no data was recorded, and even cases which have not yet occurred.
You may have heard the term “random sample.” This means that every case in the population has an equal opportunity to get in the sample. The most fundamental assumption of all statistical analysis is that samples are random (ok, there are variations on that theme, but we’ll save that for another day). In practice, our samples are not perfectly random, but we do our best.
If you use all the data in your Big Data resource, you’re not really avoiding sampling. No doubt you will use your analysis to draw conclusions about future cases – cases that are not in your resource today. So your Big Data is still just a very, very big sample from the population that matters to you.
But, if you have it, why not use it? Why wouldn’t you use all the data available?
More isn’t necessarily better. Analyzing massive quantities of data consumes a lot of resources, in computing power, storage space, in the patience of the analyst. Assuming that the resources are even available, the clock is till ticking, and every minute you are waiting for meaningful analysis is a minute when you don’t have the benefit of information that could be put to use in your business. The resources used for just one analysis involving a massive quantity of data could be sufficient to produce many useful studies if you’d only use smaller samples.
Resources are not the only issue. There’s also the little matter of data quality. Is every case in your repository nice and clean? Are you sure? What makes you sure? How about investigating some of that data very carefully and looking for signs of trouble? Much easier to assure yourself that a modest-sized sample is nicely cleaned up than a whole, whopping repository. Data quality is a whole lot more valuable than data quantity.
You see, ladies and gentlemen of the analytic community, that sampling is not a dirty word. Sampling is a necessary and desirable item in the data analysis toolkit, no matter what type of analysis you require. If you’re not familiar or comfortable with it, change your ways now.
©2012 Meta S. Brown